 AI
Ollama + MLX: Run AI Locally on Mac 3x Faster with Apple Silicon — Complete Guide 2026
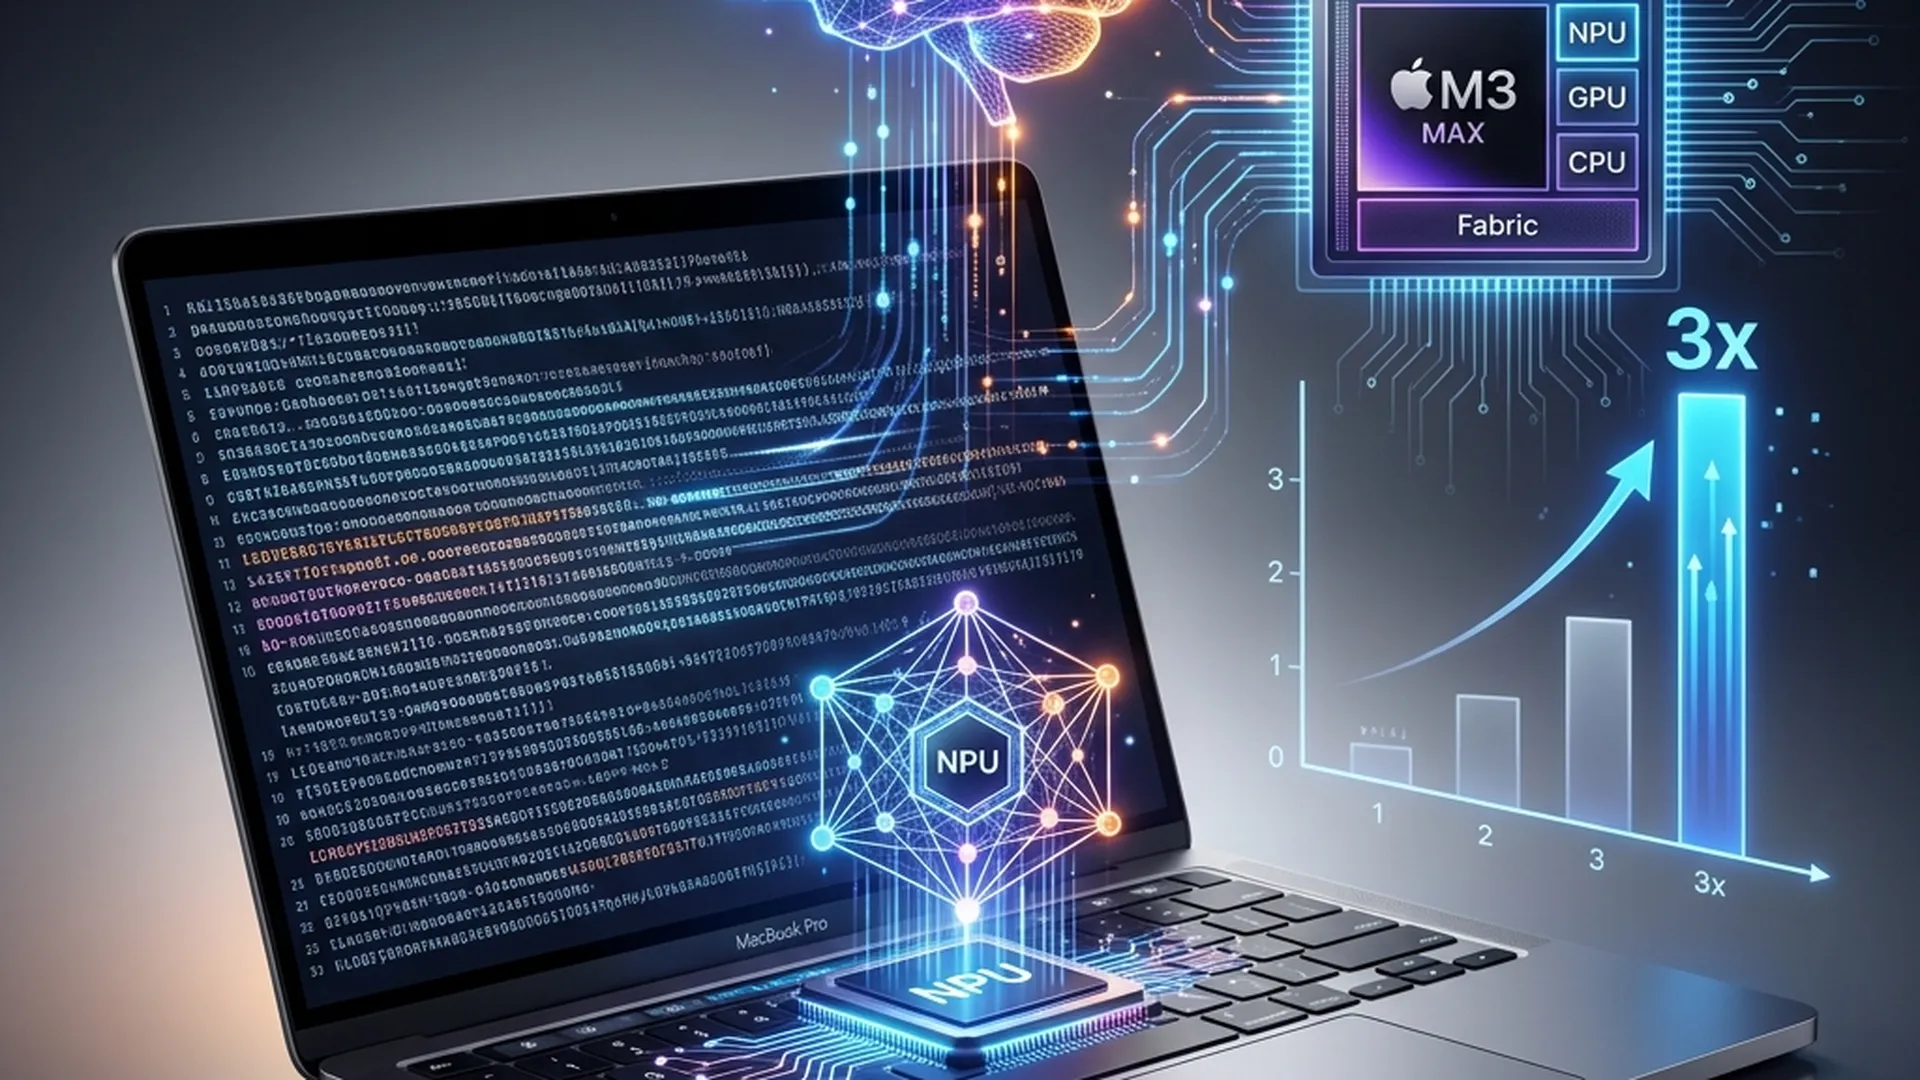
Ollama 0.19 integrates Apple's MLX backend — delivering 93% faster decode speed and 57% faster prefill on M5. A comprehensive technical analysis of unified memory architecture, real-world benchmarks across M1 to M5, and a step-by-step setup guide to maximize your Apple Silicon's potential.
 Duy Tran18 min