Series Introduction
This series is for developers who can already run LLMs locally at a basic level and want to level up to real engineering: with clear architecture, stable APIs, reliable RAG, quality metrics, and a rollout checklist.
You won't learn through quick demos. Each lesson is anchored to the real-world requirements of a local AI stack used by an internal team.
What You'll Learn
- Design a local-first architecture for AI products
- Build a Gemma 4 stack on Mac to dev team standards
- Create an API gateway, prompt contracts, and output schemas
- Build a Vietnamese-language RAG pipeline from ingestion to hybrid retrieval
- Measure quality with an eval framework and operational observability
- Harden the system before internal deployment
Prerequisites
- Mac with Apple Silicon (M1 or later), 24GB+ RAM recommended
- Basic familiarity with Terminal and Git
- Basic Python or TypeScript knowledge
- Understanding of APIs, JSON, and HTTP
Source Code
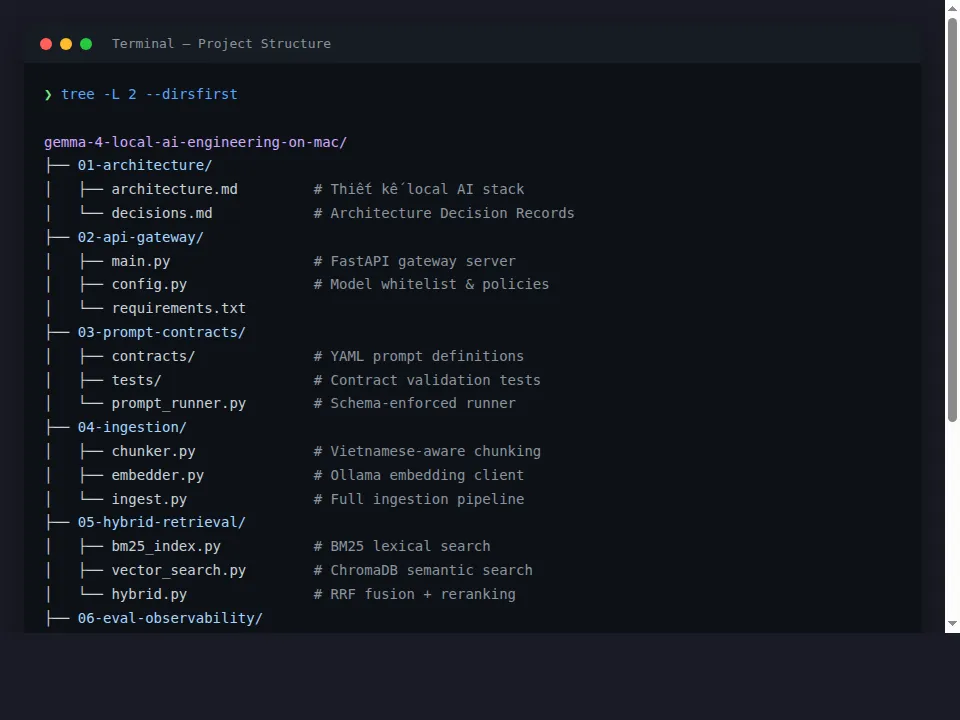
All demo code accompanying this series:
Outcome After This Series
After completing this series, you'll be able to build a mini local AI platform for your team:
- A chat UI for non-technical users
- An API for internal applications
- RAG with citations and stable quality
- Monitoring and a controlled release process