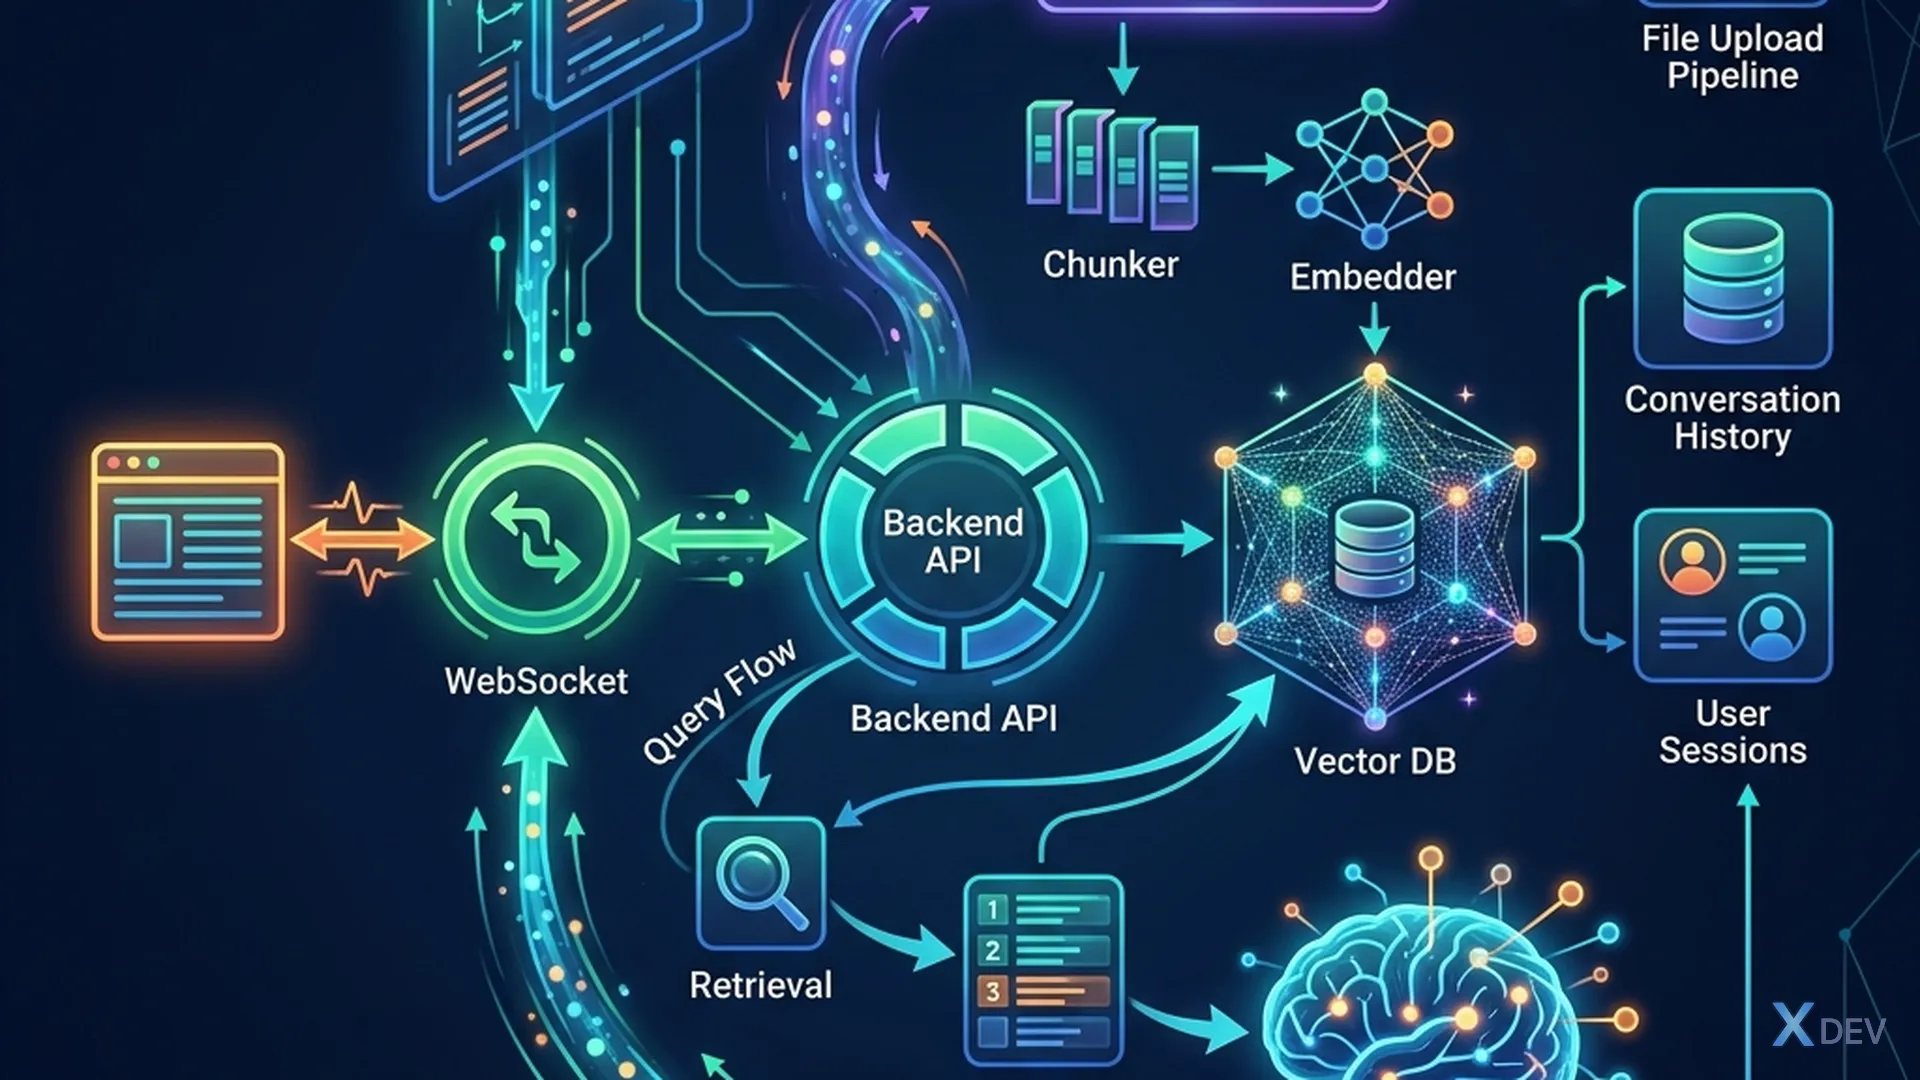
簡介
這是最後一課 — 您將從頭到尾建立 使用文件聊天,整合之前 13 課中的所有知識。最終產品:允許上傳文件→聊天提問和回答→回覆來源引用的網路應用程式。
目標產品: 上傳 PDF/DOCX → 自分塊+索引 → 問答聊天 → 擷取原始碼(頁面、段落)→ 聊天記錄 → 評估指標。
1. 架構概述
1.1 系統架構
┌─────────────────────────────────────────────────┐
│                    Frontend                      │
│  ┌────────────┐  ┌──────────────┐  ┌──────────┐ │
│  │ Upload UI  │  │ Chat Window  │  │ Settings │ │
│  └──────┬─────┘  └──────┬───────┘  └──────────┘ │
│         │               │                        │
└─────────┼───────────────┼────────────────────────┘
          │               │
     ┌────┴────┐    ┌─────┴─────┐
     │ /upload │    │  /query   │
     └────┬────┘    └─────┬─────┘
          │               │
┌─────────┼───────────────┼────────────────────────┐
│         │          FastAPI                        │
│  ┌──────┴──────┐   ┌───┴───────────┐             │
│  │  Document   │   │  RAG Pipeline │             │
│  │  Processor  │   │               │             │
│  │ ┌─────────┐ │   │  Query        │  ┌───────┐  │
│  │ │ Loader  │ │   │  Transform    │  │ Redis │  │
│  │ │ Chunker │ │   │  → Retrieve   │  │ Cache │  │
│  │ │ Embedder│ │   │  → Rerank     │  └───────┘  │
│  │ └─────────┘ │   │  → Compress   │             │
│  └──────┬──────┘   │  → Generate   │             │
│         │          └───┬───────────┘              │
│  ┌──────┴──────┐      │                          │
│  │  Pinecone / │◄─────┘                          │
│  │  Chroma     │                                  │
│  └─────────────┘                                  │
└──────────────────────────────────────────────────┘
1.2 技術堆疊
| 組件 | 技術 | 原因 |
|---|---|---|
| 後端 | 快速API | 非同步、串流、類型安全 |
| 法學碩士 | GPT-4o-迷你 | 性價比高,速度快 |
| 嵌入 | 文字嵌入-3-小 | 便宜、有效 |
| 向量商店 | Chroma (開發) / Pinecone (產品) | Chroma 易於設置,Pinecone 可擴展 |
| 快取 | Redis | 語意快取 |
| 前端 | Streamlit / Next.js | Streamlit / Next.js |
| 監控 | 蘭史密斯 | 追蹤、評估 |
2.文檔處理模組
2.1 多格式載入器
"""Document processor: PDF, DOCX, TXT, MD, CSV"""
from pathlib import Path
from langchain_community.document_loaders import (
    PyPDFLoader, Docx2txtLoader, TextLoader,
    UnstructuredMarkdownLoader, CSVLoader,
)
from langchain.text_splitter import RecursiveCharacterTextSplitter
from langchain_openai import OpenAIEmbeddings

LOADERS = {
    ".pdf": PyPDFLoader,
    ".docx": Docx2txtLoader,
    ".txt": TextLoader,
    ".md": UnstructuredMarkdownLoader,
    ".csv": CSVLoader,
}

def process_document(file_path: str, collection_name: str):
    """Load → Chunk → Embed → Index"""
    ext = Path(file_path).suffix.lower()

    if ext not in LOADERS:
        raise ValueError(f"Unsupported format: {ext}")

    # 1. Load
    loader = LOADERS[ext](file_path)
    documents = loader.load()

    # 2. Add metadata
    for doc in documents:
        doc.metadata.update({
            "source": Path(file_path).name,
            "file_type": ext,
            "collection": collection_name,
        })

    # 3. Chunk (recursive, best for most cases)
    splitter = RecursiveCharacterTextSplitter(
        chunk_size=500,
        chunk_overlap=50,
        separators=["\n\n", "\n", ". ", " ", ""],
    )
    chunks = splitter.split_documents(documents)

    # 4. Index
    from langchain_community.vectorstores import Chroma
    vectorstore = Chroma.from_documents(
        chunks,
        OpenAIEmbeddings(model="text-embedding-3-small"),
        collection_name=collection_name,
        persist_directory="./chroma_db",
    )

    return {"chunks": len(chunks), "pages": len(documents)}
2.2 上傳API
"""Upload endpoint"""
from fastapi import UploadFile, File
import shutil, os

UPLOAD_DIR = "./uploads"
os.makedirs(UPLOAD_DIR, exist_ok=True)

@app.post("/upload")
async def upload_document(
    file: UploadFile = File(...),
    collection: str = "default",
):
    # Save file
    file_path = os.path.join(UPLOAD_DIR, file.filename)
    with open(file_path, "wb") as f:
        shutil.copyfileobj(file.file, f)

    # Process
    result = process_document(file_path, collection)

    return {
        "filename": file.filename,
        "chunks_created": result["chunks"],
        "pages_processed": result["pages"],
    }
3. RAG 管道模組
3.1 進階檢索管道
"""Full RAG pipeline: multi-query → hybrid → rerank → compress"""
from langchain.retrievers import (
    MultiQueryRetriever,
    ContextualCompressionRetriever,
    EnsembleRetriever,
)
from langchain.retrievers.document_compressors import CrossEncoderReranker
from langchain_community.retrievers import BM25Retriever
from langchain_community.cross_encoders import HuggingFaceCrossEncoder

def create_rag_pipeline(collection_name: str):
    # Vector retriever
    vectorstore = Chroma(
        collection_name=collection_name,
        persist_directory="./chroma_db",
        embedding_function=OpenAIEmbeddings(),
    )
    vector_retriever = vectorstore.as_retriever(search_kwargs={"k": 10})

    # BM25 retriever
    all_docs = vectorstore.get()  # Lấy tất cả docs cho BM25
    from langchain.schema import Document
    bm25_docs = [Document(page_content=text) for text in all_docs["documents"]]
    bm25_retriever = BM25Retriever.from_documents(bm25_docs, k=10)

    # Hybrid (ensemble)
    hybrid_retriever = EnsembleRetriever(
        retrievers=[vector_retriever, bm25_retriever],
        weights=[0.6, 0.4],
    )

    # Multi-query
    multi_query = MultiQueryRetriever.from_llm(
        retriever=hybrid_retriever,
        llm=ChatOpenAI(model="gpt-4o-mini", temperature=0.3),
    )

    # Reranker
    reranker = CrossEncoderReranker(
        model=HuggingFaceCrossEncoder(model_name="cross-encoder/ms-marco-MiniLM-L-6-v2"),
        top_n=5,
    )

    # Final pipeline: multi-query → rerank
    final_retriever = ContextualCompressionRetriever(
        base_compressor=reranker,
        base_retriever=multi_query,
    )

    return final_retriever
3.2 帶引用的生成
"""Generate answer với trích nguồn"""
def generate_answer(question: str, docs, llm):
    # Format context với source markers
    context_parts = []
    for i, doc in enumerate(docs):
        source = doc.metadata.get("source", "Unknown")
        page = doc.metadata.get("page", "?")
        context_parts.append(f"[{i+1}] (Nguồn: {source}, trang {page})\n{doc.page_content}")

    context = "\n\n".join(context_parts)

    prompt = f"""Dựa trên context sau, trả lời câu hỏi bằng tiếng Việt.
Trích nguồn [số] khi sử dụng thông tin.
Nếu không tìm thấy, nói rõ.

Context:
{context}

Câu hỏi: {question}

Trả lời (kèm trích nguồn):"""

    return llm.invoke(prompt).content
    # Output: "Nhân viên full-time được 15 ngày phép/năm [1].
    #          Nhân viên trên 5 năm được thêm 3 ngày [2]."
4.聊天記錄
4.1 對話記憶
"""Lưu và sử dụng chat history"""
from collections import defaultdict

# In-memory history (production: dùng Redis hoặc DB)
chat_histories = defaultdict(list)

def query_with_history(question: str, session_id: str, retriever, llm):
    history = chat_histories[session_id]

    # Contextualize: kết hợp history + question mới
    if history:
        history_text = "\n".join([
            f"User: {h['question']}\nAI: {h['answer']}"
            for h in history[-3:]  # 3 tin nhắn gần nhất
        ])
        contextualized_q = llm.invoke(
            f"Lịch sử chat:\n{history_text}\n\n"
            f"Câu hỏi mới: {question}\n\n"
            f"Viết lại câu hỏi mới sao cho đầy đủ ngữ cảnh (standalone):"
        ).content
    else:
        contextualized_q = question

    # Retrieve + Generate
    docs = retriever.invoke(contextualized_q)
    answer = generate_answer(contextualized_q, docs, llm)

    # Save to history
    chat_histories[session_id].append({
        "question": question,
        "answer": answer,
    })

    return answer
5. 前端(Streamlit)
5.1 聊天介面
"""Streamlit chat UI"""
import streamlit as st
import requests

st.title("💬 Chat with Documents")

# Sidebar: upload
with st.sidebar:
    st.header("📄 Upload Documents")
    uploaded = st.file_uploader("Chọn file", type=["pdf", "docx", "txt"])
    if uploaded and st.button("Upload & Index"):
        files = {"file": (uploaded.name, uploaded.getvalue())}
        resp = requests.post("http://localhost:8000/upload", files=files)
        st.success(f"Đã index {resp.json()['chunks_created']} chunks!")

# Chat interface
if "messages" not in st.session_state:
    st.session_state.messages = []

for msg in st.session_state.messages:
    with st.chat_message(msg["role"]):
        st.write(msg["content"])

if prompt := st.chat_input("Hỏi gì về tài liệu?"):
    st.session_state.messages.append({"role": "user", "content": prompt})

    with st.chat_message("assistant"):
        resp = requests.post("http://localhost:8000/query",
            json={"question": prompt})
        data = resp.json()
        st.write(data["answer"])

        with st.expander("📎 Nguồn tham khảo"):
            for src in data["sources"]:
                st.write(f"- {src['source']}: {src['content'][:150]}...")

    st.session_state.messages.append({"role": "assistant", "content": data["answer"]})
6. 評估與測試
6.1 為專案建立黃金測試集
"""Golden test set cho capstone project"""
golden_test = [
    {
        "question": "Nghỉ phép bao nhiêu ngày?",
        "ground_truth": "15 ngày cho full-time, 8 ngày cho part-time",
        "category": "simple",
    },
    {
        "question": "So sánh chính sách nghỉ phép với luật lao động",
        "ground_truth": "Công ty cho 15 ngày, cao hơn luật quy định 12 ngày",
        "category": "reasoning",
    },
    # ... 48 câu nữa
]
總結
| 模組 | 應用知識 |
|---|---|
| 文件處理 | 第 3-5 課:裝載機、分塊 |
| 元資料與索引 | 第 6 課:元資料、混合搜尋 |
| 查詢轉換 | 第 7 課:多重查詢,HyDE |
| 檢索 | 第 8 課:重新排序、壓縮 |
| 高級 | 第 9-11 課:圖形、多模式、代理 |
| 評估 | 第 12 課:RAGAS,黃金測驗 |
| 生產 | 第 13 課:API、快取、監控 |
頂點練習
強制性要求:
- 上傳: 支援至少3種格式(PDF、DOCX、TXT)
- 分塊: RecursiveCharacterTextSplitter + 元數據
- 搜尋: 混合搜尋(向量+BM25)+重新排名
- 聊天: 串流回覆+聊天記錄
- 引文: 引文源文件+頁碼
增強要求(獎勵):
- 多模式: 從 PDF 擷取表格/影像
- 語意緩存: Redis語意緩存
- Guardrails: 輸入/輸出驗證
- 評估: RAGAS 指標在 20 個問題的黃金測驗中 > 0.8
- 部署: Docker Compose(API + Redis + Chroma + Streamlit)
評級:
| 標準 | 重量 |
|---|---|
| 功能正常 | 40% |
| 程式碼品質 | 20% |
| RAG 品質(RAGAS 指標) | 25% |
| 使用者介面/使用者體驗 | 15% |
**恭喜! ** 您已完成《RAG 實戰:從基礎到進階》系列。繼續針對實際用例練習並建立 RAG 產品!