The Eunomia sample CDM holds 2,700 people. A real CDM can hold 1-100 million. The technical gap is huge. This article distills production best practices for Postgres OMOP CDM at Vietnam scale.
1. Hardware sizing
| Scale | vCPU | RAM | SSD | RAM:data ratio |
|---|---|---|---|---|
| Dev (Eunomia) | 4 | 16 GB | 100 GB | n/a |
| 100K patients | 8 | 32 GB | 500 GB | 1:5 |
| 1M patients | 16 | 64 GB | 2 TB | 1:8 |
| 10M patients | 32 | 256 GB | 10 TB | 1:10 |
| 100M patients (BHYT scale) | 64+ | 512 GB+ | 50 TB+ | 1:15 |
Storage layout:
pg_data: NVMe SSD RAID 10pg_wal: dedicated SSD (low latency)pg_temp: dedicated SSD (sort/hash join spill)
2. PostgreSQL config
# postgresql.conf for 64GB RAM
shared_buffers = 16GB              # 25% RAM
effective_cache_size = 48GB         # 75% RAM
work_mem = 256MB                    # per query, watch concurrency
maintenance_work_mem = 4GB
wal_buffers = 64MB
max_wal_size = 16GB
min_wal_size = 4GB
checkpoint_timeout = 30min
default_statistics_target = 500     # higher because OMOP is skew-heavy
random_page_cost = 1.1              # SSD
effective_io_concurrency = 200      # NVMe SSD
max_parallel_workers_per_gather = 4
max_parallel_workers = 16
jit = on                            # PG12+ helps analytics
Note: work_mem × concurrent connections can exceed RAM → use pgBouncer transaction pooling, cap at ~50 connections.
3. Indexing strategy
OHDSI publishes the standard DDL: OMOPCDM_postgresql_5.4_indices.sql. Add workload-specific indexes:
-- Hottest tables: condition_occurrence, drug_exposure, measurement
CREATE INDEX idx_co_person ON condition_occurrence(person_id);
CREATE INDEX idx_co_concept ON condition_occurrence(condition_concept_id);
CREATE INDEX idx_co_date ON condition_occurrence USING BRIN(condition_start_date);  -- BRIN for time-series

CREATE INDEX idx_co_concept_date ON condition_occurrence(condition_concept_id, condition_start_date);

-- Vocabulary
CREATE INDEX idx_concept_std ON concept(standard_concept) WHERE standard_concept = 'S';
CREATE INDEX idx_ca_anc_desc ON concept_ancestor(ancestor_concept_id, descendant_concept_id);

-- Cohort
CREATE INDEX idx_cohort_id_person ON cohort(cohort_definition_id, subject_id);

-- Partial statistics
ALTER TABLE condition_occurrence ALTER COLUMN condition_concept_id SET STATISTICS 1000;
ANALYZE condition_occurrence;
4. Partitioning for large datasets
CREATE TABLE condition_occurrence (
  ...
) PARTITION BY RANGE (condition_start_date);

CREATE TABLE condition_occurrence_2026
  PARTITION OF condition_occurrence
  FOR VALUES FROM ('2026-01-01') TO ('2027-01-01');

CREATE INDEX idx_co_2026_person ON condition_occurrence_2026(person_id);
Benefits:
- Date-based pruning → queries 10× faster
- Dropping old partitions is instant (5-year data retention)
- Parallel maintenance (VACUUM, REINDEX)
Alternative: HASH-partition on person_id for cohort queries that span many dates.
5. Vacuum and bloat
OMOP sees lots of UPDATE/DELETE during re-ETL → significant bloat.
-- Auto vacuum tuning
ALTER TABLE condition_occurrence SET (
  autovacuum_vacuum_scale_factor = 0.05,
  autovacuum_analyze_scale_factor = 0.02,
  fillfactor = 90
);

-- Manual for big operations
VACUUM ANALYZE condition_occurrence;
REINDEX TABLE CONCURRENTLY condition_occurrence;
Monitor bloat:
SELECT schemaname, relname, n_dead_tup, n_live_tup,
       round(n_dead_tup::numeric / NULLIF(n_live_tup, 0), 3) AS dead_ratio
FROM pg_stat_user_tables
WHERE n_dead_tup > 1000
ORDER BY dead_ratio DESC;
6. Backup & DR
2026 pattern:
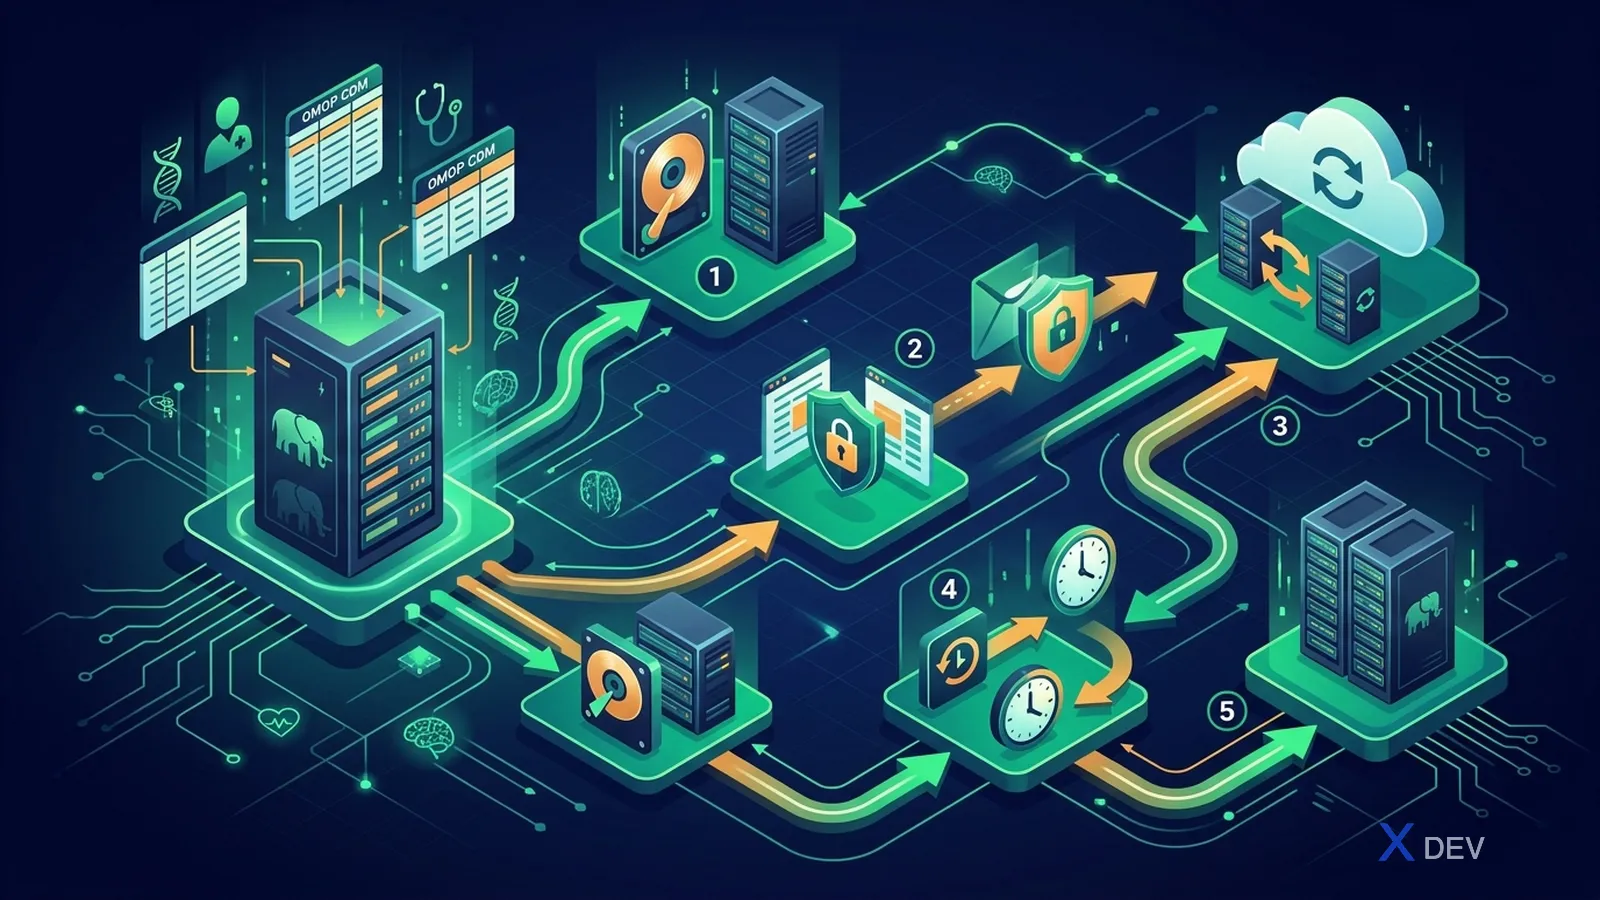
- Streaming replication to one standby in the same DC (failover < 30s)
- Async replication to a DR site
- pgBackRest weekly full + daily incremental + continuous WAL → S3
- RPO 5 min, RTO < 1h
Vietnam: healthcare data is sensitive personal data under the Vietnam Personal Data Protection Law 2025 (effective Jan 1, 2026, replacing Decree 13/2023) — it must be stored in-country, not in foreign-region S3 buckets. Use Vietnamese object storage: VNG Cloud, Viettel IDC, FPT Cloud, CMC Cloud (all certified for the new law).
7. Security under the Personal Data Protection Law 2025
2026 legal update: The Personal Data Protection Law (passed by the National Assembly in June 2025, effective Jan 1, 2026) replaces and upgrades Decree 13/2023/NĐ-CP, combined with Medical Examination and Treatment Law No. 15/2023/QH15 (effective Jan 1, 2024) — which regulates the storage of medical records and electronic health records.
Key requirements for healthcare data:
- Encryption at rest and in transit
- Audit log every PII/PHI access
- Pseudonymize national ID / BHYT
- Store in-country
- A DPO (Data Protection Officer) is accountable
- Periodic risk assessments
7.1 Encryption
# postgresql.conf
ssl = on
ssl_cert_file = '/etc/ssl/certs/postgres.crt'
ssl_key_file = '/etc/ssl/private/postgres.key'
ssl_ciphers = 'HIGH:!aNULL:!MD5'
At-rest: use LUKS / ZFS encryption / TDE (Postgres 18 native).
7.2 Pseudonymize person_source_value
-- Never store raw national ID
person_source_value = encode(
  hmac(cccd::bytea, current_setting('app.pseudonym_secret')::bytea, 'sha256'),
  'hex'
);
Keep the key in a separate Vault / KMS.
7.3 Row-level security
ALTER TABLE person ENABLE ROW LEVEL SECURITY;

CREATE POLICY person_policy ON person
  FOR SELECT
  TO research_user
  USING (location_id IN (
    SELECT location_id FROM user_location_access
    WHERE user_id = current_user
  ));
7.4 Audit log
-- pg_audit extension
CREATE EXTENSION pgaudit;
ALTER SYSTEM SET pgaudit.log = 'read,write,role,ddl';
Ship logs to a SIEM (Wazuh, Elasticsearch).
8. User & role pattern
-- Role separation
CREATE ROLE omop_owner;            -- DDL, ETL
CREATE ROLE omop_etl LOGIN;        -- ETL service account
CREATE ROLE omop_analyst LOGIN;    -- HADES, analytics
CREATE ROLE omop_atlas_webapi LOGIN;  -- WebAPI service
CREATE ROLE omop_readonly_external LOGIN;  -- DARWIN EU partner

-- Grants
GRANT USAGE ON SCHEMA cdm TO omop_analyst, omop_atlas_webapi;
GRANT SELECT ON ALL TABLES IN SCHEMA cdm TO omop_analyst, omop_atlas_webapi;

-- Cohort schema is writable
GRANT INSERT, UPDATE, DELETE ON ALL TABLES IN SCHEMA results TO omop_atlas_webapi;
9. Vocabulary upgrade workflow
Cadence: quarterly. Keep a version log:
CREATE TABLE vocabulary_history (
  id SERIAL,
  vocabulary_version TEXT,
  installed_at TIMESTAMP,
  installed_by TEXT,
  rollback_available BOOLEAN
);
10. Monitoring stack
| Layer | Tool |
|---|---|
| Postgres metrics | pg_stat_statements + Postgres Exporter + Prometheus + Grafana |
| Slow queries | Top 100 from pg_stat_statements |
| Locks | pg_locks query, alert on idle_in_transaction > 10 min |
| Replica lag | streaming_lag query |
| ETL jobs | Airflow / Prefect dashboard |
| DQD trend | Scheduled weekly DQD + Grafana panel for pct_failed |
| Security | SIEM alerts on role escalation, mass SELECT count |
11. Capacity planning
| Component | Growth indicator |
|---|---|
condition_occurrence | ~3-5 rows / patient / month |
drug_exposure | ~5-10 / patient / month |
measurement | ~10-20 / patient / month (lab + vital) |
| Vocabulary | +500 MB / quarterly upgrade |
| Cohort tables | +50 MB / cohort generation |
| Audit logs | 100 MB-1 GB / day depending on traffic |
Plan disk for a 3-5-year horizon.
12. Kubernetes / managed Postgres?
Options:
- Bare-metal Postgres: best control, lowest cost, heavy ops
- Patroni + etcd cluster: self-built HA
- CloudNativePG / Zalando on K8s: modern, scales well
- Managed: AWS RDS / GCP Cloud SQL / Azure Database — Vietnam: Viettel IDC PaaS Postgres, VNG Cloud Database
For large-scale OMOP, bare metal or CloudNativePG remain the highest-performing options.
13. CI/CD for schema migrations
# Liquibase / Flyway instead of raw SQL
flyway migrate -url=jdbc:postgresql://... -user=... -password=...
Each migration carries a version + script + rollback.
Vocabulary changes belong in their own workflow (they're not schema migrations).
14. Lessons learned
- Partitioning condition/drug/measurement by year speeds queries up 5-10×
- BRIN indexes on date columns save disk
- pgBouncer transaction pooling is mandatory above ~50 concurrent connections
- Aggressive vacuum on hot tables avoids bloat
- Vault keeps secrets out of Postgres config
- Test backup restore quarterly — an untested backup is no backup
- Vocabulary upgrades cause 1-2h outages without a schema swap
Conclusion
Production OMOP demands Postgres + DevOps + security skills. Investing properly from day one lets you scale to 100M+ events with no refactor. In Vietnam specifically, security must follow the Personal Data Protection Law 2025 (effective Jan 1, 2026) and Medical Examination and Treatment Law 15/2023 — pseudonymize, audit, store in-country, mandatory DPO, and DPIA for every research project.
Next: FHIR ↔ OMOP — bridging the operational and analytics layers.