Introduction
High Availability (HA) is an essential requirement for any database system in a production environment. However, deploying a PostgreSQL HA cluster from scratch often requires a lot of research time, is prone to errors during manual configuration, and is difficult to maintain consistency across environments.
This article shares our experience in developing a complete automation solution using Ansible that helps deploy PostgreSQL HA clusters quickly and reliably. After successful use in production, we decided to open-source this solution to the community.
Repository: postgres-patroni-etcd-install
Key Features
Automation & Deployment
- Automatically deploy an entire cluster with a single command
- Configuration as Code with over 70 centrally managed environment variables
- Multi-environment support (development, staging, production)
High Availability
- Auto-failover with Patroni (conversion time 30-45 seconds)
- Streaming replication with PostgreSQL 18.1
- Automatically restore failed nodes with pg_rewind
Performance & Scalability
- Connection pooling with PgBouncer (multiplexing ratio 13:1)
- Supports load balancing for read queries
- Optimized for systems with RAM from 16GB to 64GB+
DevOps Integration
- CI/CD pipeline with GitHub Actions
- Automated testing and validation
- Integrated security scanning
Context and Development Dynamics
Practical Issues
During production operations, we experienced a serious incident when the PostgreSQL server experienced a hardware error at 2 am. As a result, the entire application stopped working, and it took 45 minutes to restore from backup. This incident not only caused loss in revenue but also affected reputation and customer trust.
Challenges When Implementing HA
After the incident, we decided to implement a High Availability solution. However, manual configuration faces many difficulties:
High complexity: Need a deep understanding of PostgreSQL replication, Patroni, etcd, and the interactions between them. The research and configuration process takes 2-3 days for an experienced engineer.
Risk of errors: Manual configuration easily leads to inconsistency between nodes, causing problems that are difficult to debug. A small mistake in the config file can cause the entire cluster to not function properly.
Difficult to maintain: When needing to update configuration or scale cluster, it must be done manually on each node, which is time-consuming and error-prone.
Lack of documentation: There is no detailed documentation about the setup process, making it difficult for new onboard engineers to join the project.
Solution
We have developed a set of Ansible playbooks to solve the above problems:
Infrastructure as Code: All configurations are version controlled, easy to review and rollback when needed.
Repeatable Deployment: Can deploy identical cluster on many different environments (dev, staging, production) just by changing files .env.
Self-documenting: Ansible code is clear, accompanied by a detailed README, making it easy for new teams to understand and use.
CI/CD Integration: Automatically validate configuration before deploying, minimizing the risk of errors.
After successfully using it in production for over 6 months, we decided to open-source this solution to share with the community.
System Architecture
Tech Stack
The solution uses proven technologies in the community:
| Component | Version | Role |
|---|---|---|
| PostgreSQL | 18.1 | Main database engine |
| Patroni | 4.1.0 | HA orchestration and automatic failover |
| etcd | 3.5.25 | Distributed configuration store |
| PgBouncer | 1.25.0 | Connection pooling layer |
| Ansible | 2.12+ | Infrastructure automation |
General Architecture
┌─────────────────────────────────────┐
│       Application Layer             │
│  (Spring Boot / Django / Node.js)   │
└──────────────┬──────────────────────┘
               │ Port 6432 (PgBouncer)
        ┌──────┴──────┬──────────┐
        ▼             ▼          ▼
   ┌────────┐    ┌────────┐   ┌────────┐
   │PgBouncer│   │PgBouncer│  │PgBouncer│
   │Node 1   │   │Node 2   │  │Node 3   │
   └────┬───┘    └────┬───┘   └────┬───┘
        │ Port 5432   │             │
   ┌────▼────┐   ┌───▼────┐   ┌────▼────┐
   │PostgreSQL│  │PostgreSQL│ │PostgreSQL│
   │ PRIMARY │  │ REPLICA  │ │ REPLICA  │
   │Read/Write│  │Read Only│ │Read Only │
   └────┬────┘   └────┬────┘  └────┬────┘
        │ Port 8008   │             │
   ┌────▼────┐   ┌────▼────┐  ┌────▼────┐
   │ Patroni │   │ Patroni │  │ Patroni │
   │HA Mgr   │   │HA Mgr   │  │ HA Mgr  │
   └────┬────┘   └────┬────┘  └────┬────┘
        │ Port 2379   │             │
        └──────┬──────┴─────────────┘
               ▼
        ┌──────────────────┐
        │   etcd Cluster   │
        │ (Leader Election)│
        └──────────────────┘
Explanation of Ingredients
PgBouncer Layer: Deployed on each node to provide connection pooling. Applications can connect to any node, reducing single point of failure and network latency.
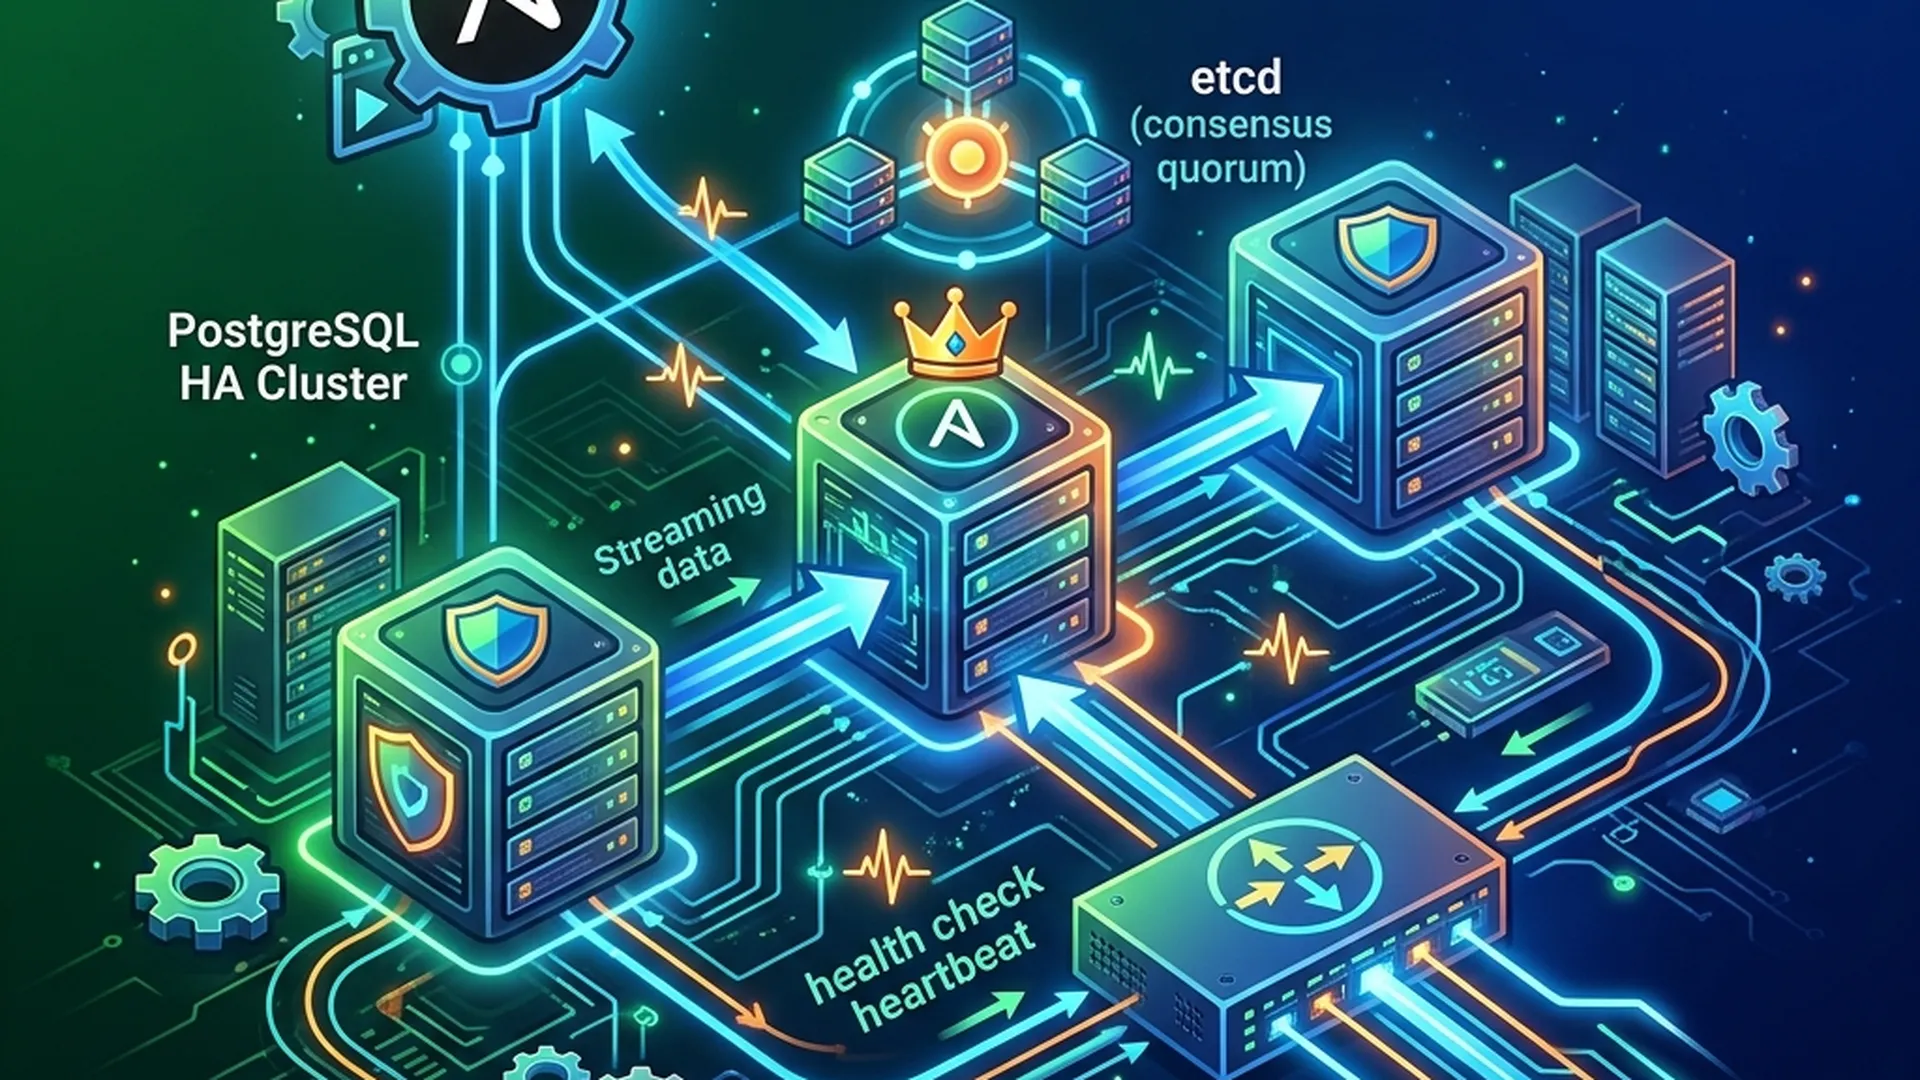
PostgreSQL Cluster: Use streaming replication with one primary node (read/write) and two replica nodes (read-only). Patroni manages the entire lifecycle of the cluster.
Patroni: Act as HA orchestrator, perform continuous health checks, automatically failover when the primary fails, and ensure data consistency through distributed consensus.
etcd Cluster: Store cluster configuration and perform leader election. Ensure there is only one primary node at a time, avoiding split-brain scenarios.
Why 3 Nodes?
The number of 3 nodes is the minimum for an HA cluster due to:
- Quorum: etcd needs at least 3 nodes to achieve quorum (2/3) and tolerates 1 node failure
- Cost effective: Enough to ensure HA without spending too much on infrastructure
- Proven patterns: Is the number of standards recommended by the PostgreSQL and etcd community
Implementation Guide
System Requirements
Hardware (per node)
Minimum for lab/development environment:
- CPU: 2 cores
- RAM: 4 GB
- Disk: 20 GB (OS) + 20 GB (Data)
- Network: 1 Gbps
Recommended for production:
- CPU: 4-8 cores
- RAM: 16-32 GB
- Disk: 50 GB SSD (OS) + 100+ GB NVMe SSD (Data)
- Network: 10 Gbps
Software
Control node (machine running Ansible):
- Ansible >= 2.12
- Python >= 3.9
Target nodes:
- Ubuntu 22.04 LTS / Debian 12 / Rocky Linux 9
- SSH access with root or sudo privileges
- Python 3.x installed
Implementation Steps
Step 1: Prepare Repository
git clone https://github.com/xdev-asia-labs/postgres-patroni-etcd-install.git
cd postgres-patroni-etcd-install
Step 2: Configure Environment
Create configuration file from template:
cp .env.example .env
Edit important parameters:
# Địa chỉ IP của các nodes NODE1_IP=10.0.0.11 NODE2_IP=10.0.0.12 NODE3_IP=10.0.0.13Mật khẩu PostgreSQL (bắt buộc phải thay đổi)
POSTGRESQL_SUPERUSER_PASSWORD=your_strong_password_here POSTGRESQL_REPLICATION_PASSWORD=your_replication_password_here
Performance tuning (ví dụ cho server 16GB RAM)
POSTGRESQL_SHARED_BUFFERS=4GB POSTGRESQL_EFFECTIVE_CACHE_SIZE=12GB POSTGRESQL_MAX_CONNECTIONS=100 PGBOUNCER_MAX_CLIENT_CONN=1000
Step 3: Configure Inventory
Edit inventory/hosts.yml:
all:
children:
postgres:
hosts:
pg-node1:
ansible_host: 10.0.0.11
patroni_name: node1
Step 4: Deploy Cluster
# Load environment variables set -a && source .env && set +aDeploy cluster
ansible-playbook playbooks/site.yml -i inventory/hosts.yml
Step 5: Verify
ssh [email protected] "patronictl -c /etc/patroni/patroni.yml list"
Outstanding Features
Configuration as Code
All configuration is managed in file .env with over 70 variables, helps:
- Easily manage and audit configuration
- Switch between environments simply by swapping files
.env - Better security with
.gitignorefor sensitive data - Developer-friendly, no need to deeply understand Ansible
Connection Pooling
PgBouncer is configured to optimize connections:
- 13:1 multiplexing ratio (3000 clients → 225 backend connections)
- Automatic failover with multi-host support
- Reduce memory and CPU overhead on PostgreSQL
Zero-Downtime Operations
Planned Switchover: Planned primary node migration with downtime of only 2-5 seconds.
Automatic Failover: Automatic failover in 30-45 seconds when primary fails.
Rolling Updates: Update configuration or version without affecting service availability.
CI/CD Pipeline
Automated Validation
GitHub Actions automatically validates each change:
- YAML syntax checking
- Ansible playbooks validation
- Security scanning (Trivy, TruffleHog)
- Code quality checks
Release Automation
When creating a new tag (v1.0.0), GitHub Actions automatically:
- Generate changelog from git history
- Create release archive
- Publish GitHub Release with documentation
Performance
In a test environment with 3 nodes (16GB RAM, 5 cores per node):
- Read QPS: 50,000-100,000
- Write QPS: 10,000-20,000
- Failover time: 30-45 seconds
- Connection capacity: 3,000 clients
- Query latency: <5ms (simple queries)
Lessons Learned
1. Use Proven Tools
Instead of developing our own, we use proven technologies such as Patroni, etcd, and PgBouncer. This helps focus on automation instead of reinventing the wheel.
2. Configuration as Code
Externalize configuration out .env files instead of hardcode in playbooks makes it easy to customize and maintain for different environments.
3. Security First
Always prioritize security from the beginning:
- Use
.gitignorefor sensitive files - Generate strong passwords
- Automatically configure firewall rules
- Integrate security scanning in CI
4. Documentation Matters
Good documentation reduces onboarding time and demonstrates the professionalism of the project. We maintain full documentation in both English and Vietnamese.
Roadmap
Features in development:
- Integrated Prometheus/Grafana monitoring
- Automated backups with pgBackRest
- Terraform support for cloud deployment
- Docker/Kubernetes deployment option
- Multi-region replication
When Should You Use It?
Suitable for:
- Applications require high availability (uptime > 99.9%)
- The system cannot tolerate extended downtime
- Multi-tenant applications with multiple concurrent connections
- Teams applies Infrastructure as Code
Not necessary when:
- Development/testing environments are simple
- Low-traffic applications
- Applications may accept occasional downtime
- Budget constraints (need at least 3 servers)
Conclusion
Building a PostgreSQL High Availability cluster is no longer a big challenge with the right tools and approach. This solution has been proven in production and helps ensure uptime for many important systems.
With this set of Ansible playbooks, you can deploy a production-ready cluster in 10 minutes, achieve uptime over 99.9%, and manage infrastructure according to the Infrastructure as Code method.
Contribute
If you find the project useful:
- ⭐ Star repository
- 🐛 Report issues
- 💬 Share feedback
- 🤝 Contribute code
- 📢 Share with the community