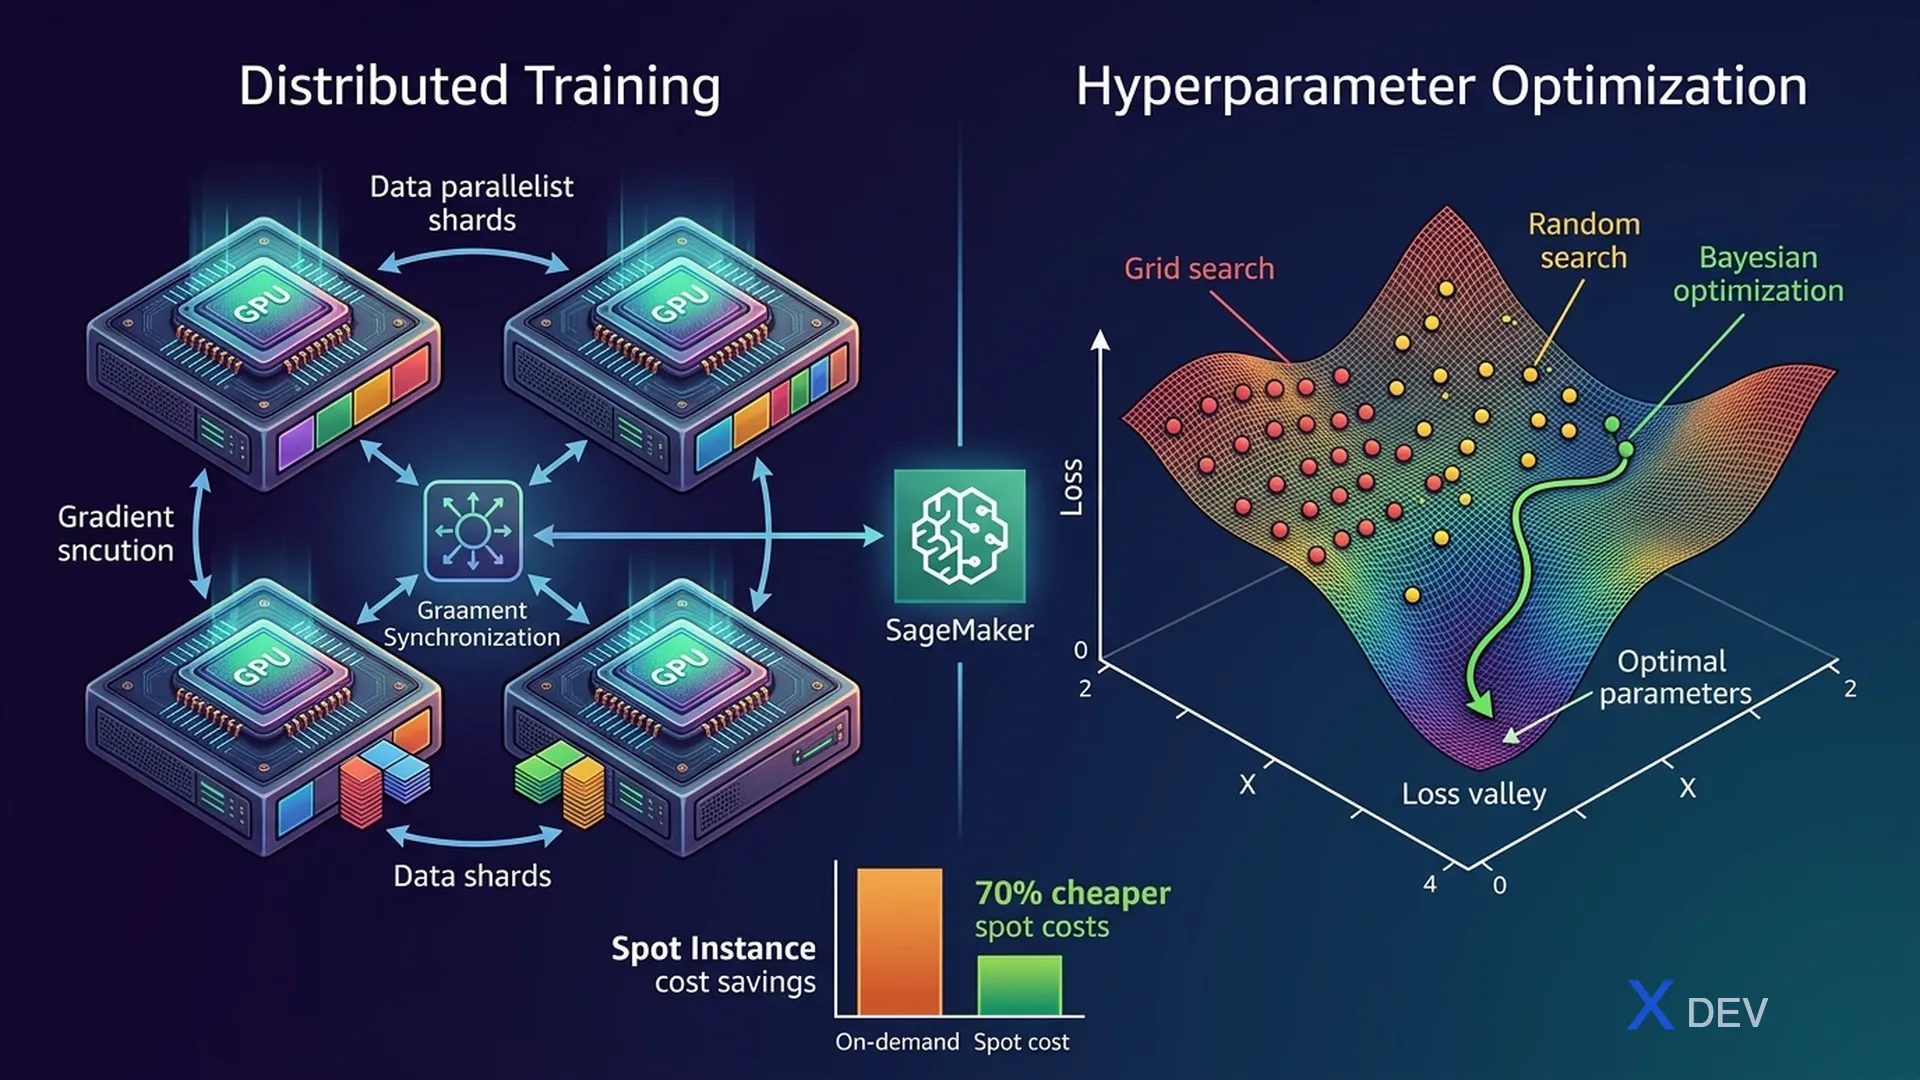
SageMaker Training Jobs & Hyperparameter Tuning: distributed training, Spot Instances, and HPO strategies
1. SageMaker Training Jobs
SageMaker Training Jobs run ML training code on managed compute infrastructure. Training runs on ephemeral instances — you only pay while they're running.
Training Job Lifecycle:

  Submit Job ──→ Provision Instances ──→ Download Data
                                              ↓
                                       Run Training Code
                                              ↓
                                       Save Model to S3
                                              ↓
                                       Terminate Instances
2. Instance Types for Training
| Instance Family | Hardware | Best For |
|---|---|---|
| ml.c5 | CPU optimized | Tabular ML, XGBoost, sklearn |
| ml.m5 | General purpose CPU | Light training, data processing |
| ml.p3 | V100 GPU | Deep learning training |
| ml.p4d | A100 GPU (8x) | Large-scale DL, distributed training |
| ml.g4dn | T4 GPU (cost-effective) | Small-medium DL models |
| ml.trn1 | AWS Trainium | LLM training, cost optimization |
3. Distributed Training
When the model or dataset is too large for a single instance, distributed training across multiple instances is needed.
| Strategy | How It Works | When to Use |
|---|---|---|
| Data Parallelism | Each instance has a copy of the model, trains on a subset of data, syncs gradients | Dataset too large, model fits in one GPU |
| Model Parallelism | Model split across instances, each holds a portion | Model too large for a single GPU (LLMs) |
Data Parallelism:

Instance 1 [Full Model] ──→ Train on data shard A ──→ ↓
Instance 2 [Full Model] ──→ Train on data shard B ──→ ↓  AllReduce
Instance 3 [Full Model] ──→ Train on data shard C ──→ ↓  (sync gradients)
                                                          ↓
                                              Updated Model Weights

Model Parallelism:

Instance 1 [Layers 1-4]  ──→ forward pass ──→
Instance 2 [Layers 5-8]  ──→ forward pass ──→
Instance 3 [Layers 9-12] ──→ forward pass ──→ output
Exam tip: SageMaker provides the SageMaker Distributed library with 2 modules: (1)
smdistributed.dataparallel— optimized AllReduce; (2)smdistributed.modelparallel— auto pipeline parallelism. When the question asks "large model training" → model parallelism.
4. Automatic Model Tuning (HPO)
Hyperparameter Optimization (HPO) automatically finds the best hyperparameters by running multiple training jobs with different configurations.
| Strategy | How It Works | Tradeoff |
|---|---|---|
| Random Search | Randomly sample hyperparameters from range | Fast, good baseline |
| Grid Search | Try all combinations | Exhaustive, expensive, bad for large spaces |
| Bayesian Optimization | Probabilistic model of outcome, suggests best next config | Efficient, learns from previous trials — SageMaker default |
| Hyperband | Early-stop poorly performing trials | Resource-efficient, fast |
Exam tip: SageMaker AMT (Automatic Model Tuning) uses Bayesian Optimization by default. It EXAMINES RESULTS from previous jobs to suggest the next hyperparameter set — intelligent search, not brute force.
5. Spot Instance Training
SageMaker supports using EC2 Spot Instances for training jobs, saving up to 90% in cost compared to On-Demand.
| Feature | Detail |
|---|---|
| MaxWaitTimeInSeconds | Maximum time to wait for spot capacity |
| Checkpointing | Saves model to S3 periodically — resume after interruption |
| use_spot_instances=True | Parameter in SageMaker Estimator |
Exam tip: When the question asks "reduce training costs", the answer is usually Spot Instances with checkpointing. Checkpointing is essential to avoid losing progress when spot instances are terminated.
6. Bias-Variance Tradeoff
| Issue | Symptom | Cause | Solution |
|---|---|---|---|
| High Bias (Underfitting) | High train error, high test error | Model too simple | Increase model complexity, add features, reduce regularization |
| High Variance (Overfitting) | Low train error, high test error | Model too complex | Add more data, dropout, regularization, feature selection |
| Balanced | Low train error, low test error (close to each other) | Good fit | Deploy model |
7. Practice Questions
Q1: A company is training a large deep learning model that doesn't fit on a single GPU instance. Which SageMaker distributed training strategy should they use?
- A) Data parallelism
- B) Model parallelism ✓
- C) Pipeline parallelism only
- D) Increase batch size
Explanation: Model parallelism splits the model itself across multiple GPU instances, allowing training of models too large to fit in a single GPU's memory. Data parallelism keeps a full model copy on each instance, which doesn't help when the model itself is too large.
Q2: A team wants to minimize the cost of running 500 hyperparameter tuning jobs. Training can tolerate interruptions. What is the MOST cost-effective approach?
- A) Use larger instances to run jobs faster
- B) Use Spot Instances with checkpointing enabled ✓
- C) Use Grid Search instead of Bayesian Optimization
- D) Reduce the number of epochs
Explanation: Spot Instances can save up to 90% compared to On-Demand pricing. With checkpointing enabled, interrupted jobs save their state to S3 and can resume, making Spot Instances practical for long HPO jobs.
Q3: A model achieves 95% accuracy on training data but only 62% on the test set. What problem does this indicate?
- A) Underfitting / High bias
- B) Overfitting / High variance ✓
- C) Data leakage
- D) Class imbalance
Explanation: The large gap between training accuracy (95%) and test accuracy (62%) is a classic sign of overfitting (high variance). The model memorized the training data but fails to generalize. Solutions: more data, regularization (L1/L2, dropout), reduce model complexity.