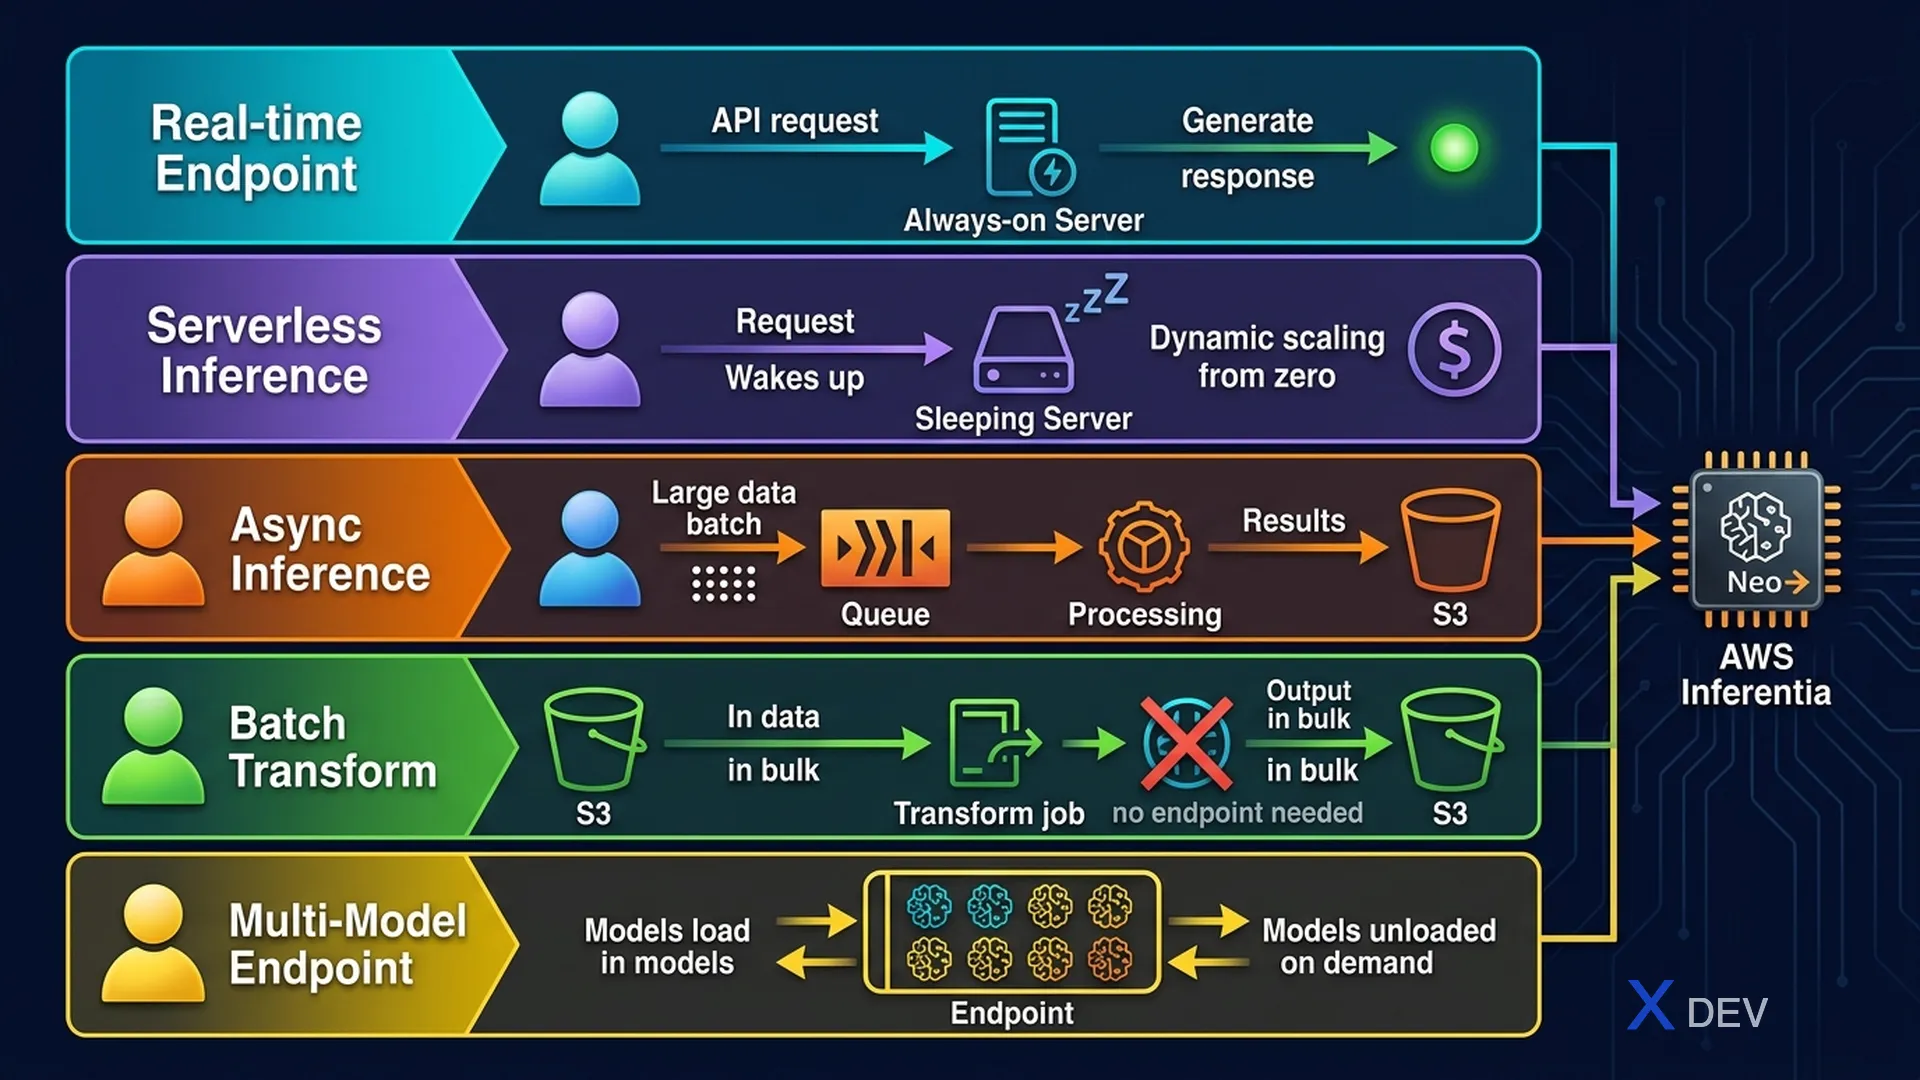
SageMaker Deployment: Real-time Endpoint, Serverless, Async Inference, and Batch Transform
1. SageMaker Deployment Options
SageMaker provides multiple inference patterns — each suited for different workloads. This section typically has 5-8 questions on the MLS-C01 exam.
Exam tip: Key decision factors: latency requirement, volume, cost, payload size. Map these to: Real-time (low latency) → Async (large payload) → Serverless (sporadic) → Batch (no latency need).
| Deployment Type | Latency | Throughput | Cost Model | Best For |
|---|---|---|---|---|
| Real-time Endpoint | Milliseconds | High | Always-on (pay per hour) | Interactive apps, APIs |
| Serverless Inference | Seconds (cold start) | Variable | Pay-per-invocation | Sporadic, unpredictable traffic |
| Async Inference | Minutes | High queued | Pay per processing | Large payloads, non-urgent |
| Batch Transform | No real-time | Very high | Pay per batch job | Scheduled offline predictions |
2. Real-time Inference
Standard deployment — a persistent endpoint that runs constantly and responds synchronously.
Real-time Endpoint Architecture:

Client ──→ HTTPS Request
              ↓
      SageMaker Endpoint
      ┌────────────────┐
      │  Model Server  │  ← Instance running 24/7
      │  (TorchServe,  │
      │  TensorFlow    │
      │  Serving, etc) │
      └────────────────┘
              ↓
         Response (ms)
2.1. Auto Scaling for Endpoints
Endpoints can scale based on the InvocationsPerInstance metric via Application Auto Scaling.
3. Serverless Inference
Best suited for uneven, unpredictable traffic. AWS automatically scales, including down to 0 when there's no traffic.
| Feature | Detail |
|---|---|
| Cold start latency | ~1-2 seconds (first request after idle) |
| Memory config | 1 GB → 6 GB |
| Max payload | 4 MB |
| Pricing | Per inference requests + processing time |
4. Async Inference
Best for large media files, long processing time. Requests are queued, responses saved to S3.
Async Inference Flow:

Client ──→ Upload payload to S3 ──→ Invoke Endpoint
                                          ↓
                                   Queue Request
                                          ↓
                               Process when instance available
                                          ↓
                                   Save output to S3
                                          ↓
                           SNS Notification → Client
| Feature | Detail |
|---|---|
| Max payload | 1 GB (vs 6 MB for real-time) |
| Auto-scale to 0 | Yes — scales down when queue empty |
| Response | S3 output path + SNS notification |
5. Batch Transform
Runs predictions on an entire dataset on schedule. No endpoint — only runs when needed.
Batch Transform:

Input S3 ──→ Batch Transform Job ──→ Output S3
  (CSV/       (ephemeral compute)      (CSV/JSON
  JSON/                                predictions)
  Parquet)           ↑
               No persistent endpoint
               Pay only when running
6. Multi-Model Endpoints (MME)
MME allows hosting multiple models on a single endpoint, reducing inference infrastructure costs.
| Feature | Detail |
|---|---|
| Cost saving | One endpoint serves thousands of models |
| Dynamic loading | Models loaded into memory on-demand, cached |
| Use case | SaaS multi-tenant with model per customer |
7. SageMaker Neo — Edge Deployment
SageMaker Neo compiles and optimizes models for specific hardware (edge devices, mobile).
Neo Workflow:

Trained Model (S3)
       ↓
  Neo Compiler
  (optimizes for target hardware)
       ↓
 Optimized Model
       ↓
    ├── Deploy to IoT Greengrass (edge)
    ├── Deploy to ARM devices
    └── Deploy to mobile (Android/iOS)
8. Cheat Sheet — Deployment Decision
| Scenario | Deployment Type |
|---|---|
| Mobile app, real-time response (<100ms) | Real-time Endpoint |
| Traffic is sporadic (few req/hour) | Serverless Inference |
| Video/audio processing (large files) | Async Inference |
| Nightly predictions on full dataset | Batch Transform |
| Thousands of customer-specific models | Multi-Model Endpoints |
| IoT edge device deployment | SageMaker Neo + Greengrass |
9. Practice Questions
Q1: A company runs an e-commerce chatbot that requires sub-100ms response times during peak shopping hours. Which SageMaker inference type should they use?
- A) Batch Transform
- B) Async Inference
- C) Serverless Inference
- D) Real-time Endpoint ✓
Explanation: Real-time Endpoints provide persistent, always-on inference with millisecond latency. Serverless has cold start delays, Async is asynchronous (not sub-100ms), and Batch Transform is for scheduled offline processing.
Q2: A media company wants to run ML classification on 1 GB video files. Processing time is not urgent. Which SageMaker inference option is MOST appropriate?
- A) Real-time Endpoints
- B) Serverless Inference
- C) Async Inference ✓
- D) Batch Transform
Explanation: Async Inference supports payloads up to 1 GB and queues requests for processing, making it ideal for large media files. Real-time is limited to 6 MB payload, Serverless to 4 MB, and Batch Transform is for scheduled bulk predictions without real-time queue.
Q3: A SaaS company provides individual ML models for each of their 10,000 enterprise customers. Hosting each on a separate endpoint is too expensive. What is the BEST solution?
- A) Merge all models into one large model
- B) Use SageMaker Multi-Model Endpoints ✓
- C) Deploy all models on a single Batch Transform job
- D) Use Serverless Inference for each model
Explanation: Multi-Model Endpoints (MME) host multiple models on a single endpoint, dynamically loading them into memory on-demand. This is exactly designed for multi-tenant scenarios where each customer has their own model, reducing infrastructure costs by orders of magnitude.