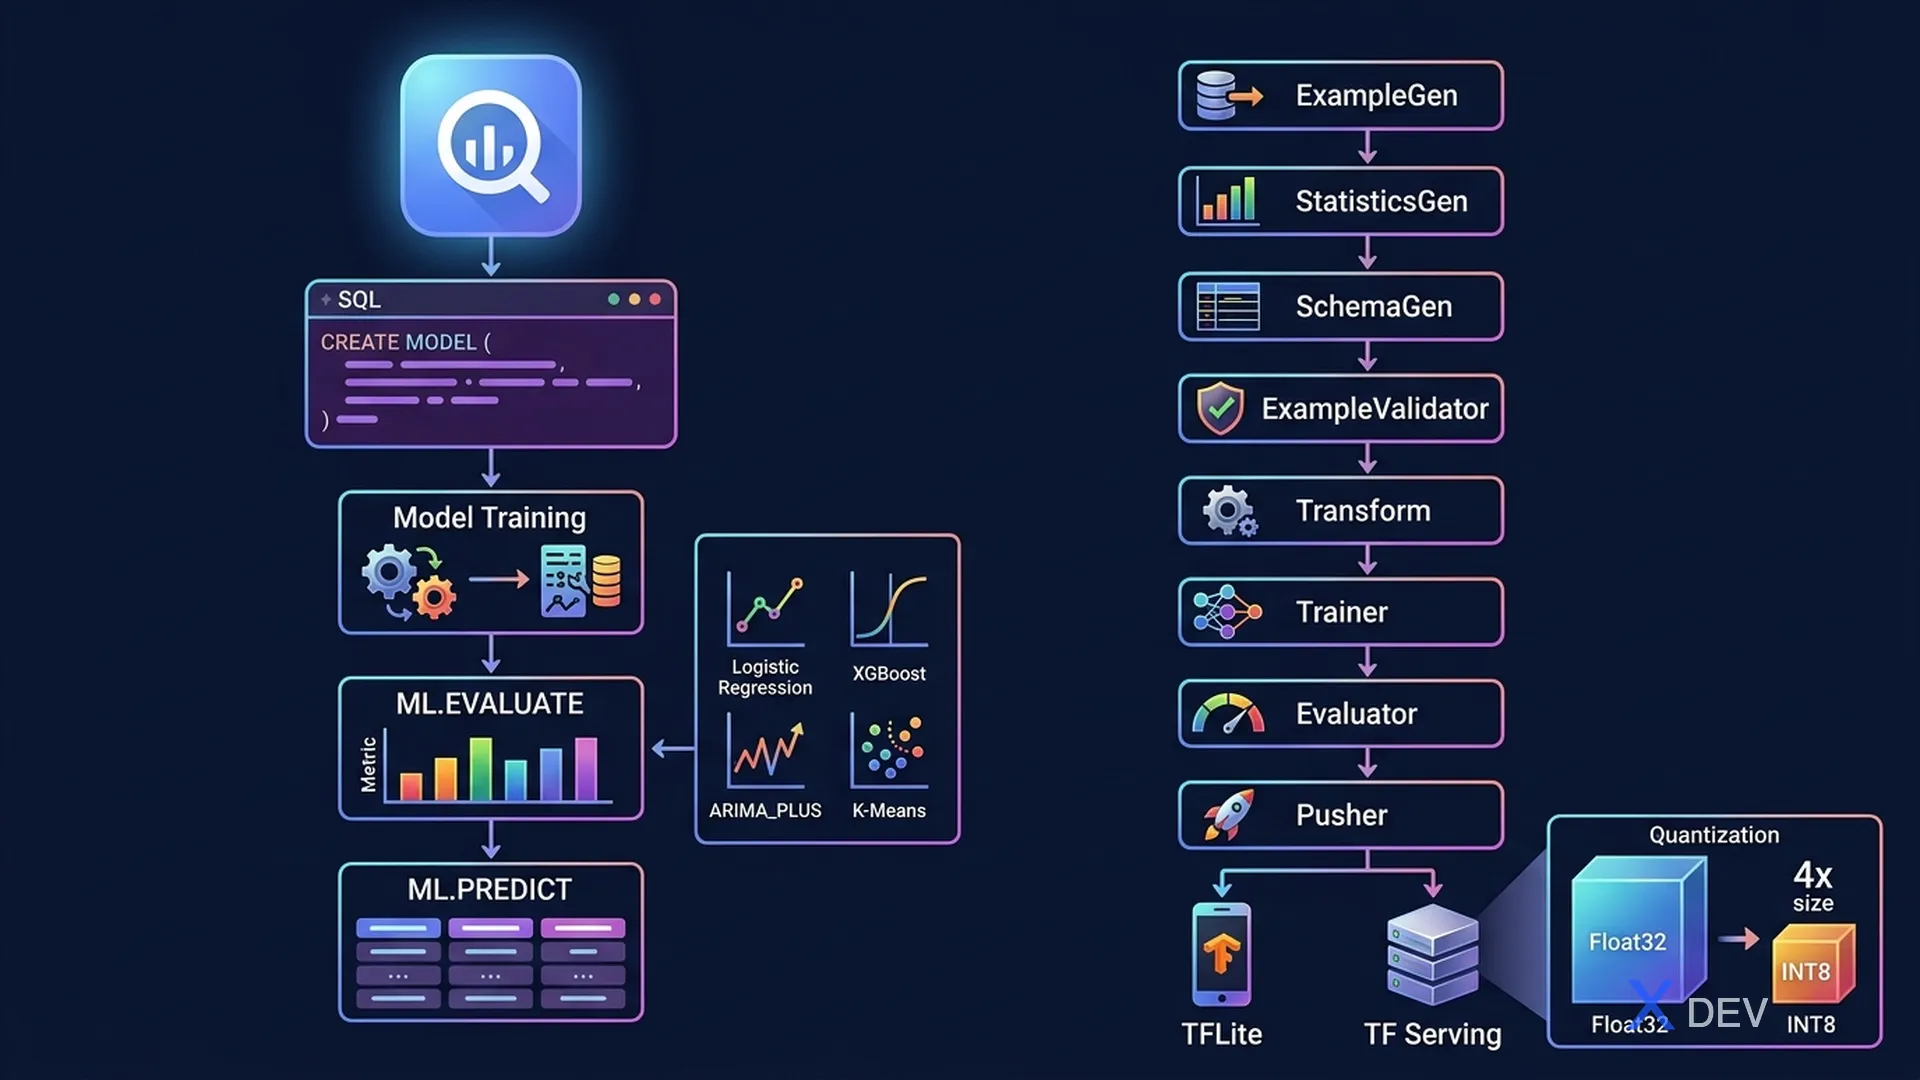
BigQuery ML and TFX Pipeline: train models with SQL, optimize models, and production ML pipelines
1. BigQuery ML (BQML)
BigQuery ML lets data analysts train and serve ML models using SQL within BigQuery — no need to export data or learn ML frameworks.
BigQuery ML Workflow:

1. CREATE MODEL → train
2. ML.EVALUATE() → evaluate metrics
3. ML.PREDICT() → generate predictions
4. ML.EXPLAIN_PREDICT() → SHAP-based explanations
5. EXPORT MODEL → export to Cloud Storage (TF SavedModel format)
| Model Type | BQML Option | Task |
|---|---|---|
| Linear Regression | LINEAR_REG | Regression |
| Logistic Regression | LOGISTIC_REG | Binary/Multiclass classification |
| K-Means | KMEANS | Clustering |
| XGBoost | BOOSTED_TREE_CLASSIFIER / BOOSTED_TREE_REGRESSOR | Tabular classification/regression |
| Random Forest | RANDOM_FOREST_CLASSIFIER / RANDOM_FOREST_REGRESSOR | Tabular classification/regression |
| DNN | DNN_CLASSIFIER / DNN_REGRESSOR | Complex patterns |
| Wide & Deep | WIDE_AND_DEEP_CLASSIFIER | Recommendations (memorization + generalization) |
| AutoML | AUTOML_CLASSIFIER / AUTOML_REGRESSOR | Automated model selection |
| Time Series | ARIMA_PLUS | Forecasting |
| Matrix Factorization | MATRIX_FACTORIZATION | Collaborative filtering |
Exam tip: BQML ARIMA_PLUS automatically handles seasonality, holiday effects, and trend decomposition. When the question asks "forecast using BigQuery data" → ARIMA_PLUS. When it asks "recommendation system in BigQuery" → MATRIX_FACTORIZATION.
2. TensorFlow Extended (TFX)
TFX is a production ML pipeline library for TensorFlow. It provides standard components for each step in the ML lifecycle.
| TFX Component | Purpose |
|---|---|
| ExampleGen | Ingest data from CSV, BigQuery, Avro, Parquet |
| StatisticsGen | Compute statistics on training data |
| SchemaGen | Infer schema from statistics |
| ExampleValidator | Detect anomalies: missing data, distribution skew |
| Transform | Feature engineering (Apache Beam-based) |
| Trainer | Train TF model (EvalSpec + TrainSpec) |
| Tuner | Hyperparameter tuning (KerasTuner) |
| Evaluator | Evaluate model against baseline |
| ModelValidator | Validate model meets quality thresholds |
| Pusher | Push model to serving (TF Serving, Vertex AI) |
TFX Pipeline (simplified):

ExampleGen → StatisticsGen → SchemaGen → ExampleValidator
                ↓
            Transform (feature engineering)
                ↓
            Trainer (model training)
                ↓
            Evaluator (metrics vs baseline)
                ↓ (if pass)
            Pusher → TF Serving / Vertex AI Endpoint
3. TF Serving & TFLite
| Option | Use Case |
|---|---|
| TF Serving | High-performance serving on server/cloud (gRPC or REST) |
| TFLite | Mobile devices, edge devices, microcontrollers |
| TF.js | Browser-based inference |
4. Model Optimization Techniques
| Technique | Description | Trade-off |
|---|---|---|
| Quantization | Float32 → INT8 weights | 4x smaller, ~2x faster, slight accuracy loss |
| Pruning | Remove low-weight connections | Smaller model, preserve accuracy |
| Knowledge Distillation | Train small "student" model from large "teacher" | Smaller + fast, slight accuracy loss |
| TensorRT | NVIDIA GPU optimization (layer fusion) | 3-5x inference speedup on NVIDIA GPUs |
5. Practice Questions
Q1: A data analyst team needs to build a sales forecasting model on data already in BigQuery. They are comfortable with SQL but have no Python/ML framework experience. Which BigQuery ML model type should they use for time series forecasting?
- A) KMEANS
- B) LOGISTIC_REG
- C) ARIMA_PLUS ✓
- D) MATRIX_FACTORIZATION
Explanation: BigQuery ML ARIMA_PLUS is designed for time series forecasting and automatically handles seasonality, trend, and holiday effects. It can be trained with a simple CREATE MODEL statement in SQL, requiring no Python expertise.
Q2: A TFX pipeline is detecting that the distribution of the "age" feature in new production data differs significantly from the training data distribution. Which TFX component is responsible for detecting this anomaly?
- A) StatisticsGen
- B) SchemaGen
- C) ExampleValidator ✓
- D) Transform
Explanation: ExampleValidator compares data statistics against the expected schema and flags anomalies including distribution skew (significant difference between training and serving data distributions). StatisticsGen computes statistics; SchemaGen creates the schema; Transform does feature engineering.
Q3: A team needs to deploy a TensorFlow image classification model to mobile devices with limited compute resources. They need to reduce model size by 4x with minimal accuracy loss. Which technique should they apply?
- A) Knowledge Distillation
- B) Model Pruning
- C) Post-training quantization (INT8) ✓
- D) TensorRT optimization
Explanation: Post-training quantization converts Float32 weights to INT8, reducing model size by approximately 4x and improving inference speed by 2x, with minimal accuracy loss for most models. TFLite supports INT8 quantization for mobile/edge deployment. TensorRT is for NVIDIA GPUs, not mobile.