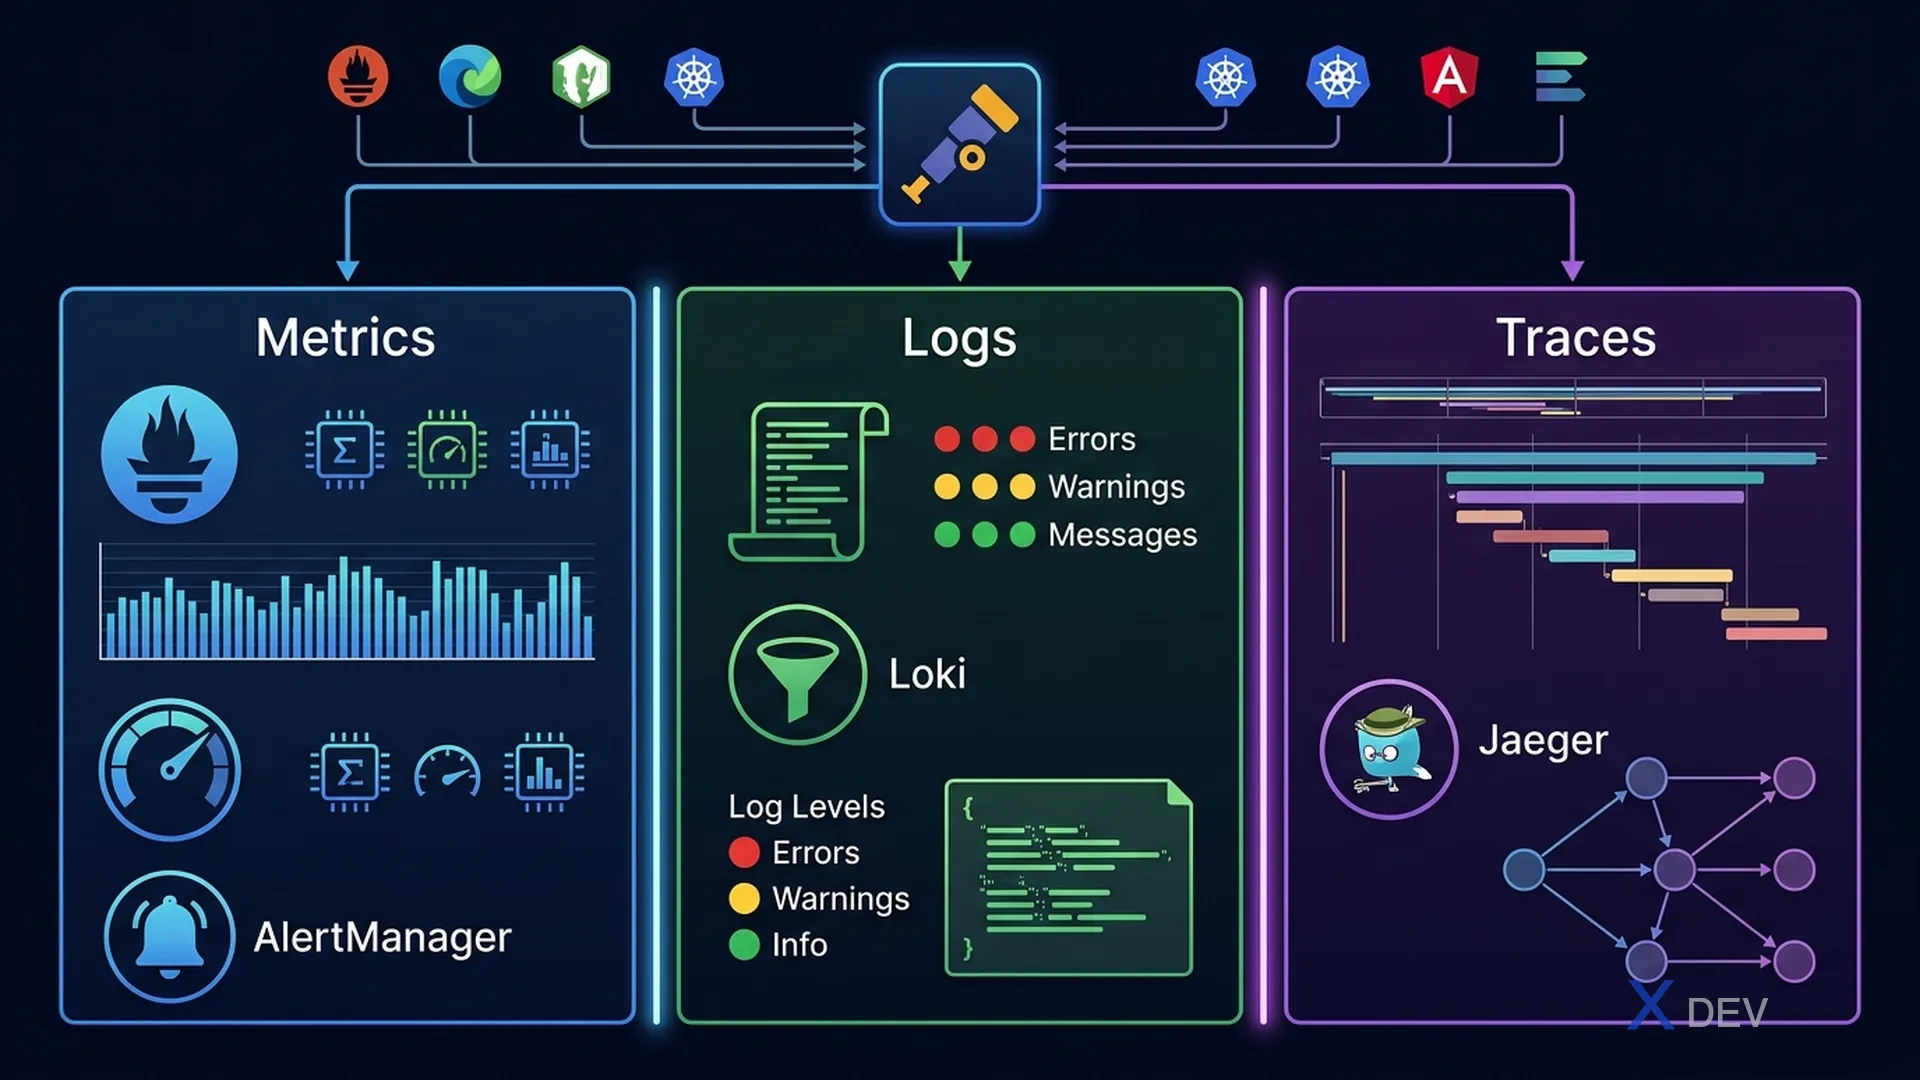
1. Three Pillars of Observability
Observability is the ability to understand the internal state of a system through its external signals. It consists of 3 pillars:
| Pillar | What it is | What question it answers | Tool |
|---|---|---|---|
| Metrics | Aggregated numerical data over time | "What is the current state of the system?" | Prometheus + Grafana |
| Logs | Text event lines from each service | "What happened?" | Loki, Elasticsearch, Fluentd |
| Traces | Request flow across multiple services | "Where did the request go and how long did it take?" | Jaeger, Zipkin, Tempo |
User request fails → Use 3 pillars:

  METRICS: CPU spike at 14:05?
  LOGS: Error "DB timeout" in service B
  TRACES: Request A→B→C, step B took 8s

  → Root cause: Service B DB connection pool exhausted
Exam tip: KCNA often asks "which tool" for each pillar. Prometheus = metrics. Grafana = visualization. Jaeger = distributed tracing. Loki = log aggregation.
2. Prometheus & Metrics
Prometheus is a CNCF graduated project for monitoring and alerting. It uses a pull-based model: Prometheus scrapes metrics from targets.
Prometheus Architecture:
  App (exposes /metrics)
       ↑ scrape
  Prometheus Server ──► Alert Manager ──► Slack/PagerDuty
       │
Grafana (query PromQL → charts)| Metric Type | Meaning | Example |
|---|---|---|
| Counter | Only increases (resets on restart) | http_requests_total |
| Gauge | Can go up and down freely | memory_usage_bytes |
| Histogram | Distribution, quantile | request_duration_seconds |
| Summary | Pre-computed quantiles | response_size_summary |
3. OpenTelemetry (OTel)
OpenTelemetry is the CNCF standard for collecting telemetry (metrics, logs, traces) with vendor-neutral SDKs and a Collector.
OpenTelemetry Flow:
  App (instrumented with OTel SDK)
       │ OTLP (protocol)
  OTel Collector (receive, process, export)
       │
  ┌────┴────┐
 Jaeger   Prometheus   Loki
(traces)  (metrics)   (logs)
Exam tip: OpenTelemetry separates vendor-specific code from apps — you only need to change the OTel Collector config to switch from Jaeger to Zipkin without modifying app code.
4. Observability in Kubernetes
| Component | Provides |
|---|---|
| kubelet /metrics | Node resource metrics for Prometheus |
| metrics-server | CPU/Memory for kubectl top, HPA |
| kube-state-metrics | Kubernetes object state (Pod, Deployment status) |
| Prometheus Operator | Deploy Prometheus stack with CRDs (ServiceMonitor) |
| Loki + Promtail | Log aggregation (Promtail collects logs from nodes) |
kubectl debugging commands
kubectl logs pod-name              # Current container logs
kubectl logs pod-name --previous   # Last crashed container logs
kubectl logs -f pod-name           # Stream live logs
kubectl describe pod pod-name      # Events + status details
kubectl top pod                    # CPU/Memory (needs metrics-server)
kubectl top node                   # Node resource usage
5. Cheat Sheet
| Exam question | Answer |
|---|---|
| 3 pillars of observability? | Metrics, Logs, Traces |
| Distributed tracing tool? | Jaeger, Zipkin, Tempo |
| Kubernetes metrics collection? | Prometheus |
| Visualization dashboard? | Grafana |
| Vendor-neutral telemetry standard? | OpenTelemetry |
| What does kubectl top require? | metrics-server |
6. Practice Questions
Q1: A team needs to trace how a single HTTP request flows through 5 microservices to find which service adds the most latency. Which observability tool should they use?
- A) Prometheus
- B) Grafana
- C) Jaeger ✓
- D) Loki
Explanation: Distributed tracing (Jaeger, Zipkin) tracks a request's entire flow across multiple services, showing each hop's latency and relationships. Prometheus shows aggregate metrics; Loki shows logs; Grafana is visualization.
Q2: What type of Prometheus metric would you use to track the total number of HTTP requests served since startup?
- A) Gauge
- B) Histogram
- C) Counter ✓
- D) Summary
Explanation: Counter is a monotonically increasing metric — it only goes up (or resets to 0 on restart). Perfect for tracking cumulative events like requests, errors, or bytes transferred. Gauge is for values that go up and down (like memory usage).
Q3: Which framework allows developers to instrument their application once and export telemetry to multiple backends (Jaeger, Prometheus, etc.) without code changes?
- A) Prometheus client libraries
- B) OpenTelemetry ✓
- C) Kubernetes metrics-server
- D) Grafana Agent
Explanation: OpenTelemetry provides vendor-neutral APIs and SDKs for generating traces, metrics, and logs. The OTel Collector routes telemetry to different backends. Switching backends requires only Collector config changes, not application code.