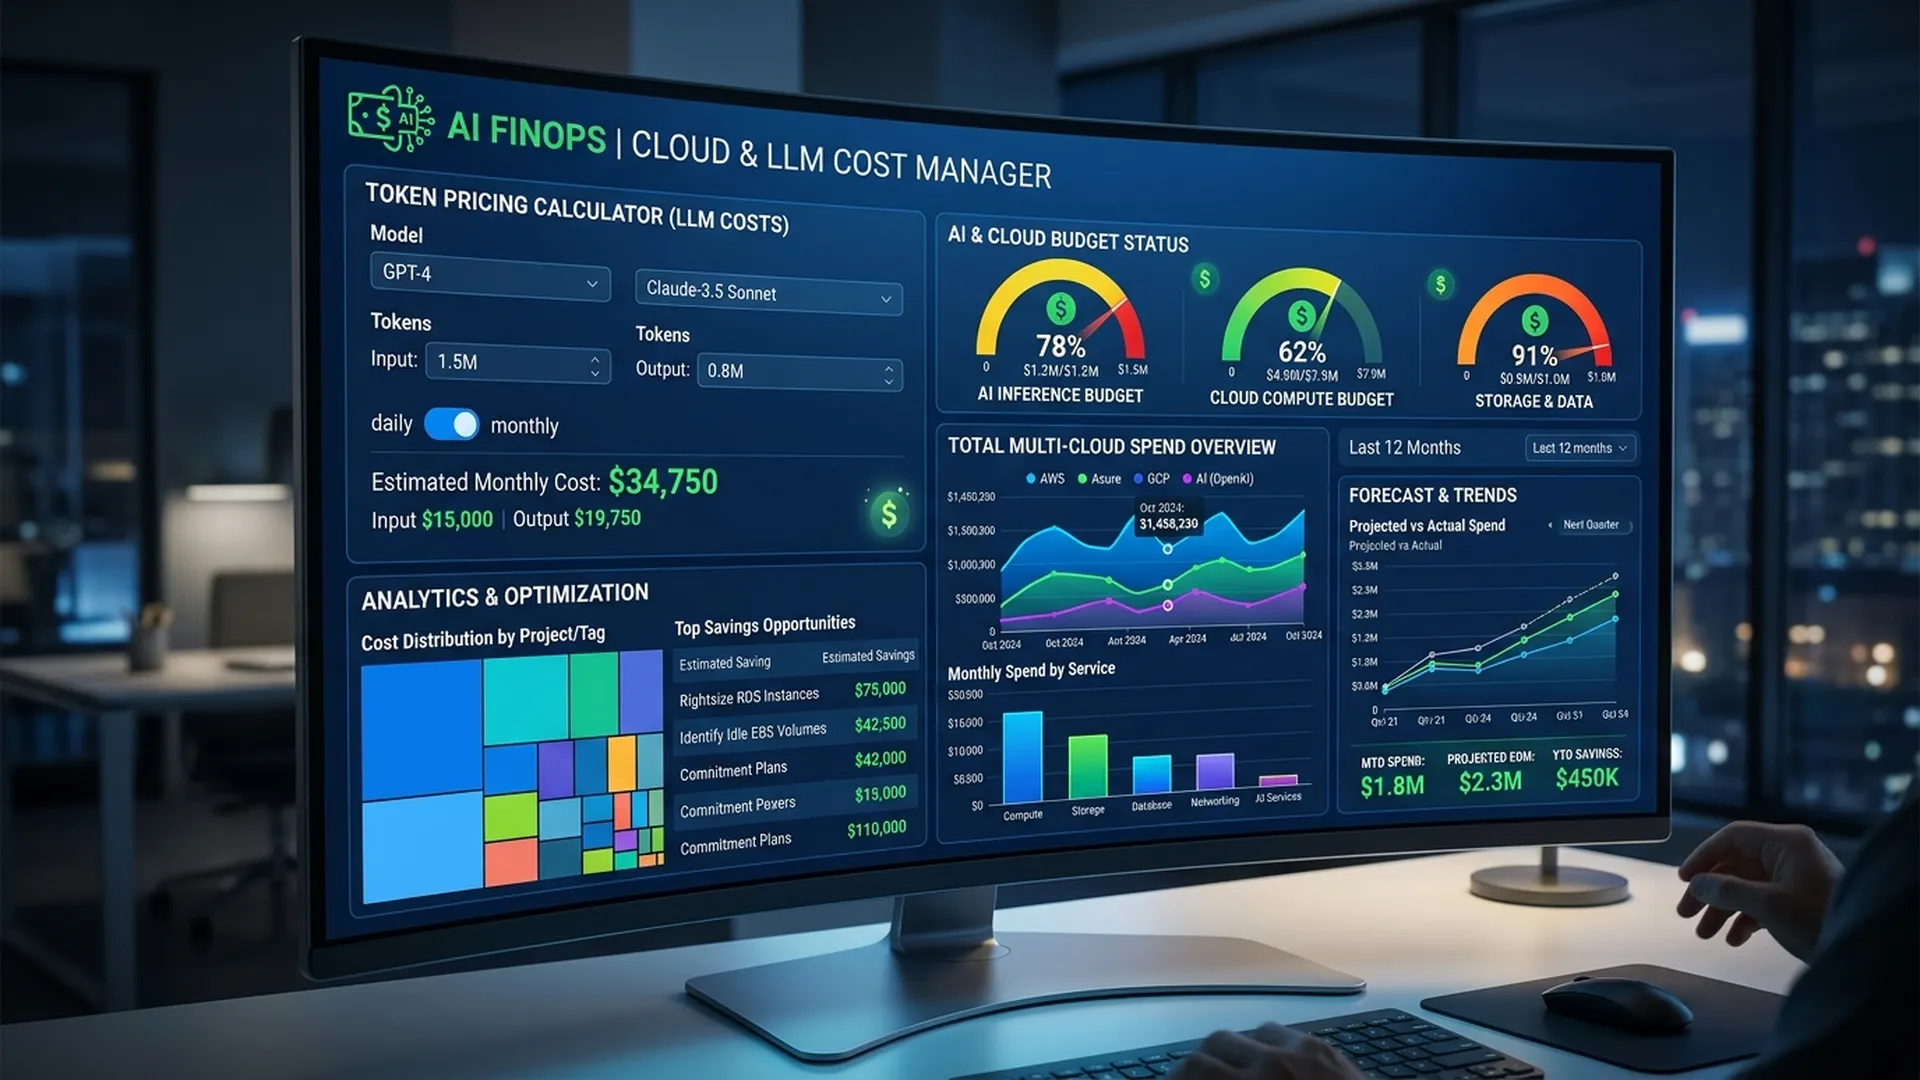
BA 常把「AI 會花多少錢」交給技術團隊處理。這是錯誤的。當 stakeholder 問「這個功能值得投資嗎?」BA 必須拿得出數字,而不是說「我再去問 tech team」。
1. 你需要知道的 AI 成本類型
1.1 Token-based Pricing(LLM API)
多數 LLM API 以 token 計費(不是字元數、也不是字數):
1 token ~= 4 個英文字元 ~= 3/4 個單字
"Hello world" ~= 2 tokens
1 頁 A4 文字 ~= 500-700 tokens
價格範例(參考,2026 年 5 月):
| Model | Input | Output | 何時使用 |
|---|---|---|---|
| GPT-4o mini | $0.15/1M tokens | $0.60/1M tokens | 高流量、簡單任務 |
| GPT-4o | $2.50/1M tokens | $10/1M tokens | 複雜任務、高品質 |
| Claude Sonnet | $3/1M tokens | $15/1M tokens | reasoning、coding、analysis |
| Gemini Flash | $0.075/1M tokens | $0.30/1M tokens | 最低成本,足夠多數任務 |
1.2 成本估算公式
Monthly cost = Daily requests x Avg tokens/request x Cost per token x 30 days

範例:客服 chatbot
- 500 requests/day
- 800 input + 400 output = 1200 tokens/request
- Model: GPT-4o mini ($0.15 input, $0.60 output)

Cost = 500 x [(800 x $0.15) + (400 x $0.60)] / 1,000,000 x 30
     = 500 x [($0.00012) + ($0.00024)] x 30
     = 500 x $0.00036 x 30
     = $5.40/month(chatbot 成本非常低)
2. Latency 與 Compute Cost
除了 API cost,還有:
| Cost Type | 說明 | BA 應知道 |
|---|---|---|
| Compute (GPU) | self-hosted model 推論成本 | 視 GPU 類型約 $0.5-5/小時 |
| Embedding | vector search、RAG | 約 $0.02/1M tokens(很低) |
| Storage | vector DB、model weights | 約 $20-100/月(依量級) |
| Inference latency | user 等待時間造成 UX 成本 | 通常 P95 < 3s 可接受 |
3. Cloud AI API vs Self-hosted Model
| 指標 | Cloud API | Self-hosted |
|---|---|---|
| 前期成本 | $0 | $10K-100K+(GPU) |
| 變動成本 | 按 token 計費 | 電力 + cloud GPU |
| Latency | 0.5-3s | 0.1-1s(local GPU) |
| Data privacy | 資料送到 vendor | 資料留在內部 |
| 維運成本 | 幾乎無 | 需要 MLOps 團隊 |
| 適用情境 | MVP、低中流量 | 大規模、高敏感資料 |
BA Rule of thumb:
- < 1M tokens/month -> Cloud API 幾乎總是更便宜
-
100M tokens/month -> Self-hosted 可能在 6-12 個月後 ROI 轉正
- 高敏感資料(醫療、金融)-> 可能必須 Self-hosted
4. BA 可提出的 FinOps 實務
4.1 Cost Alert Setup
要求團隊設定:
Alert Level 1: 成本達月預算 70% -> 通知 BA + PM
Alert Level 2: 成本達月預算 90% -> 通知 leadership
Alert Level 3: 超過 100% 時,自動關閉非關鍵功能(hard cap)
4.2 Token Optimization Strategies
BA 可提出(不需寫程式):
| Strategy | 說明 | 潛在節省 |
|---|---|---|
| Prompt caching | 多 request 重用 system prompt | input tokens 節省 30-50% |
| Model routing | 簡單任務用小模型 | routine task 成本省 60-90% |
| Context pruning | 移除不必要對話歷史 | 每次 request 省 20-40% |
| Batch processing | 非即時需求批次處理 | 最高可有 50% volume 優惠 |
| Output length limit | 限制 output max tokens | output 成本省 20-30% |
4.3 每個商業成果的成本
不要只看 API 成本,應看每個 business outcome 的成本:
Cost per resolved ticket = Monthly AI cost ÷ Tickets resolved by AI
Cost per qualified lead = Monthly AI cost ÷ Leads qualified by AI
Cost savings vs manual = (FTE hours saved x hourly rate) - AI cost
5. BA 的 Budget Estimation Template
## AI Feature Cost Estimate
**Feature:** [Name] | **Date:** [YYYY-MM] | **Owner:** [BA]

### Volume Assumptions
| Parameter | Estimate | Source |
|-----------|----------|--------|
| Daily active users | [X] | Analytics/forecast |
| Requests per user per day | [Y] | UX assumption |
| Total daily requests | [XxY] | Calculated |

### Per-Request Cost
| Component | Cost | Notes |
|-----------|------|-------|
| LLM API (input) | $[X]/1K tokens | [Model name] |
| LLM API (output) | $[X]/1K tokens | [Model name] |
| Avg tokens per request | [X] input + [Y] output | Estimated from prototype |
| **Cost per request** | **$[total]** | |

### Monthly Projection
| Scenario | Cost | Notes |
|----------|------|-------|
| Conservative (50% of estimate) | $[X] | Low adoption |
| Base case | $[Y] | Expected |
| Peak (200% of estimate) | $[Z] | Viral/spike |

### ROI Estimate
- Manual cost replaced: $[X]/month
- AI cost: $[Y]/month
- Net savings: $[X-Y]/month
- Break-even: [N] months
結論
BA 不需要精通 cloud architecture 才能做 AI 成本估算。理解 token pricing、知道何時選 cloud 或 self-hosted、並建立 cost alert,就足以參與 business case 並避免 budget overrun。
當 stakeholder 問「這個 AI 功能要花多少錢?」你可以在 30 分鐘內用模板給出答案。