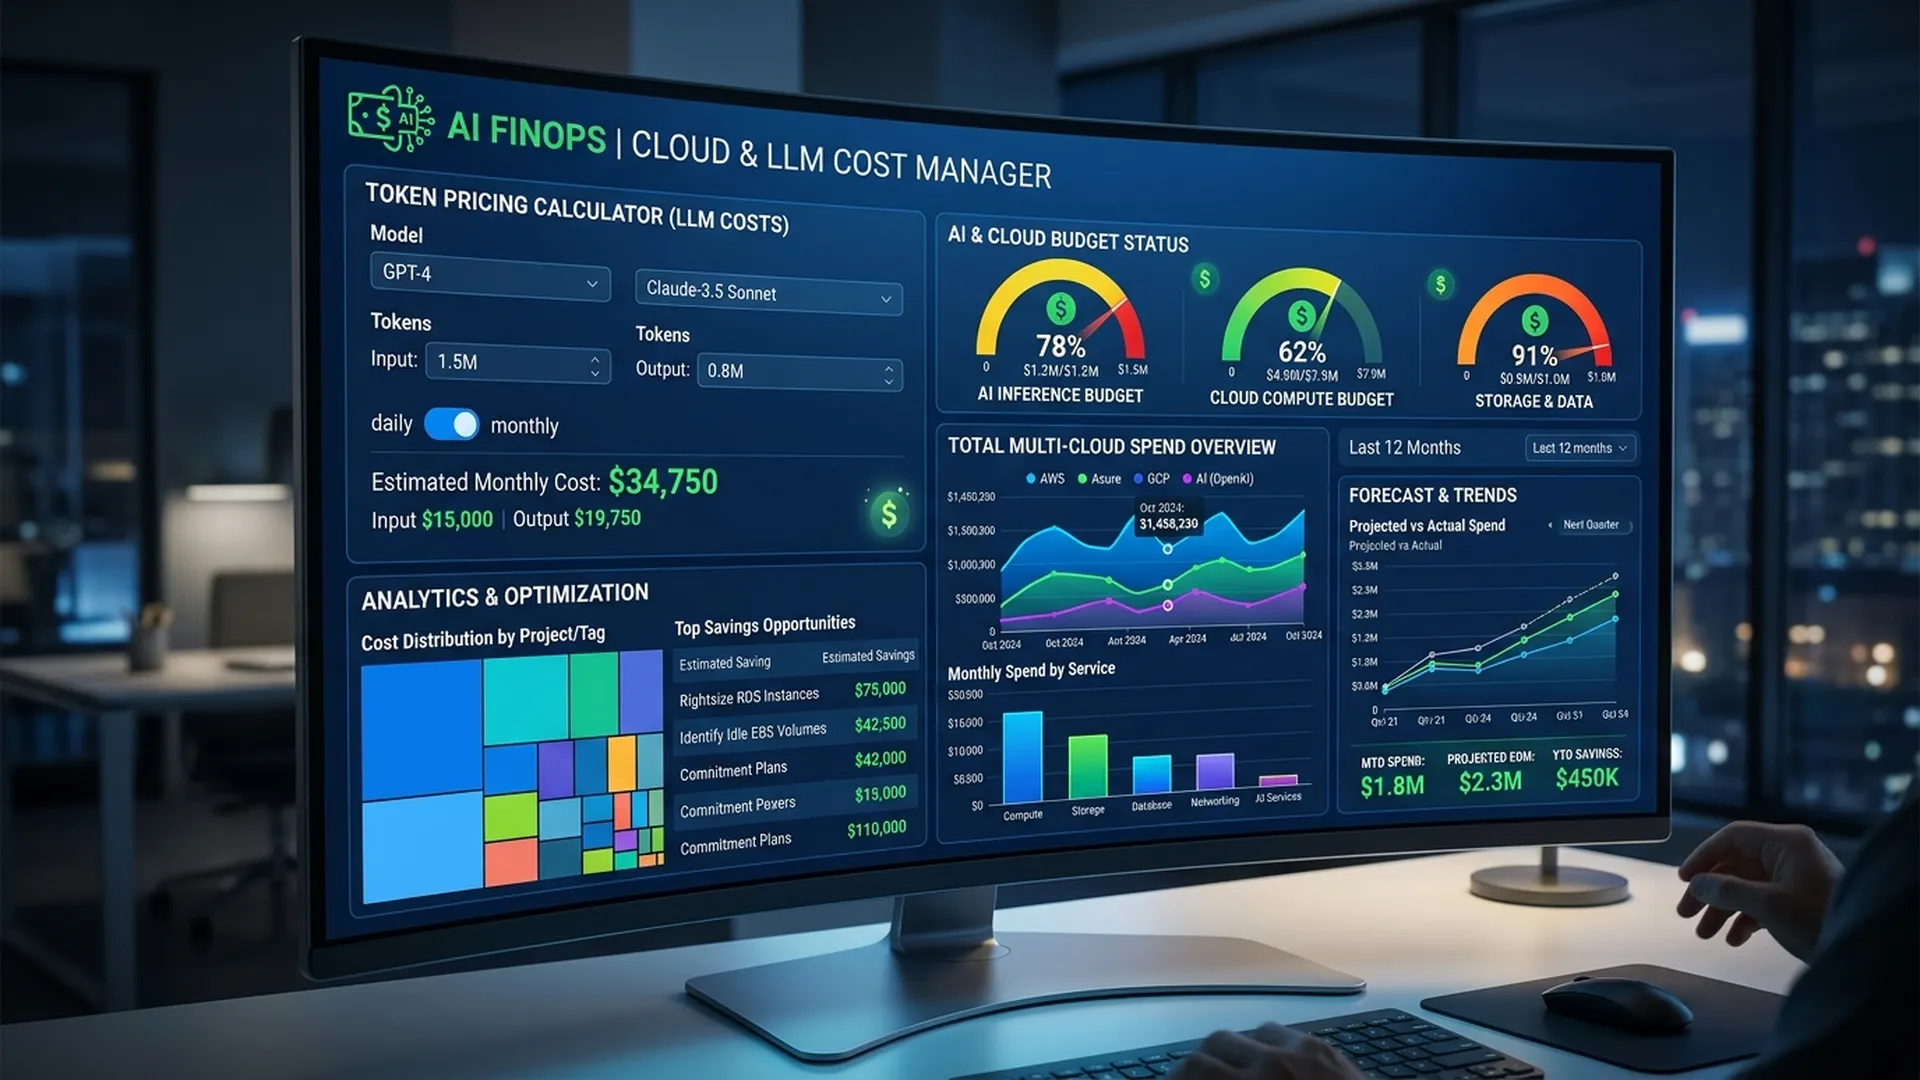
BA thường để team kỹ thuật lo phần "AI tốn bao nhiêu tiền". Đây là sai lầm. Khi stakeholder hỏi "feature này có đáng đầu tư không?", BA phải có con số trong tay, không phải nói "để hỏi team tech".
1. Các loại chi phí AI bạn cần biết
1.1 Token-based Pricing (LLM API)
Hầu hết LLM API tính phí theo token (không phải ký tự, không phải từ):
1 token ≈ 4 ký tự tiếng Anh ≈ 3/4 từ
"Hello world" ≈ 2 tokens
1 trang A4 text ≈ 500-700 tokens
Ví dụ pricing (tham khảo, tháng 5/2026):
| Model | Input | Output | Khi nào dùng |
|---|---|---|---|
| GPT-4o mini | $0.15/1M tokens | $0.60/1M tokens | Volume cao, task đơn giản |
| GPT-4o | $2.50/1M tokens | $10/1M tokens | Task phức tạp, chất lượng cao |
| Claude Sonnet | $3/1M tokens | $15/1M tokens | Reasoning, coding, analysis |
| Gemini Flash | $0.075/1M tokens | $0.30/1M tokens | Rẻ nhất, đủ cho nhiều task |
1.2 Cost Estimation Formula
Monthly cost = Daily requests × Avg tokens/request × Cost per token × 30 days

Ví dụ: Chatbot support
- 500 requests/day
- 800 tokens input + 400 tokens output = 1200 tokens/request
- Model: GPT-4o mini ($0.15 input, $0.60 output)

Cost = 500 × [(800 × $0.15) + (400 × $0.60)] / 1,000,000 × 30
     = 500 × [($0.00012) + ($0.00024)] × 30
     = 500 × $0.00036 × 30
     = $5.40/tháng (rất rẻ cho chatbot)
2. Latency và Compute Cost
Ngoài API cost, còn có:
| Cost Type | Mô tả | BA cần biết |
|---|---|---|
| Compute (GPU) | Chạy model self-hosted | $0.5-5/GPU hour tùy loại |
| Embedding | Vector search, RAG | $0.02/1M tokens (rất rẻ) |
| Storage | Vector DB, model weights | $20-100/month tùy volume |
| Inference latency | User waiting time → UX cost | P95 latency < 3s thường acceptable |
3. Cloud AI API vs Self-hosted Model
| Tiêu chí | Cloud API | Self-hosted |
|---|---|---|
| Upfront cost | $0 | $10K-100K+ (GPU) |
| Variable cost | Pay per token | Điện + cloud GPU |
| Latency | 0.5-3s | 0.1-1s (local GPU) |
| Data privacy | Data goes to vendor | Data stays in-house |
| Maintenance | None | MLOps team needed |
| Khi nào chọn | MVP, volume thấp-trung | Scale lớn, data sensitive |
BA Rule of thumb:
- < 1M tokens/month → Cloud API gần như luôn rẻ hơn
-
100M tokens/month → Self-hosted có thể ROI dương sau 6-12 tháng
- Data classified (y tế, tài chính) → Self-hosted bắt buộc
4. FinOps Practices BA có thể đề xuất
4.1 Cost Alert Setup
Yêu cầu team setup:
Alert Level 1: Khi cost đạt 70% monthly budget → Notify BA + PM
Alert Level 2: Khi cost đạt 90% monthly budget → Notify leadership
Alert Level 3: Hard cap tự động tắt non-critical features khi vượt 100%
4.2 Token Optimization Strategies
BA có thể đề xuất (không cần code để understand):
| Strategy | Mô tả | Tiết kiệm tiềm năng |
|---|---|---|
| Prompt caching | Reuse system prompt cho nhiều request | 30-50% input tokens |
| Model routing | Dùng model nhỏ cho task đơn giản | 60-90% cost cho routine tasks |
| Context pruning | Cắt bớt conversation history không cần thiết | 20-40% per request |
| Batch processing | Gộp request không cần real-time | Volume discount 50% |
| Output length limit | Giới hạn max tokens output | 20-30% output cost |
4.3 Cost per Business Metric
Đừng chỉ nhìn API cost — tính cost per business outcome:
Cost per resolved ticket = Monthly AI cost ÷ Tickets resolved by AI
Cost per qualified lead = Monthly AI cost ÷ Leads qualified by AI
Cost savings vs manual = (FTE hours saved × hourly rate) - AI cost
5. Budget Estimation Template cho BA
## AI Feature Cost Estimate
**Feature:** [Name] | **Date:** [YYYY-MM] | **Owner:** [BA]

### Volume Assumptions
| Parameter | Estimate | Source |
|-----------|----------|--------|
| Daily active users | [X] | Analytics/forecast |
| Requests per user per day | [Y] | UX assumption |
| Total daily requests | [X×Y] | Calculated |

### Per-Request Cost
| Component | Cost | Notes |
|-----------|------|-------|
| LLM API (input) | $[X]/1K tokens | [Model name] |
| LLM API (output) | $[X]/1K tokens | [Model name] |
| Avg tokens per request | [X] input + [Y] output | Estimated from prototype |
| **Cost per request** | **$[total]** | |

### Monthly Projection
| Scenario | Cost | Notes |
|----------|------|-------|
| Conservative (50% of estimate) | $[X] | Low adoption |
| Base case | $[Y] | Expected |
| Peak (200% of estimate) | $[Z] | Viral/spike |

### ROI Estimate
- Manual cost replaced: $[X]/month
- AI cost: $[Y]/month
- Net savings: $[X-Y]/month
- Break-even: [N] months
Kết luận
BA không cần biết cloud architecture để estimate AI cost. Hiểu token pricing, biết khi nào nên cloud vs self-hosted, và setup cost alert — đủ để BA tham gia vào business case và ngăn chặn budget overrun.
Khi stakeholder hỏi "AI feature này tốn bao nhiêu?", bạn có template để trả lời trong vòng 30 phút.