Introduction
Mathematics is the language that AI models use to "think". But don't worry — you don't have to be a mathematician to understand AI! This article focuses on what's really needed, explaining it with real life examples first, then getting into the code.
Study tips: Each section has practical examples → illustrative code → small exercises. If you don't understand any part, read the practical example first.
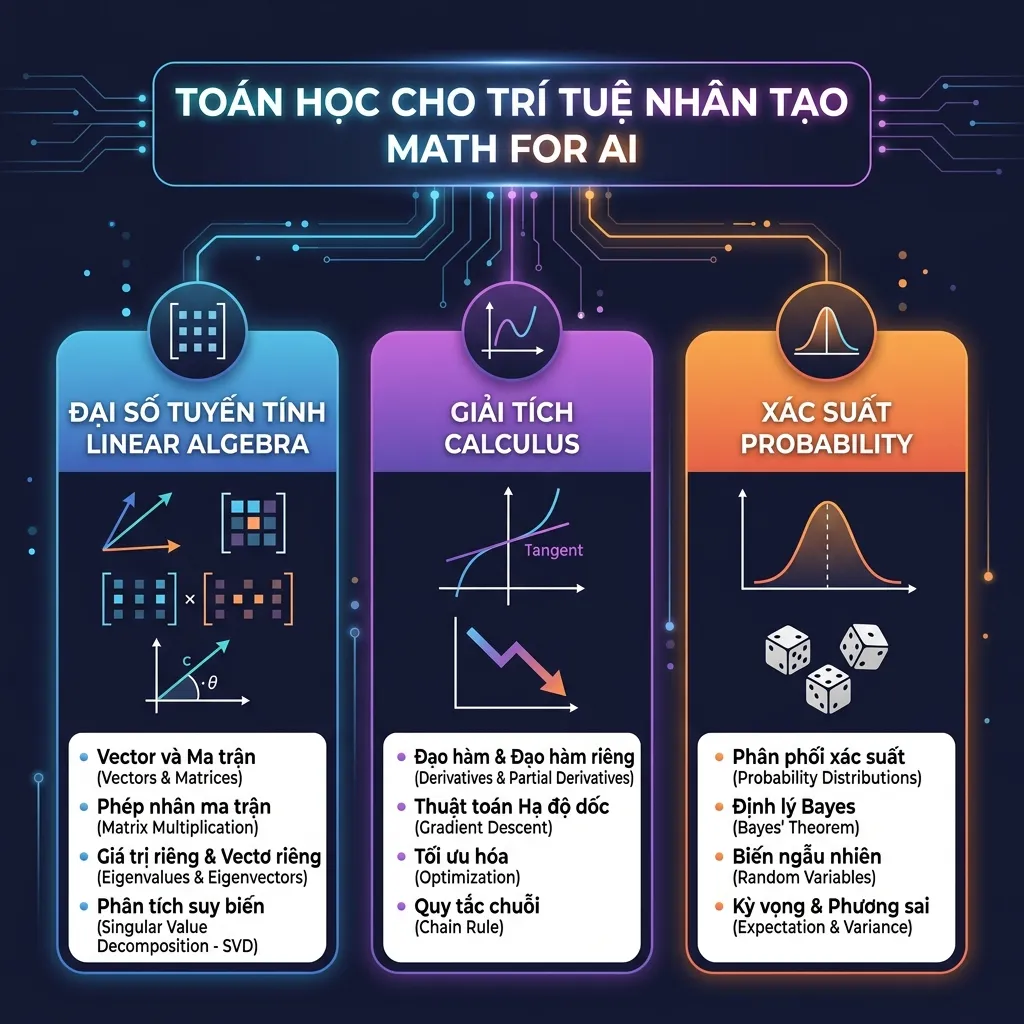
This lesson is divided into 4 main parts:
| Part | You will learn | Why is there a need for AI |
|---|---|---|
| 1. Linear Algebra | Vector, Matrix, Dot Product | Data representation & transformation |
| 2. Calculus | Derivative, Chain Rule | Know how to "learn" — model tuning |
| 3. Gradient Descent | Optimization algorithm | How AI is actually trained |
| 4. Probability | Probability, Softmax | Output & model evaluation |
import numpy as np
import matplotlib.pyplot as plt

# Thiết lập seed để kết quả tái tạo được
np.random.seed(42)
1. Linear Algebra — Linear algebra
Quick summary
💡 One sentence: Linear Algebra helps AI represent and transform data. Everything in AI — words, images, sounds — is converted into numbers (vector/matrix) for the computer to process.
1.1 Scalar, Vector, Matrix, Tensor — Simple explanation
Imagine you're describing the weather:
- Scalar = "Today 37°C" → only 1 number
- Vector = "Today 37°C, humidity 80%, wind 15km/h" → 1 row of numbers (multidimensional description)
- Matrix = Weather table for the whole week (7 days × 3 indicators) → number table
- Tensor = Weather data of 50 cities × 365 days × 3 indices → multiple stacked tables
| Concept | Real life example | Examples in AI |
|---|---|---|
| Scalar | Temperature: 37°C | Learning rate: 0.001 |
| Vector | GPS coordinates: (10.8°, 106.6°) | Embedding of the word "cat": [0.2, -0.5, 0.8, ...] |
| Matrix | Class transcript (student × subject) | Batch of word embeddings |
| Tensor | Video (frame × height × width × color) | Batch of sequences in LLM |
In short: Scalar = 1 number, Vector = 1 row of numbers, Matrix = table of numbers, Tensor = multiple stacked tables of numbers.
# Scalar — số vô hướng (1 giá trị duy nhất)
learning_rate = 0.001  # Tốc độ học
temperature = 0.7      # "Sáng tạo" khi sinh text

# Vector — mảng 1 chiều
# Ví dụ: vị trí một quán cafe trên Google Maps cần 2 số (lat, long)
# Trong AI: mỗi từ được biểu diễn bằng hàng trăm số
word_embedding = np.array([0.2, -0.5, 0.8, 0.1, -0.3])
print(f"Vector shape: {word_embedding.shape}")  # (5,)

# Matrix — mảng 2 chiều (bảng)
# Ví dụ: bảng điểm 8 học sinh × 3 môn
# Trong AI: 8 tokens × 512 chiều embedding
batch_embeddings = np.random.randn(8, 512)
print(f"Matrix shape: {batch_embeddings.shape}")  # (8, 512)

# Tensor — mảng n chiều
# Ví dụ: 32 câu × 128 từ/câu × 512 chiều embedding
batched_sequences = np.random.randn(32, 128, 512)
print(f"Tensor shape: {batched_sequences.shape}")  # (32, 128, 512)
💡 Exercise 1.1: If you have 100 color photos, each photo is 224×224 pixels, 3 color channels (RGB). What shape does this tensor have? Write code to create that random tensor using NumPy.
1.2 Dot Product — "Measuring similarity"
Normal life example: You want to know if two people have similar interests. Each person rates 3 movie genres (action, romance, horror) from 1→5:
- An: [5, 1, 4] (likes action & horror)
- Binh: [4, 2, 5] (also likes action & horror)
- Chi: [1, 5, 1] (only likes feelings)
Dot product will give a large number if the preferences are the same, small if they are different.
an   = np.array([5, 1, 4])
binh = np.array([4, 2, 5])
chi  = np.array([1, 5, 1])

# Dot product: nhân tương ứng rồi cộng
# An · Bình = 5×4 + 1×2 + 4×5 = 20 + 2 + 20 = 42 → GẦN!
# An · Chi  = 5×1 + 1×5 + 4×1 = 5 + 5 + 4 = 14 → XA!
print(f"An · Bình = {np.dot(an, binh)}")  # 42 (tương đồng cao)
print(f"An · Chi  = {np.dot(an, chi)}")   # 14 (tương đồng thấp)
Why is it important in AI? This is exactly how the Attention mechanism works — measuring the degree of "relatedness" between words in a sentence! When ChatGPT reads "The cat is lying on the chair", it uses dot product to know that "lying" is more strongly related to "cat" than to "chair".
# Cosine Similarity — dot product đã "chuẩn hóa" (từ -1 đến 1)
# Giống đo góc giữa 2 mũi tên:
#   - Cùng hướng = 1 (rất giống)
#   - Vuông góc = 0 (không liên quan)
#   - Ngược hướng = -1 (trái ngược)
def cosine_similarity(v1, v2):
    return np.dot(v1, v2) / (np.linalg.norm(v1) * np.linalg.norm(v2))

print(f"Cosine(An, Bình) = {cosine_similarity(an, binh):.4f}")  # ~0.96 (rất giống)
print(f"Cosine(An, Chi)  = {cosine_similarity(an, chi):.4f}")   # ~0.39 (khác nhiều)
💡 Exercise 1.2:
- Add a person "Dung" with preferences [3, 3, 3] (like equally). Calculate the cosine similarity of Dung with An, Binh, Chi. Who resembles Dung the most?
- Think about it: If "Ha" has preferences [10, 2, 8] (same as An but double), what is the cosine similarity between An and Ha? Why is the result like that?
1.3 Matrix Multiplication — "Data Transformation"
Normal life example: You have a coffee menu (3 types of drinks) and ingredient prices. You want to calculate the price of each type of water:
| Coffee (g) | Milk (ml) | Sugar (g) | |
|---|---|---|---|
| Stone black | 20 | 0 | 10 |
| Iced milk | 15 | 50 | 15 |
| Undercut | 10 | 80 | 20 |
Raw material prices: Coffee = 500 VND/g, Milk = 30 VND/ml, Sugar = 50 VND/g
# Menu (3 loại nước × 3 nguyên liệu)
menu = np.array([
    [20, 0,  10],   # Đen đá
    [15, 50, 15],   # Sữa đá
    [10, 80, 20],   # Bạc xỉu
])

# Giá nguyên liệu (3 nguyên liệu × 1 giá)
gia = np.array([[500], [30], [50]])

# Nhân ma trận = tính giá mỗi loại nước!
gia_nuoc = menu @ gia
print("Giá mỗi loại nước:")
for ten, g in zip(["Đen đá", "Sữa đá", "Bạc xỉu"], gia_nuoc):
    print(f"  {ten}: {int(g[0]):,}đ")
# Đen đá: 10,500đ  |  Sữa đá: 9,750đ  |  Bạc xỉu: 8,400đ
Shape rule: When multiplying A (m×n) with B (n×p), the result is shape (m×p). The number of columns in A **must be equal to the number of rows in B.
(3, 3) @ (3, 1) = (3, 1)   ✅ 3 loại nước × 1 giá
(8, 768) @ (768, 256) = (8, 256)   ✅ Trong neural network
(3, 3) @ (2, 1) = ???       ❌ 3 ≠ 2, không nhân được!
In Neural Network: Each linear layer is exactly a matrix multiplication — transforming input data into a new form.
# Neural network layer: output = input × W + b
batch_size, input_dim, output_dim = 32, 768, 256
X = np.random.randn(batch_size, input_dim)      # 32 câu, 768 chiều
W = np.random.randn(input_dim, output_dim) * 0.02  # Trọng số
b = np.zeros(output_dim)                         # Bias
output = X @ W + b
print(f"Linear layer: ({batch_size}, {input_dim}) → ({output.shape})")
💡 Exercise 1.3:
- Write a function
matrix_multiply(A, B)from the beginning with 3 loopsfor(not used@nicenp.dot). Check the results by comparing withA @ B.- If the input has shape (16, 512) and you want to output shape (16, 128), what shape must matrix W have?
1.4 Transpose and Norm
# Transpose — "lật" bảng (hàng → cột, cột → hàng)
# Ví dụ: bạn có bảng điểm (học sinh × môn), lật thành (môn × học sinh)
M = np.array([[1, 2, 3], [4, 5, 6]])  # (2 hàng, 3 cột)
print(f"M shape: {M.shape}")      # (2, 3)
print(f"M.T shape: {M.T.shape}")  # (3, 2) — lật!

# L2 Norm — "độ dài" vector (khoảng cách từ gốc)
# Ví dụ: bạn ở vị trí (3, 4), cách gốc tọa độ bao xa?
v = np.array([3.0, 4.0])
norm = np.linalg.norm(v)  # sqrt(3² + 4²) = 5.0
print(f"Khoảng cách: {norm}")

# Normalize — biến vector thành "vector đơn vị" (dài = 1)
# Giống như: giữ nguyên hướng đi nhưng quy về cùng 1 bước chân
# Rất quan trọng trong AI — word embeddings luôn được normalize!
v_unit = v / np.linalg.norm(v)
print(f"Unit vector: {v_unit}, length = {np.linalg.norm(v_unit):.6f}")  # 1.0
💡 Exercise 1.4: Given 3 vectors: a = [1, 0, 0], b = [0, 1, 0], c = [1, 1, 0]. Normalize vector c and then calculate the cosine similarity between c (normalized) and a, b. Compare the results with before normalization.
2. Calculus — Calculus
Quick summary
💡 One sentence: Calculus tells the AI how it should be adjusted to predict better. Derivative = "rate of change" = "direction to go".
2.1 Derivative — "Rate of change"
Normal life example: You drive a car, the speedometer shows 60 km/h. This number is the derivative of distance over time — it tells you how fast the distance is changing.
Another more familiar example:
- You are losing weight. This week you lost 0.5 kg → weight derivative over time = -0.5 kg/week
- Next week you only lose 0.1 kg → derivative = -0.1 → the rate of loss slows down!
In AI: The derivative shows how loss is changing when we change the weights — from there we know in which direction to adjust the weights.
# f(x) = x² → f'(x) = 2x
# Tại x=3: f'(3) = 6 → nếu x tăng 1 nhỏ, f(x) tăng ~6
def f(x):
    return x**2

# Cách tính đạo hàm bằng số (không cần biết công thức)
# Ý tưởng: lấy 2 điểm rất gần nhau, tính độ dốc
# f'(x) ≈ [f(x + h) - f(x - h)] / (2h)
def numerical_gradient(func, x, h=1e-5):
    return (func(x + h) - func(x - h)) / (2 * h)

x = 3.0
print(f"f'(3) công thức: {2*x}")                    # 6.0
print(f"f'(3) tính số:   {numerical_gradient(f, x):.6f}")  # 6.000000
💡 Exercise 2.1:
- Let f(x) = x³ - 2x. Calculate f'(x) using the formula (3x² - 2) and equal to
numerical_gradient. Compare the results at x = 2.- Let f(x) = sin(x). Use
numerical_gradientto calculate f'(0), f'(π/2), f'(π). Compare with the theoretical value cos(x).
2.2 Partial Derivatives — "Partial Derivatives"
Normal life example: You are baking a cake. Quality depends on temperature and time:
- If you only increase the temperature (keep the time the same) → how will the cake change? → Partial derivative with temperature
- If you only increase time (keep the temperature the same) → how will the cake change? → Partial derivative over time
In AI: Models have millions of weights (parameters). The partial derivative says: "If I just change this weight w₁₂₃₄₅, will the loss increase or decrease?". Calculate partial derivatives for all weights = gradient — vector indicating the fastest loss direction.
# f(x, y) = x² + 3xy + y²
# ∂f/∂x = 2x + 3y  (đạo hàm theo x, coi y là hằng số)
# ∂f/∂y = 3x + 2y  (đạo hàm theo y, coi x là hằng số)

def f_multi(x, y):
    return x**2 + 3*x*y + y**2

h = 1e-5
x, y = 2.0, 1.0

# Tính đạo hàm riêng bằng số
# Cách làm: giữ nguyên biến kia, chỉ thay đổi biến cần tính
df_dx = (f_multi(x + h, y) - f_multi(x - h, y)) / (2 * h)
df_dy = (f_multi(x, y + h) - f_multi(x, y - h)) / (2 * h)

print(f"∂f/∂x tại (2,1): {df_dx:.4f} (lý thuyết: {2*x + 3*y})")  # 7.0
print(f"∂f/∂y tại (2,1): {df_dy:.4f} (lý thuyết: {3*x + 2*y})")  # 8.0
print(f"Gradient = [{df_dx:.1f}, {df_dy:.1f}]")  # [7.0, 8.0] — hướng loss tăng nhanh nhất
💡 Exercise 2.2: Let f(x, y) = (x - 3)² + (y + 2)². This is a "paraboloid" function with a base at (3, -2). Calculate the gradient at (0, 0) and at (3, -2). What is the gradient at the base? Why?
2.3 Chain Rule — "Chain Rule"
Normal life example: You want to know how much gasoline price affects beef noodle price?
Giá xăng ↑10% → Chi phí vận chuyển ↑5% → Giá thịt bò ↑3% → Giá bún bò ↑2%
Total direct impact? Multiply the ratios together: 10% × 0.5 × 0.6 × 0.67 ≈ 2%
This is the chain rule: when f depends on g, g depends on x → df/dx = df/dg × dg/dx.
Why so important? Because it is the foundation of Backpropagation — how neural networks "learn". In a 100-layer network, the chain rule allows calculating the gradient from output back to input through all layers.
# z = (x² + 1)³
# Chia thành 2 bước: g(x) = x² + 1, rồi f(g) = g³
# Chain rule: dz/dx = f'(g) × g'(x) = 3g² × 2x = 3(x²+1)² × 2x

def z(x):
    return (x**2 + 1)**3

x = 2.0
# Theo chain rule: 3 × (4+1)² × (2×2) = 3 × 25 × 4 = 300
analytical = 3 * (x**2 + 1)**2 * (2 * x)
numerical = numerical_gradient(z, x)

print(f"dz/dx công thức: {analytical}")       # 300.0
print(f"dz/dx tính số:   {numerical:.4f}")     # 300.0000
💡 Exercise 2.3:
- Let y = sin(x²). Calculate dy/dx using chain rule: cos(x²) × 2x. Check by
numerical_gradientat x = 1.- More practical: For a simple neural network: output = sigmoid(w × x + b). With sigmoid(z) = 1/(1+e^(-z)). Calculate d(output)/dw using chain rule when x=2, w=0.5, b=0.
3. Gradient Descent — Neural Network's "learning algorithm".
Quick summary
💡 One sentence: Gradient Descent is how AI automatically finds the best set of parameters by "going downhill" on the loss surface.
3.1 Visual
Normal life example: You stand on a mountain in dense fog — unable to see anything. You want to go to the foot of the mountain (find the minimum). The only way: feel the ground around your feet, find the steepest direction, take a small step down. Repeat.
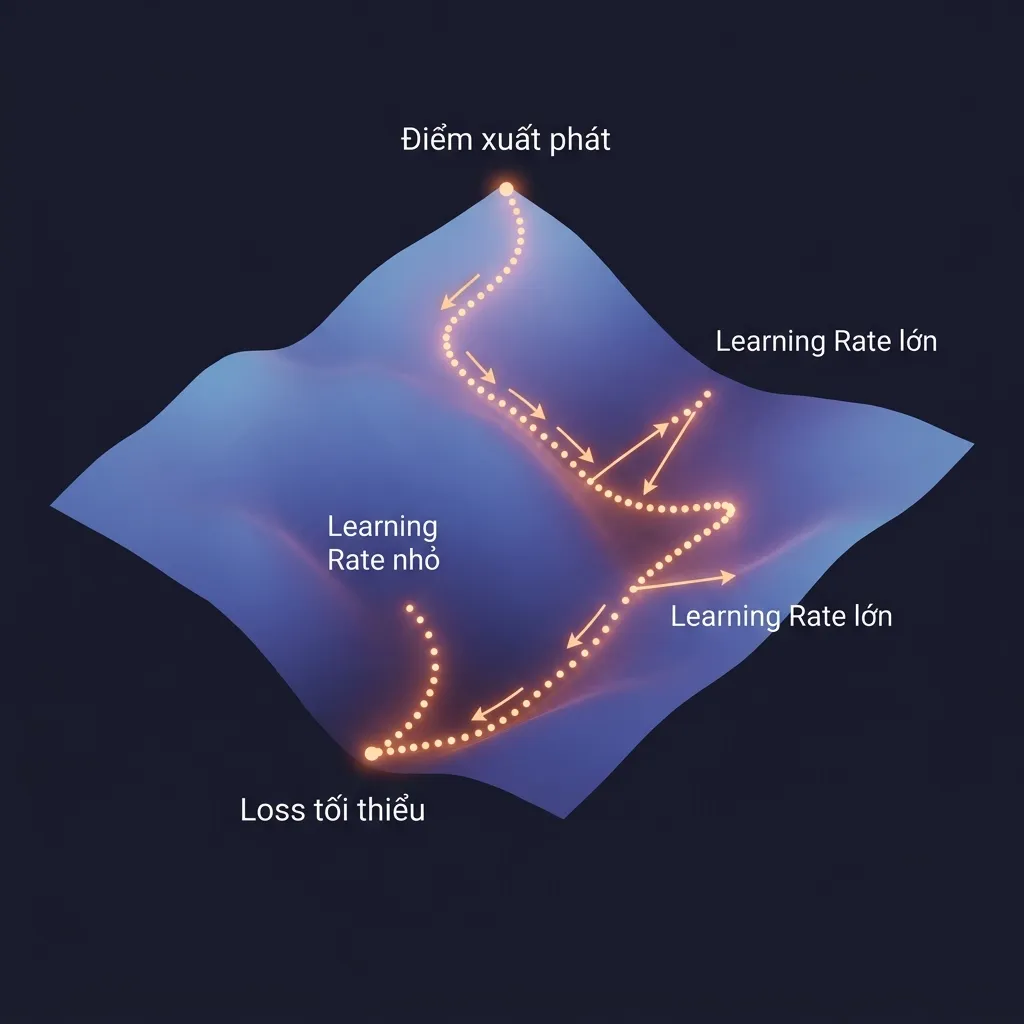
θ_new = θ_old - α × ∇L(θ)
  ↑         ↑      ↑
  vị trí   learning  hướng dốc
  mới      rate      nhất
α(learning rate) = step size- Too small → steps never reach (requires 100,000 epochs)
- Too large → jumps back and forth, does not converge (loss increases!)
- Moderate → fast and stable convergence
∇L(θ)= steepest direction (gradient)- Minus sign: goes opposite to the gradient direction (gradient indicates increasing direction, we want to decrease)
3.2 Demo: Fit line y = wx + b
Problem: Given data, find w and b such that y ≈ wx + b. This is the first step that every neural network must go through!
# Dữ liệu thật: y = 3x + 1.5 + noise
np.random.seed(42)
X = np.linspace(-2, 2, 100)
y_true = 3 * X + 1.5 + np.random.randn(100) * 0.3

# Bắt đầu với w, b ngẫu nhiên (chưa biết đáp án)
w = np.random.randn()  # w ban đầu
b = np.random.randn()  # b ban đầu
lr = 0.01
n = len(X)

print(f"Ban đầu: w={w:.3f}, b={b:.3f} (cần tìm: w≈3.0, b≈1.5)")

for epoch in range(500):
    # Bước 1: Dự đoán (Forward Pass)
    y_pred = w * X + b

    # Bước 2: Tính sai số (Loss = Mean Squared Error)
    loss = np.mean((y_pred - y_true) ** 2)

    # Bước 3: Tính gradient (hướng cần điều chỉnh)
    # "w cần thay đổi bao nhiêu?" và "b cần thay đổi bao nhiêu?"
    dL_dw = np.mean(2 * (y_pred - y_true) * X)
    dL_db = np.mean(2 * (y_pred - y_true))

    # Bước 4: Cập nhật w, b (đi ngược hướng gradient)
    w -= lr * dL_dw
    b -= lr * dL_db

    if epoch % 100 == 0:
        print(f"  Epoch {epoch:3d} | Loss: {loss:.4f} | w={w:.3f}, b={b:.3f}")

print(f"\nKết quả: w={w:.4f} (≈3.0), b={b:.4f} (≈1.5) ✅")
3.3 Gradient Descent Variations
| Variants | Every time you update, use | Advantages | Disadvantages | Real life example |
|---|---|---|---|---|
| Batch GD | Entire dataset | Accurate gradient | Slow, consumes RAM | Read all 1000 reviews and then decide |
| SGD | 1 random sample | Quick, exit local min | Fluctuating a lot | Read 1 review then decide immediately |
| Mini-batch | 32–256 samples | Good balance | Need to tune batch size | Read 32 reviews then decide |
| Adam | Mini-batch + adaptive lr | Fast and stable convergence | Multiple hyperparameters | Read 32 reviews + adjust reading speed |
Fact: Almost every AI model today uses Adam or AdamW — you will encounter them continuously from lesson 3 onwards.
💡 Exercise 3:
- Try changing
lr = 0.1(larger). Observe whether the loss converges. Then trylr = 0.0001(too small) — how many epochs does it take to converge?- Challenge: Modify the gradient descent code above to fit the parabola y = ax² + bx + c. Hint: need 3 variables a, b, c and 3 gradients.
4. Probability — Probability
Quick summary
💡 One sentence: Probability helps AI make predictions with confidence — instead of saying "this is a cat", the AI says "90% this is a cat, 8% dog, 2% rabbit".
4.1 Bayes Theorem — "Updating beliefs"
Normal life example: You receive an email. Before reading, you estimate that 30% of emails are spam (personal experience). After seeing an email containing the word "money" — you update your beliefs: how much does the likelihood of spam increase?
- In spam emails, 80% contain the word "money"
- In normal emails, 10% contain the word "money"
# Bayes: P(spam|tiền) = P(tiền|spam) × P(spam) / P(tiền)
# Đọc: "Xác suất spam BIẾT RẰNG có từ tiền"

p_spam = 0.3                    # Prior: niềm tin ban đầu
p_ham = 0.7
p_tien_spam = 0.8               # P(tiền|spam): 80% spam có từ "tiền"
p_tien_ham = 0.1                # P(tiền|ham): 10% email thường có từ "tiền"

# P(tiền) = tổng xác suất gặp từ "tiền" trong mọi loại email
p_tien = p_tien_spam * p_spam + p_tien_ham * p_ham
print(f"P(gặp từ 'tiền' bất kỳ): {p_tien:.2f}")  # 0.31

# P(spam | tiền) — xác suất spam sau khi thấy từ "tiền"
p_spam_tien = (p_tien_spam * p_spam) / p_tien
print(f"P(spam | có từ 'tiền'): {p_spam_tien:.1%}")  # 77.4%
# → Từ 30% nghi ngờ, giờ tăng lên 77.4% chắc chắn là spam!
In AI: Bayes' theorem is the foundation of many classic ML algorithms (Naive Bayes, Bayesian Neural Networks). Bayesian thinking — "updating beliefs as more evidence becomes available" — runs throughout AI.
💡 Exercise 4.1: If the email also contains the word "free" (P("free"|spam) = 0.6, P("free"|ham) = 0.05), update the spam probability by applying Bayes again (using the result 77.4% as the new prior). What is the probability of spam now?
4.2 Softmax — "Converting scores to probabilities"
Normal life example: LLM just read "The cat is..." and gave scores (logits) for the next 5 words. But "score" doesn't make intuitive sense — we need to convert it to probability (sum = 100%):
| From | Score (logits) | Probability (softmax) |
|---|---|---|
| "sleep" | 2.1 | 33.9% |
| "eat" | 1.5 | 18.6% |
| "run" | 0.3 | 5.6% |
| "fly" | -0.8 | 1.9% |
| "read" | 1.9 | 27.8% |
Softmax does two things: (1) turns every number positive, (2) normalizes the sum = 1.
def softmax(x):
    x_shifted = x - np.max(x)  # Trừ max để tránh overflow (e^1000 = ∞!)
    exp_x = np.exp(x_shifted)  # Biến thành dương
    return exp_x / np.sum(exp_x)  # Chuẩn hóa tổng = 1

logits = np.array([2.1, 1.5, 0.3, -0.8, 1.9])
probs = softmax(logits)

tokens = ["ngủ", "ăn", "chạy", "bay", "đọc"]
print("Xác suất từ tiếp theo:")
for token, p in zip(tokens, probs):
    bar = "█" * int(p * 50)
    print(f"  '{token}': {p:.1%} {bar}")

print(f"\nTổng: {probs.sum():.6f}")  # Luôn = 1.0
Output:
  'ngủ':  33.9% █████████████████
  'ăn':   18.6% █████████
  'chạy':  5.6% ██
  'bay':   1.9%
  'đọc':  27.8% █████████████
Interesting note: When using ChatGPT, parameter
temperatureControl the "creativity level": high temperature → more uniform probability (creativity), low temperature → focus on from the highest point (less creativity).
💡 Exercise 4.2:
- Implement softmax with temperature:
softmax(x / T). Try T=0.5, T=1.0, T=2.0 with the above logits. Observe how the probability distribution changes.- When T → 0, what result will softmax give? What happens when T → ∞?
4.3 Cross-Entropy Loss — "Measuring the wrong level"
Normal life example: Multiple choice test with 4 answers (A, B, C, D). The correct answer is B.
- You confidently choose B (90%) → you are almost correct → low loss
- You confidently choose D (90%) → you are wrong → very high loss
- You randomly guess 25% for each answer → average loss
Cross-entropy heavy penalty when the model is confident but wrong!
# Đáp án đúng: từ tiếp theo là "ngủ" (index 0)
y_true = np.array([1, 0, 0, 0, 0])  # One-hot: chỉ "ngủ" = 1

# Dự đoán tốt: model tự tin "ngủ" đúng
y_good = softmax(np.array([3.0, 0.5, 0.1, -1.0, 0.5]))
# Dự đoán tệ: model nghĩ là "bay"
y_bad  = softmax(np.array([-1.0, 0.5, 0.1, 3.0, 0.5]))

def cross_entropy(y_true, y_pred, eps=1e-15):
    y_pred = np.clip(y_pred, eps, 1)  # Tránh log(0) = -∞
    return -np.sum(y_true * np.log(y_pred))

print(f"Loss (dự đoán tốt): {cross_entropy(y_true, y_good):.4f}")  # Nhỏ ≈ 0.1
print(f"Loss (dự đoán tệ):  {cross_entropy(y_true, y_bad):.4f}")   # Lớn ≈ 4.0

# Perplexity = "mức bối rối" = exp(loss)
# PPL thấp = model ít bối rối = dự đoán tốt
# PPL = 1 → hoàn hảo, PPL = 50000 → đoán bừa
avg_loss = 2.3
ppl = np.exp(avg_loss)
print(f"\nPerplexity: {ppl:.2f} (mô hình tốt thường < 20)")
💡 Exercise 4.3:
- Calculate cross-entropy manually (using a calculator) for: y_true = [0, 1, 0], y_pred = [0.1, 0.8, 0.1]. Hint: -log(0.8) = ?
- If the model predicts perfectly y_pred = [0, 1, 0], cross-entropy = ? Why?
- Practical Contact: When you see ChatGPT reporting perplexity = 3.5 for a model, what does that mean?
Lesson summary
| Topics | Simple understanding | Applications in AI |
|---|---|---|
| Dot product | Measuring the similarity of two vectors | Attention mechanism |
| Matrix mul | Transform data through "filters" | Linear layers |
| Derivative | Rate of change | Know how to adjust |
| Chain rule | Multiply the influence ratio | Backpropagation |
| Gradient descent | Go downhill to find the bottom | Train any model |
| Softmax | Score → probability | Output layer of LLM |
| Cross-entropy | Measuring the "wrong" level | Loss function training |
General exercises
- ✅ Complete all small exercises in each section (1.1, 1.2, 1.3, 1.4, 2.1, 2.2, 2.3, 3, 4.1, 4.2, 4.3)
- Implement Gradient Descent to find the minimum of
f(x, y) = (x-3)² + (y+2)²from the starting point (0, 0). The result should be (3, -2) - Mini-project: Create a simple "recommend movies" system:
- For 5 users, each user rates 4 movies (1→5)
- Use cosine similarity to find the most similar users
- Suggest movies that user A has not seen but users like A like
- Read the abstract of the original article "Attention Is All You Need" (2017) at
arxiv.org/abs/1706.03762— find out where and why the article mentions "dot product".
Next lesson: We will use this math to build Neural Networks from scratch — neural networks, the core of every AI model.