1. Introduction: From Class Labels to Text Prompts
In the previous lesson, you implemented Classifier-Free Guidance (CFG) with class labels (digits 0–9). But Stable Diffusion doesn't use class labels — it uses free-form text prompts. So how do we convert "a photo of a cat" into a tensor that U-Net can understand?
The answer lies in CLIP (Contrastive Language-Image Pretraining) — the bridge model between language and images, introduced by OpenAI in 2021. This is the final lesson in the Diffusion Models section, combining all the knowledge you've learned to build a full text-to-image pipeline.
Exam tip: DLI assessment S-FX-14 requires you to combine U-Net, DDPM, CFG, and text conditioning into a complete pipeline. This lesson is the "grand synthesis" — if you thoroughly understand each component from Lessons 3–4 and connect them in Lesson 5, you'll complete the assessment faster.
Roadmap: Class Label → Text Prompt Conditioning
════════════════════════════════════════════════

  Lesson 3: U-Net backbone          → Denoiser architecture
  Lesson 4: DDPM + CFG              → Training & sampling with class labels
  Lesson 5: CLIP + Cross-Attention  → Text-to-image pipeline ← YOU ARE HERE
        │
        ▼
  ┌──────────────────────────────────────────────────────────┐
  │  "a sunset over mountains"                               │
  │         │                                                │
  │         ▼                                                │
  │   ┌──────────┐   ┌──────────────────┐   ┌──────────┐   │
  │   │   CLIP   │──►│  Cross-Attention  │──►│  U-Net   │   │
  │   │ Encoder  │   │  (K, V from text) │   │ Denoise  │   │
  │   └──────────┘   └──────────────────┘   └──────────┘   │
  │                                              │          │
  │                                              ▼          │
  │                                        [ 🖼️ Image ]     │
  └──────────────────────────────────────────────────────────┘
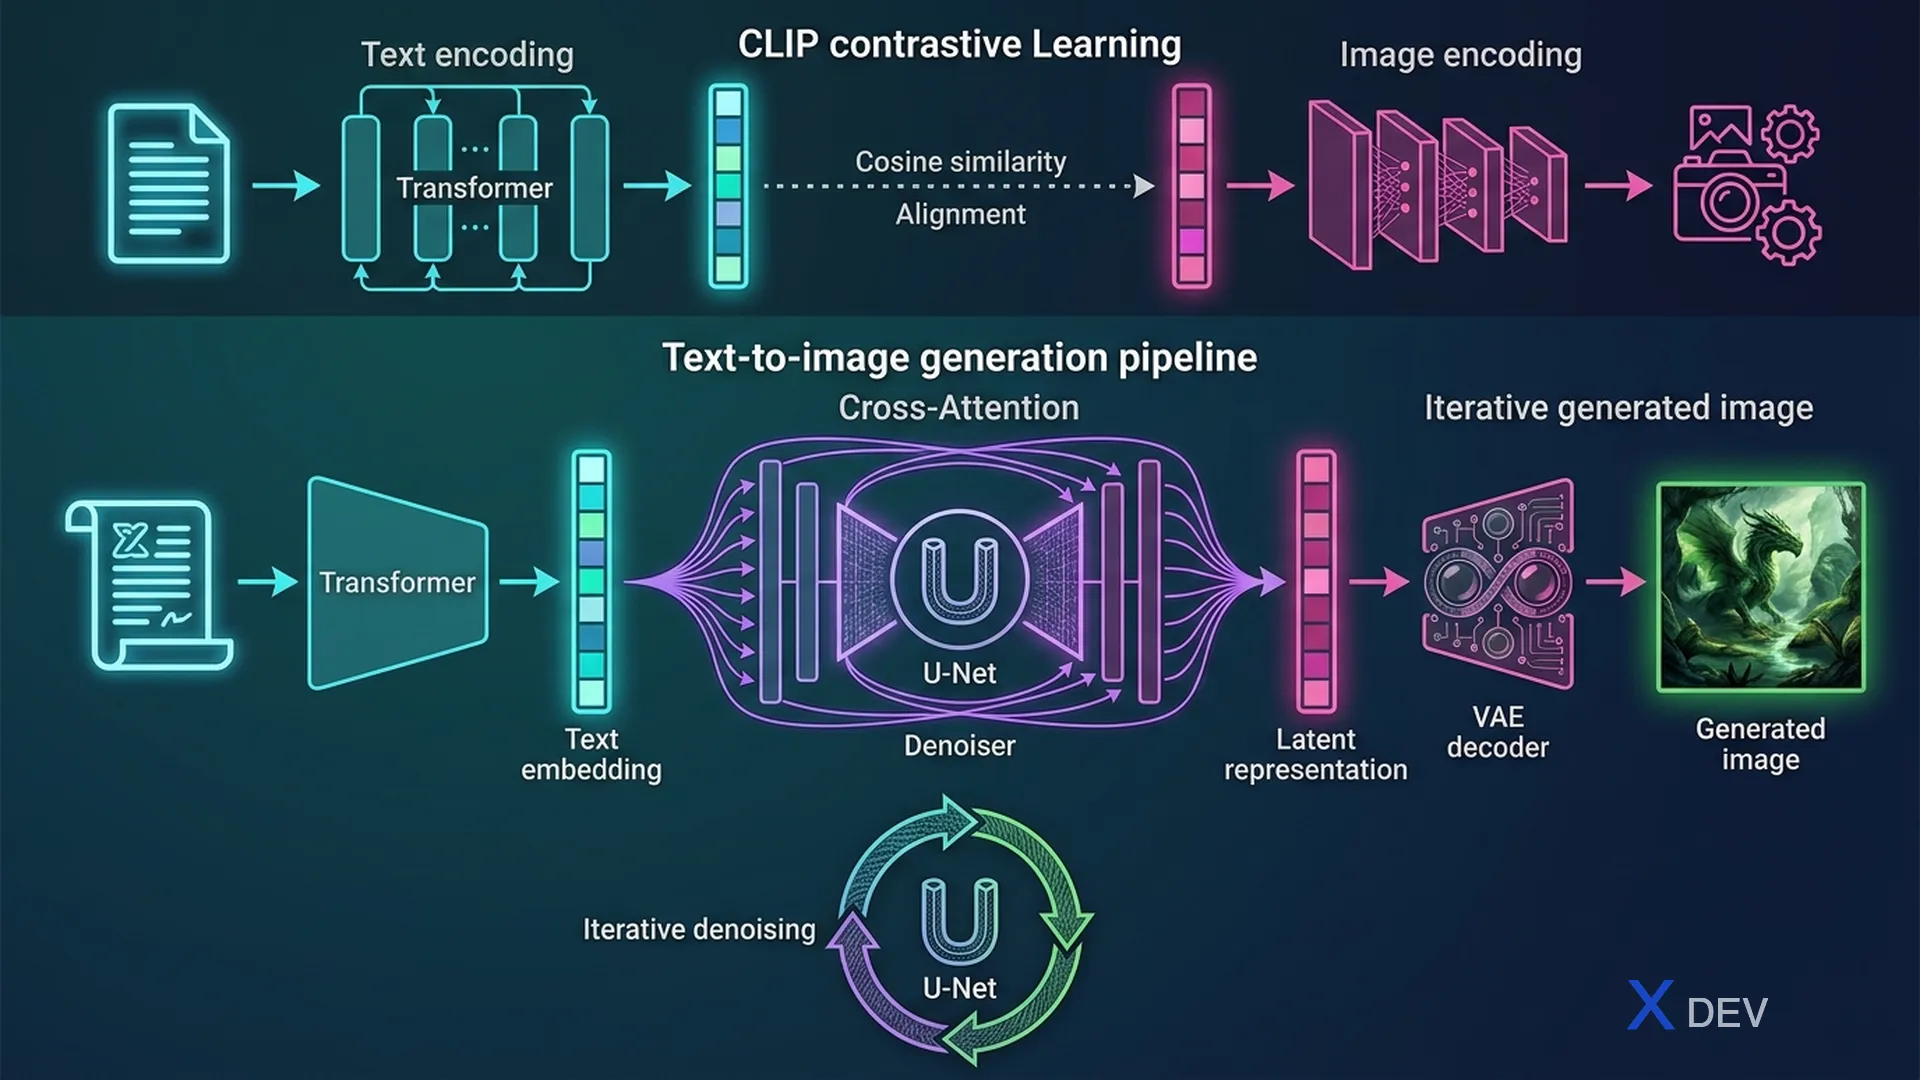
2. CLIP — Contrastive Language-Image Pretraining
2.1 Dual-Encoder Architecture
CLIP consists of two encoders trained simultaneously on 400 million (text, image) pairs from the internet:
- Text Encoder: Transformer (similar to GPT) — takes text → outputs embedding vector (512-d or 768-d)
- Image Encoder: ViT (Vision Transformer) or ResNet — takes image → outputs embedding of the same dimension
The key point: both encoders output embeddings in the same vector space. This allows direct comparison of text and images using cosine similarity.
CLIP Architecture — Dual Encoder
═════════════════════════════════

  TEXT BRANCH                          IMAGE BRANCH
  ───────────                          ────────────

  "a photo of    ┌───────────────┐     ┌─────┐   ┌───────────────┐
   a cat"    ──► │ Text Encoder  │     │ 🖼️  │──►│ Image Encoder │
                 │ (Transformer) │     │     │   │ (ViT / ResNet)│
                 └───────┬───────┘     └─────┘   └───────┬───────┘
                         │                                │
                         ▼                                ▼
                  ┌──────────────┐                 ┌──────────────┐
                  │ Text Embed.  │                 │ Image Embed. │
                  │ (768-dim)    │                 │ (768-dim)    │
                  └──────┬───────┘                 └──────┬───────┘
                         │                                │
                         └────────────┬───────────────────┘
                                      │
                                      ▼
                              ┌───────────────┐
                              │    Cosine      │
                              │  Similarity    │
                              │  sim(t, i)     │
                              └───────────────┘

  Training (400M image-text pairs):
  ┌──────────────────────────────────────────────────────┐
  │  Maximize sim(text_i, image_i)    ← matched pairs    │
  │  Minimize sim(text_i, image_j)    ← non-matched      │
  └──────────────────────────────────────────────────────┘
2.2 Contrastive Loss
CLIP uses a symmetric cross-entropy loss on an NxN similarity matrix. With a batch of N (text, image) pairs:
Contrastive Loss — Similarity Matrix
═════════════════════════════════════

  Batch N = 4 pairs (text, image):

              image_0   image_1   image_2   image_3
            ┌─────────┬─────────┬─────────┬─────────┐
  text_0    │  0.95 ✓ │  0.12   │  0.08   │  0.03   │
            ├─────────┼─────────┼─────────┼─────────┤
  text_1    │  0.10   │  0.91 ✓ │  0.15   │  0.07   │
            ├─────────┼─────────┼─────────┼─────────┤
  text_2    │  0.05   │  0.11   │  0.93 ✓ │  0.09   │
            ├─────────┼─────────┼─────────┼─────────┤
  text_3    │  0.08   │  0.06   │  0.12   │  0.89 ✓ │
            └─────────┴─────────┴─────────┴─────────┘

  Goal: diagonal (✓) → high, rest → low

  Loss = (CE_rows + CE_cols) / 2
       = cross_entropy(logits, labels) for both dimensions

  logits = temperature * text_embeds @ image_embeds.T
  labels = [0, 1, 2, ..., N-1]   ← identity matching
Temperature parameter (learnable, initialized ~0.07) controls the sharpness of the distribution. Lower temperature → clearer distinction between positive and negative pairs.
| Component | Details | In CLIP |
|---|---|---|
| Text Encoder | 12-layer Transformer, BPE tokenizer | Max 77 tokens, outputs CLS embedding |
| Image Encoder | ViT-B/32 or ViT-L/14 | Splits image into patches, outputs CLS |
| Embedding dim | 512 (ViT-B/32) or 768 (ViT-L/14) | Shared space between text & image |
| Training data | 400M image-text pairs (WIT dataset) | Crawled from the internet |
| Loss function | Symmetric cross-entropy | InfoNCE / NT-Xent variant |
| Temperature | Learnable scalar τ | Init ≈ 0.07, learned during training |
Exam tip: CLIP does not generate images — it only encodes text and images into a shared space. In the text-to-image pipeline, we only use CLIP's Text Encoder to create the conditioning signal for U-Net. The Image Encoder is not used during generation.
3. Using CLIP Encodings in Code
3.1 Load CLIP and Encode Text
import torch
import clip
from PIL import Image

# Load pretrained CLIP model
device = "cuda" if torch.cuda.is_available() else "cpu"
model, preprocess = clip.load("ViT-B/32", device=device)

# ── Encode text ──
text_prompts = ["a photo of a cat", "a sunset over mountains", "a red car"]
text_tokens = clip.tokenize(text_prompts).to(device)  # (3, 77) — padded to 77 tokens

with torch.no_grad():
    text_embeddings = model.encode_text(text_tokens)  # (3, 512)
    text_embeddings = text_embeddings / text_embeddings.norm(dim=-1, keepdim=True)  # L2 normalize

print(f"Text embeddings shape: {text_embeddings.shape}")  # (3, 512)
3.2 Encode Image and Compute Similarity
# ── Encode images ──
images = [preprocess(Image.open(f"img_{i}.jpg")).unsqueeze(0) for i in range(3)]
image_batch = torch.cat(images).to(device)  # (3, 3, 224, 224)

with torch.no_grad():
    image_embeddings = model.encode_image(image_batch)   # (3, 512)
    image_embeddings = image_embeddings / image_embeddings.norm(dim=-1, keepdim=True)

# ── Cosine similarity ──
similarity = text_embeddings @ image_embeddings.T  # (3, 3)
print(similarity)
# tensor([[ 0.31,  0.05,  0.02],    ← "cat" matches image_0
#         [ 0.04,  0.28,  0.06],    ← "sunset" matches image_1
#         [ 0.03,  0.07,  0.26]])   ← "red car" matches image_2
Result: text and images with matching content have the highest similarity. This is the power of the shared embedding space — you can search images by text or vice versa.
3.3 CLIP for Diffusion Models: Sequence Embeddings
Important: Stable Diffusion does not use the CLS embedding (a single vector). Instead, it uses the sequence of token embeddings from CLIP Text Encoder — the output before the projection layer:
CLS Embedding vs Sequence Embeddings
═════════════════════════════════════

  Text: "a photo of a cat"
  Tokenized: [SOS, "a", "photo", "of", "a", "cat", EOS, PAD, PAD, ...]

  CLIP Text Encoder output:
  ┌──────────────────────────────────────────────┐
  │  token_0 (SOS)  → [0.12, -0.34, 0.56, ...]  │
  │  token_1 ("a")  → [0.08, -0.21, 0.43, ...]  │
  │  token_2 ("photo") → [...]                   │
  │  token_3 ("of") → [...]                      │
  │  token_4 ("a")  → [...]                      │
  │  token_5 ("cat")→ [0.91, 0.15, -0.33, ...]  │  ← semantic info
  │  token_6 (EOS)  → [0.67, 0.42, -0.18, ...]  │  ← CLS (used by CLIP)
  │  ...                                         │
  │  token_76 (PAD) → [0.00, 0.00, 0.00, ...]   │
  └──────────────────────────────────────────────┘

  Stable Diffusion uses: ALL 77 token embeddings → (1, 77, 768)
  CLIP zero-shot uses:   ONLY the EOS token embedding → (1, 768)
| Use Case | Output | Shape | Reason |
|---|---|---|---|
| CLIP classification | CLS / EOS token | (B, 768) | Global similarity comparison |
| Stable Diffusion | Full token sequence | (B, 77, 768) | Cross-attention needs per-token info |
Exam tip: If the question asks "What is the shape of the text conditioning input to the U-Net?", the answer is (batch, 77, 768) — NOT (batch, 768). Cross-attention needs a sequence, not a single vector.
4. Cross-Attention: Injecting Text Embeddings into U-Net
4.1 Cross-Attention Mechanism
In Lesson 3, U-Net used self-attention — Q, K, V all come from image features. Cross-attention changes the source of K and V:
Self-Attention vs Cross-Attention
═════════════════════════════════

  SELF-ATTENTION (in U-Net):
  ───────────────────────────────
  Q = W_q · image_features    ← from image
  K = W_k · image_features    ← from image
  V = W_v · image_features    ← from image

  Attention = softmax(Q · K^T / √d) · V

  CROSS-ATTENTION (text → image):
  ────────────────────────────────
  Q = W_q · image_features    ← from image (queries)
  K = W_k · text_embeddings   ← from CLIP text (keys)
  V = W_v · text_embeddings   ← from CLIP text (values)

  Attention = softmax(Q_image · K_text^T / √d) · V_text

  ┌──────────────────────────────────────────────────┐
  │  Q shape: (B, H*W, d_model)    ← spatial pixels  │
  │  K shape: (B, 77, d_model)     ← text tokens      │
  │  V shape: (B, 77, d_model)     ← text tokens      │
  │  Score:   (B, H*W, 77)        ← pixel-to-token    │
  │  Output:  (B, H*W, d_model)    ← text-aware image │
  └──────────────────────────────────────────────────┘
Each pixel "looks at" all 77 text tokens and decides which token to attend to. Pixels in the cat region will strongly attend to the "cat" token, pixels in the sky region attend to "sky".
4.2 Cross-Attention in U-Net Block
U-Net Block with Cross-Attention
════════════════════════════════

  Input: x (image features, shape: B×C×H×W)
  Condition: text_emb (CLIP output, shape: B×77×768)
  Timestep: t_emb (timestep embedding, shape: B×d)

  ┌─────────────────────────────────────────────┐
  │                U-Net Block                   │
  │                                             │
  │  x ──► [ResBlock + t_emb] ──► x'           │
  │              │                               │
  │              ▼                               │
  │     [Self-Attention]                         │
  │       Q,K,V ← x'                            │
  │              │                               │
  │              ▼                               │
  │     [Cross-Attention]   ◄── text_emb        │
  │       Q ← x'                                │
  │       K,V ← text_emb                        │
  │              │                               │
  │              ▼                               │
  │     [FFN / MLP]                              │
  │              │                               │
  │              ▼                               │
  │           output                             │
  └─────────────────────────────────────────────┘

  Order within each block: ResBlock → Self-Attn → Cross-Attn → FFN
4.3 Implementation: CrossAttention Module
import torch
import torch.nn as nn
import torch.nn.functional as F

class CrossAttention(nn.Module):
    """
    Cross-attention: Q from image features, K/V from text embeddings.
    Used in U-Net blocks to inject text conditioning.
    """
    def __init__(self, d_model, context_dim, n_heads=8):
        super().__init__()
        self.n_heads = n_heads
        self.d_head = d_model // n_heads

        # Q from image, K/V from text
        self.to_q = nn.Linear(d_model, d_model, bias=False)
        self.to_k = nn.Linear(context_dim, d_model, bias=False)
        self.to_v = nn.Linear(context_dim, d_model, bias=False)
        self.out_proj = nn.Linear(d_model, d_model)
        self.norm = nn.LayerNorm(d_model)

    def forward(self, x, context):
        """
        Args:
            x: image features (B, H*W, d_model)
            context: text embeddings from CLIP (B, seq_len, context_dim)
        Returns:
            text-conditioned image features (B, H*W, d_model)
        """
        residual = x
        x = self.norm(x)

        B, N, _ = x.shape
        H = self.n_heads
        d = self.d_head

        # Project to Q, K, V
        Q = self.to_q(x).view(B, N, H, d).transpose(1, 2)       # (B, H, N, d)
        K = self.to_k(context).view(B, -1, H, d).transpose(1, 2) # (B, H, S, d)
        V = self.to_v(context).view(B, -1, H, d).transpose(1, 2) # (B, H, S, d)

        # Scaled dot-product attention
        scale = d ** -0.5
        attn = torch.matmul(Q, K.transpose(-2, -1)) * scale  # (B, H, N, S)
        attn = F.softmax(attn, dim=-1)

        # Weighted sum of values
        out = torch.matmul(attn, V)                     # (B, H, N, d)
        out = out.transpose(1, 2).contiguous().view(B, N, H * d)  # (B, N, d_model)
        out = self.out_proj(out)

        return out + residual  # residual connection
4.4 U-Net Block Combining Self-Attention + Cross-Attention
class TransformerBlock(nn.Module):
    """Single transformer block: Self-Attn → Cross-Attn → FFN"""
    def __init__(self, d_model, context_dim, n_heads=8):
        super().__init__()
        self.self_attn = nn.MultiheadAttention(d_model, n_heads, batch_first=True)
        self.self_attn_norm = nn.LayerNorm(d_model)

        self.cross_attn = CrossAttention(d_model, context_dim, n_heads)

        self.ffn = nn.Sequential(
            nn.LayerNorm(d_model),
            nn.Linear(d_model, d_model * 4),
            nn.GELU(),
            nn.Linear(d_model * 4, d_model),
        )

    def forward(self, x, context):
        # Self-attention
        norm_x = self.self_attn_norm(x)
        attn_out, _ = self.self_attn(norm_x, norm_x, norm_x)
        x = x + attn_out

        # Cross-attention (inject text)
        x = self.cross_attn(x, context)

        # Feed-forward
        x = x + self.ffn(x)
        return x
Exam tip: A common mistake in the assessment: setting K, V from image instead of text. If cross-attention takes K, V from image features → the text prompt will have no effect → output will be the same as unconditional generation. Debug tip: check whether
self.to_kandself.to_vreceive context (text) or x (image).
5. Full Text-to-Image Pipeline
5.1 Overview: Combining All Components
Full Text-to-Image Pipeline
════════════════════════════

  Input: "a golden retriever playing in snow"

  ┌──────────────────────────────────────────────────────────────┐
  │                                                              │
  │  Step 1: TEXT ENCODING                                       │
  │  ─────────────────────                                       │
  │  prompt ──► CLIP Tokenizer ──► CLIP Text Encoder             │
  │                                      │                       │
  │                               text_emb (1, 77, 768)         │
  │                                      │                       │
  │  Step 2: NOISE INITIALIZATION        │                       │
  │  ────────────────────────────        │                       │
  │  x_T ~ N(0, I)  (pure noise)        │                       │
  │       shape: (1, C, H, W)           │                       │
  │              │                        │                       │
  │  Step 3: REVERSE DIFFUSION LOOP     │                       │
  │  ───────────────────────────────     │                       │
  │  for t = T, T-1, ..., 1:            │                       │
  │    │                                  │                       │
  │    ├─► ε̂_uncond = UNet(x_t, t, ∅)   │  ← unconditional     │
  │    ├─► ε̂_cond = UNet(x_t, t, text_emb) ← conditional       │
  │    │                                                         │
  │    ├─► ε̂ = ε̂_uncond + w·(ε̂_cond − ε̂_uncond)   ← CFG      │
  │    │                                                         │
  │    └─► x_{t-1} = denoise_step(x_t, ε̂, t)                   │
  │              │                                               │
  │  Step 4: OUTPUT                                              │
  │  ──────────────                                              │
  │  x_0 = final denoised image                                 │
  │                                                              │
  └──────────────────────────────────────────────────────────────┘
5.2 Implementation: Text-to-Image Sampling
@torch.no_grad()
def text_to_image_sample(
    unet, clip_model, prompt, schedule,
    guidance_scale=7.5, image_size=64, channels=3,
    device='cuda'
):
    """
    Complete text-to-image sampling pipeline.
    Combines CLIP encoding + CFG + DDPM reverse diffusion.
    """
    T = len(schedule['betas'])
    betas = schedule['betas'].to(device)
    alphas = schedule['alphas'].to(device)
    alpha_bar = schedule['alpha_bar'].to(device)

    # ── Step 1: Encode text prompt ──
    text_tokens = clip.tokenize([prompt]).to(device)           # (1, 77)
    text_emb = clip_model.encode_text_sequence(text_tokens)    # (1, 77, 768)

    # Null embedding for unconditional path (CFG)
    null_tokens = clip.tokenize([""]).to(device)
    null_emb = clip_model.encode_text_sequence(null_tokens)    # (1, 77, 768)

    # ── Step 2: Start from pure noise ──
    x_t = torch.randn(1, channels, image_size, image_size, device=device)

    # ── Step 3: Reverse diffusion with CFG ──
    for t in reversed(range(T)):
        t_batch = torch.tensor([t], device=device)

        # Conditional & unconditional predictions
        noise_cond = unet(x_t, t_batch, context=text_emb)     # ε̂_cond
        noise_uncond = unet(x_t, t_batch, context=null_emb)   # ε̂_uncond

        # Classifier-Free Guidance
        noise_pred = noise_uncond + guidance_scale * (noise_cond - noise_uncond)

        # DDPM denoise step
        alpha_t = alphas[t]
        alpha_bar_t = alpha_bar[t]
        beta_t = betas[t]

        # Predicted x_0
        x_0_pred = (x_t - (1 - alpha_bar_t).sqrt() * noise_pred) / alpha_bar_t.sqrt()
        x_0_pred = x_0_pred.clamp(-1, 1)

        if t > 0:
            alpha_bar_prev = alpha_bar[t - 1]
            # Posterior mean
            coeff1 = beta_t * alpha_bar_prev.sqrt() / (1 - alpha_bar_t)
            coeff2 = (1 - alpha_bar_prev) * alpha_t.sqrt() / (1 - alpha_bar_t)
            mean = coeff1 * x_0_pred + coeff2 * x_t

            # Posterior variance
            sigma = (beta_t * (1 - alpha_bar_prev) / (1 - alpha_bar_t)).sqrt()
            z = torch.randn_like(x_t)
            x_t = mean + sigma * z
        else:
            x_t = x_0_pred  # Final step: no noise

    return x_t  # Generated image (1, C, H, W)
5.3 Pipeline Components Summary
| Component | Role | Input → Output | Trainable? |
|---|---|---|---|
| CLIP Text Encoder | Encode text → embeddings | str → (B, 77, 768) | Frozen (pretrained) |
| U-Net (with Cross-Attn) | Predict noise ε̂ | (x_t, t, text_emb) → ε̂ | Yes — main training target |
| Noise Schedule | Define β_t, α_t, ᾱ_t | t → schedule values | No (fixed) |
| CFG | Combine cond/uncond | (ε̂_cond, ε̂_uncond, w) → ε̂ | No (inference only) |
| DDPM Sampler | Denoise step-by-step | (x_t, ε̂, t) → x_{t-1} | No (fixed formula) |
Exam tip: In the assessment, you'll receive a code skeleton with the CLIP encoder and schedule already provided. Your task is to implement the U-Net forward pass (with cross-attention) and the sampling loop (with CFG). Don't try to rewrite CLIP — it's already provided.
6. Latent Diffusion — Stable Diffusion Overview
6.1 The Problem with Pixel-Space Diffusion
The original DDPM performs diffusion directly in pixel space. For a 256×256 RGB image, each diffusion step processes 196,608 dimensions. This is very slow and memory-intensive.
Latent Diffusion Model (LDM) — the foundation of Stable Diffusion — solves this by performing diffusion in a much smaller latent space.
Pixel Space vs Latent Space Diffusion
══════════════════════════════════════

  PIXEL SPACE (original DDPM):
  ────────────────────────
  Image: 256 × 256 × 3 = 196,608 dims
  U-Net must process a VERY large tensor
  ✗ Slow  ✗ High VRAM  ✗ 1000 steps

  LATENT SPACE (Stable Diffusion):
  ─────────────────────────────────
  Image ──► VAE Encoder ──► Latent: 32 × 32 × 4 = 4,096 dims
                                          │
                              48× SMALLER  │
                                          ▼
                              Diffusion in latent space
                                          │
                                          ▼
                            Latent ──► VAE Decoder ──► Image

  ┌───────────────────────────────────────────────────────┐
  │  Stable Diffusion Architecture:                       │
  │                                                       │
  │  "a golden retriever"                                 │
  │         │                                             │
  │         ▼                                             │
  │  ┌──────────┐                                         │
  │  │   CLIP   │──── text_emb (1, 77, 768)              │
  │  │ Encoder  │         │                               │
  │  └──────────┘         │                               │
  │                       ▼                               │
  │  z_T (noise) ──► U-Net (latent) ──► z_0 (latent)    │
  │  (1,4,32,32)    + cross-attn      (1,4,32,32)       │
  │                                        │              │
  │                                        ▼              │
  │                                 ┌──────────┐          │
  │                                 │   VAE    │          │
  │                                 │ Decoder  │          │
  │                                 └────┬─────┘          │
  │                                      │                │
  │                                      ▼                │
  │                               Image (1,3,256,256)     │
  └───────────────────────────────────────────────────────┘
6.2 VAE: Encoder & Decoder
| Component | Pixel Space | Latent Space | Compression |
|---|---|---|---|
| Image size | 256 × 256 × 3 | 32 × 32 × 4 | 48× fewer dims |
| 512 × 512 × 3 | 786,432 dims | 64 × 64 × 4 = 16,384 | 48× fewer dims |
| U-Net input | Full resolution pixels | Compressed latents | Much faster |
| Training cost | Very high (many GPU-days) | Much lower | Feasible on 1 GPU |
# Latent Diffusion — using VAE + U-Net in latent space
from diffusers import AutoencoderKL

# Load pretrained VAE
vae = AutoencoderKL.from_pretrained("stabilityai/sd-vae-ft-mse")
vae = vae.to(device).eval()

# ── Encode image → latent ──
with torch.no_grad():
    # image: (B, 3, 256, 256), normalized to [-1, 1]
    latent = vae.encode(image).latent_dist.sample()  # (B, 4, 32, 32)
    latent = latent * 0.18215  # scaling factor (Stable Diffusion convention)

# ── Diffusion happens in latent space ──
# x_T = torch.randn(1, 4, 32, 32)  ← noise in latent space
# ... reverse diffusion loop on latents ...

# ── Decode latent → image ──
with torch.no_grad():
    latent_decoded = latent / 0.18215
    image_out = vae.decode(latent_decoded).sample  # (B, 3, 256, 256)
    image_out = (image_out + 1) / 2  # [-1,1] → [0,1]
6.3 DDIM Scheduler: Fewer Steps
DDPM requires 1000 steps per image. DDIM (Denoising Diffusion Implicit Models) enables deterministic sampling with only 20–50 steps by skipping timesteps:
| Scheduler | Steps | Stochastic? | Quality | Speed |
|---|---|---|---|---|
| DDPM | 1000 | Yes (random z each step) | Good | Very slow |
| DDIM | 20–50 | No (deterministic) | Comparable | 20–50× faster |
| Euler | 20–30 | Optional | Good | Fast |
| DPM-Solver | 10–25 | Optional | Very good | Fastest |
DDPM (1000 steps) vs DDIM (50 steps)
═════════════════════════════════════

  DDPM:   x_1000 → x_999 → x_998 → ... → x_1 → x_0
          └──────────── 1000 U-Net calls ────────────┘

  DDIM:   x_1000 → x_980 → x_960 → ... → x_20 → x_0
          └──────────── 50 U-Net calls ──────────────┘
          (skip 20 steps each time)

  DDIM key insight: non-Markovian — x_{t-k} depends on x_t & x_0 (predicted)
  → No need to go through each intermediate step
  → Same quality, 20× faster
Exam tip: If the question asks "Why does Stable Diffusion use 50 steps while DDPM uses 1000?", the answer relates to the DDIM scheduler and latent space. Both factors contribute: DDIM reduces the number of steps, latent space reduces the size of each step.
7. Cheat Sheet — Part 2 Summary
| Concept | Key Formula / Detail | Exam Focus |
|---|---|---|
| CLIP Text Encoder | text → (B, 77, 768) embeddings | Shape, frozen vs trainable |
| Contrastive Loss | CE on NxN similarity matrix | Matched pairs ↑, non-matched ↓ |
| Cross-Attention Q | Q = W_q · image_features | Q from image, NOT text |
| Cross-Attention K, V | K = W_k · text_emb, V = W_v · text_emb | K, V from text, NOT image |
| Block order in U-Net | ResBlock → Self-Attn → Cross-Attn → FFN | Coding order matters |
| CFG formula | ε̂ = ε̂_uncond + w·(ε̂_cond − ε̂_uncond) | w = 7.5 default, 2 forward passes |
| Latent space (SD) | 256×256×3 → 32×32×4 via VAE | 48× compression, 4-channel latent |
| DDIM vs DDPM | 50 vs 1000 steps | Non-Markovian, deterministic |
| VAE scaling factor | 0.18215 | Multiply after encode, divide before decode |
| Pipeline order | Text → CLIP → U-Net(+CFG) → VAE Decode → Image | End-to-end flow |
8. Assessment Prep — DLI S-FX-14 Final Assessment
8.1 Assessment Overview
DLI assessment S-FX-14 requires you to complete coding tasks in a JupyterLab environment. You'll receive a code skeleton with # TODO markers and must implement the missing parts.
| Section | Content | Estimated Weight | Suggested Time |
|---|---|---|---|
| U-Net architecture | Implement ResBlock, Attention, CrossAttention | ~30% | 25 minutes |
| DDPM Training | Forward diffusion, training loop, loss | ~25% | 20 minutes |
| Text conditioning | CLIP integration, cross-attention wiring | ~25% | 20 minutes |
| Sampling pipeline | Reverse diffusion + CFG sampling | ~20% | 15 minutes |
8.2 Common Pitfalls & Fixes
| Pitfall | Symptom | Fix |
|---|---|---|
| Cross-attn K/V from image | Text prompt has no effect on output | Ensure K, V receive context (text), Q receives x (image) |
| Forgot L2 normalize CLIP | Similarity values out of expected range | Add / embed.norm(dim=-1, keepdim=True) |
| CFG guidance_scale = 1.0 | Low quality images, doesn't follow prompt | Use w = 7.5 or as specified in the problem |
| Wrong shape when reshaping attention | RuntimeError: shape mismatch | Check (B, H, N, d) → (B, N, H*d) ordering |
Forgot .no_grad() during sampling | Out of memory | Wrap sampling loop in torch.no_grad() |
| Wrong VAE scaling factor | Image output looks washed out or saturated | Encode: × 0.18215, Decode: ÷ 0.18215 |
| Timestep embedding wrong dim | Size mismatch in ResBlock | Verify t_emb dim matches channel dim |
8.3 Assessment Strategy
- Read the entire notebook first (5 minutes) — understand the flow, identify TODO blocks
- Implement in order: U-Net blocks → forward diffusion → training loop → sampling
- Test each part: run the cell after each TODO to confirm correct shape/output
- Debug shape errors: temporarily add
print(tensor.shape) - Don't rewrite provided code — only fill in TODOs, keep everything else unchanged
Exam tip: The assessment allows you to run code multiple times. Test incrementally: implement 1 TODO → run cell → verify → move to next TODO. Don't try to implement everything before running — it will be very difficult to debug if there are multiple errors at once.
9. Practice Questions — Coding Exercises
The questions below simulate the format of the DLI assessment. Try to solve them yourself before checking the answers.
Q1: Implement CrossAttention module
Complete the CrossAttention module. Q comes from image features, K and V come from text embeddings. Use multi-head attention with residual connection.
class CrossAttention(nn.Module):
    def __init__(self, d_model=256, context_dim=768, n_heads=8):
        super().__init__()
        self.n_heads = n_heads
        self.d_head = d_model // n_heads
        # TODO: Define to_q, to_k, to_v, out_proj, and norm
        pass

    def forward(self, x, context):
        """
        x: (B, N, d_model) - image features
        context: (B, S, context_dim) - text embeddings
        Returns: (B, N, d_model)
        """
        # TODO: Implement cross-attention
        pass
Show Answer Q1
class CrossAttention(nn.Module):
    def __init__(self, d_model=256, context_dim=768, n_heads=8):
        super().__init__()
        self.n_heads = n_heads
        self.d_head = d_model // n_heads
        self.to_q = nn.Linear(d_model, d_model, bias=False)
        self.to_k = nn.Linear(context_dim, d_model, bias=False)
        self.to_v = nn.Linear(context_dim, d_model, bias=False)
        self.out_proj = nn.Linear(d_model, d_model)
        self.norm = nn.LayerNorm(d_model)

    def forward(self, x, context):
        residual = x
        x = self.norm(x)
        B, N, _ = x.shape
        H, d = self.n_heads, self.d_head

        Q = self.to_q(x).view(B, N, H, d).transpose(1, 2)         # (B, H, N, d)
        K = self.to_k(context).view(B, -1, H, d).transpose(1, 2)   # (B, H, S, d)
        V = self.to_v(context).view(B, -1, H, d).transpose(1, 2)   # (B, H, S, d)

        scale = d ** -0.5
        attn = torch.matmul(Q, K.transpose(-2, -1)) * scale
        attn = F.softmax(attn, dim=-1)

        out = torch.matmul(attn, V)
        out = out.transpose(1, 2).contiguous().view(B, N, H * d)
        out = self.out_proj(out)
        return out + residual
Key point: to_q receives x (image), to_k and to_v receive context (text). This is the only difference compared to self-attention.
Q2: Build full text-to-image sampling pipeline
Given a trained U-Net with cross-attention, CLIP text encoder, and DDPM schedule, implement the complete sampling function with Classifier-Free Guidance.
@torch.no_grad()
def sample_text_to_image(unet, clip_encoder, prompt, schedule,
                          guidance_scale=7.5, H=64, W=64, C=3,
                          device='cuda'):
    """
    Generate image from text prompt.
    Args:
        unet: U-Net with cross-attention (takes x_t, t, context)
        clip_encoder: encodes text → (1, 77, 768)
        prompt: string, e.g. "a cat sitting on a chair"
        schedule: dict with 'betas', 'alphas', 'alpha_bar'
        guidance_scale: CFG weight (w)
    Returns: generated image tensor (1, C, H, W)
    """
    # TODO: Implement full pipeline
    # 1. Encode prompt and null prompt with CLIP
    # 2. Initialize x_T as random noise
    # 3. Reverse diffusion loop with CFG
    # 4. Return x_0
    pass
Show Answer Q2
@torch.no_grad()
def sample_text_to_image(unet, clip_encoder, prompt, schedule,
                          guidance_scale=7.5, H=64, W=64, C=3,
                          device='cuda'):
    T = len(schedule['betas'])
    betas = schedule['betas'].to(device)
    alphas = schedule['alphas'].to(device)
    alpha_bar = schedule['alpha_bar'].to(device)

    # 1. Encode text
    text_emb = clip_encoder.encode(prompt)       # (1, 77, 768)
    null_emb = clip_encoder.encode("")            # (1, 77, 768)

    # 2. Initialize noise
    x_t = torch.randn(1, C, H, W, device=device)

    # 3. Reverse diffusion
    for t in reversed(range(T)):
        t_tensor = torch.tensor([t], device=device)

        # CFG: two forward passes
        eps_cond = unet(x_t, t_tensor, context=text_emb)
        eps_uncond = unet(x_t, t_tensor, context=null_emb)
        eps = eps_uncond + guidance_scale * (eps_cond - eps_uncond)

        # DDPM reverse step
        ab_t = alpha_bar[t]
        a_t = alphas[t]
        b_t = betas[t]

        x0_pred = (x_t - (1 - ab_t).sqrt() * eps) / ab_t.sqrt()
        x0_pred = x0_pred.clamp(-1, 1)

        if t > 0:
            ab_prev = alpha_bar[t - 1]
            c1 = b_t * ab_prev.sqrt() / (1 - ab_t)
            c2 = (1 - ab_prev) * a_t.sqrt() / (1 - ab_t)
            mean = c1 * x0_pred + c2 * x_t
            sigma = (b_t * (1 - ab_prev) / (1 - ab_t)).sqrt()
            x_t = mean + sigma * torch.randn_like(x_t)
        else:
            x_t = x0_pred

    return x_t
Key points: (1) Null embedding for CFG unconditional path, (2) two forward passes through U-Net per step, (3) clamp x0_pred to avoid numerical instability, (4) no noise at t=0.
Q3: Explain why Latent Diffusion uses ~50 steps while DDPM needs 1000
Write a short function that demonstrates the difference between DDPM and DDIM step selection, and explain in comments why DDIM can skip steps.
def compare_schedulers(T=1000, ddim_steps=50):
    """
    Show the difference between DDPM and DDIM timestep selection.
    TODO: Return both timestep sequences and add comments explaining
    why DDIM can skip steps without quality loss.
    """
    # TODO: implement
    pass
Show Answer Q3
import numpy as np

def compare_schedulers(T=1000, ddim_steps=50):
    """
    DDPM: must visit every timestep t = T-1, T-2, ..., 1, 0
      → each step is Markovian: x_{t-1} depends ONLY on x_t
      → cannot skip steps without breaking the Markov chain

    DDIM: can skip timesteps using a non-Markovian formulation
      → x_{t-k} = f(x_t, predicted_x_0) — depends on x_t AND predicted x_0
      → the "shortcut" through predicted x_0 allows jumping multiple steps
      → deterministic (no random noise z added at each step)
    """
    # DDPM: all 1000 steps
    ddpm_steps = list(range(T - 1, -1, -1))  # [999, 998, ..., 1, 0]

    # DDIM: evenly spaced subset
    step_size = T // ddim_steps  # 1000 // 50 = 20
    ddim_timesteps = list(range(T - 1, -1, -step_size))  # [999, 979, 959, ..., 19]

    print(f"DDPM: {len(ddpm_steps)} steps")
    print(f"  First 5: {ddpm_steps[:5]}")
    print(f"  Last  5: {ddpm_steps[-5:]}")

    print(f"\nDDIM: {len(ddim_timesteps)} steps")
    print(f"  First 5: {ddim_timesteps[:5]}")
    print(f"  Last  5: {ddim_timesteps[-5:]}")

    # Key reason: DDIM uses non-Markovian update rule:
    # x_{t-k} = sqrt(ᾱ_{t-k}) * predicted_x0 + sqrt(1 - ᾱ_{t-k}) * direction
    # This formula works for ANY t-k, not just t-1
    # → can skip from t=999 to t=979 directly

    return ddpm_steps, ddim_timesteps
Core insight: DDPM is Markovian (each step depends only on the previous step), while DDIM is non-Markovian (depends on predicted x_0 as well). The non-Markovian formulation allows "jumping" through multiple steps at once without significant quality loss.
Q4: Debug — Text prompt has no effect on generated image
The following code generates images, but changing the text prompt does NOT change the output. Find and fix the bug.
class BuggyUNetBlock(nn.Module):
    def __init__(self, d_model=256, context_dim=768, n_heads=8):
        super().__init__()
        self.self_attn = nn.MultiheadAttention(d_model, n_heads, batch_first=True)
        self.cross_attn_q = nn.Linear(d_model, d_model)
        self.cross_attn_k = nn.Linear(d_model, d_model)      # BUG HERE?
        self.cross_attn_v = nn.Linear(d_model, d_model)      # BUG HERE?
        self.cross_attn_out = nn.Linear(d_model, d_model)
        self.norm1 = nn.LayerNorm(d_model)
        self.norm2 = nn.LayerNorm(d_model)

    def forward(self, x, context):
        # Self-attention
        norm_x = self.norm1(x)
        sa_out, _ = self.self_attn(norm_x, norm_x, norm_x)
        x = x + sa_out

        # Cross-attention
        norm_x = self.norm2(x)
        Q = self.cross_attn_q(norm_x)
        K = self.cross_attn_k(norm_x)    # ← THIS LINE
        V = self.cross_attn_v(norm_x)    # ← AND THIS LINE
        # ... attention computation ...
        return x
Show Answer Q4
# BUG: cross_attn_k and cross_attn_v take norm_x (image features)
# instead of context (text embeddings).
# This makes "cross-attention" effectively another self-attention,
# so text prompt has ZERO effect on the output.

# FIX 1: Change Linear input dimensions
self.cross_attn_k = nn.Linear(context_dim, d_model)  # context_dim, not d_model
self.cross_attn_v = nn.Linear(context_dim, d_model)   # context_dim, not d_model

# FIX 2: Pass context instead of norm_x
K = self.cross_attn_k(context)    # ← FIX: use context, not norm_x
V = self.cross_attn_v(context)    # ← FIX: use context, not norm_x
Two bugs: (1) cross_attn_k and cross_attn_v have input dim = d_model instead of context_dim, (2) K and V are computed from norm_x (image) instead of context (text). Result: the U-Net completely ignores text conditioning → output is the same as unconditional generation regardless of the prompt.
Q5: Integration test — Assemble working text-to-image system
Given the following pre-built components, write the integration code that connects them into a working text-to-image system and generates one image.
# Pre-built components (already defined):
# - clip_model: has .encode_text(tokens) → (B, 77, 768)
# - unet: has .forward(x_t, t_emb, context) → noise prediction
# - schedule: dict with 'betas', 'alphas', 'alpha_bar' (T=1000)
# - ddpm_reverse_step(x_t, noise_pred, t, schedule) → x_{t-1}

def generate_image(prompt: str, negative_prompt: str = "",
                   guidance_scale: float = 7.5, steps: int = 1000,
                   image_size: int = 64, channels: int = 3):
    """
    TODO: Wire all components together.
    Handle: CLIP encoding, null prompt for CFG, reverse loop, CFG combination.
    Return final image tensor.
    """
    pass
Show Answer Q5
@torch.no_grad()
def generate_image(prompt: str, negative_prompt: str = "",
                   guidance_scale: float = 7.5, steps: int = 1000,
                   image_size: int = 64, channels: int = 3):
    device = next(unet.parameters()).device

    # ── 1. CLIP encode: positive and negative/null prompts ──
    pos_tokens = clip.tokenize([prompt]).to(device)
    neg_tokens = clip.tokenize([negative_prompt]).to(device)

    pos_emb = clip_model.encode_text(pos_tokens)     # (1, 77, 768)
    neg_emb = clip_model.encode_text(neg_tokens)     # (1, 77, 768)

    # ── 2. Initialize random noise ──
    x_t = torch.randn(1, channels, image_size, image_size, device=device)

    # ── 3. Reverse diffusion with CFG ──
    for t in reversed(range(steps)):
        t_tensor = torch.tensor([t], device=device)

        # Two forward passes for CFG
        noise_pos = unet(x_t, t_tensor, context=pos_emb)
        noise_neg = unet(x_t, t_tensor, context=neg_emb)

        # CFG combination
        noise_guided = noise_neg + guidance_scale * (noise_pos - noise_neg)

        # Denoise step
        x_t = ddpm_reverse_step(x_t, noise_guided, t, schedule)

    # ── 4. Post-process ──
    image = (x_t.clamp(-1, 1) + 1) / 2   # [-1,1] → [0,1]
    return image

# Generate!
img = generate_image("a golden retriever playing in snow", guidance_scale=7.5)
print(f"Output shape: {img.shape}")  # (1, 3, 64, 64)
Integration checklist: (1) Encode both positive and negative prompts, (2) initialize noise with correct shape, (3) loop in reverse from T-1 to 0, (4) two forward passes per step for CFG, (5) combine with guidance_scale, (6) call denoise step, (7) post-process output. An empty negative prompt "" acts as unconditional — this is how Stable Diffusion handles CFG.