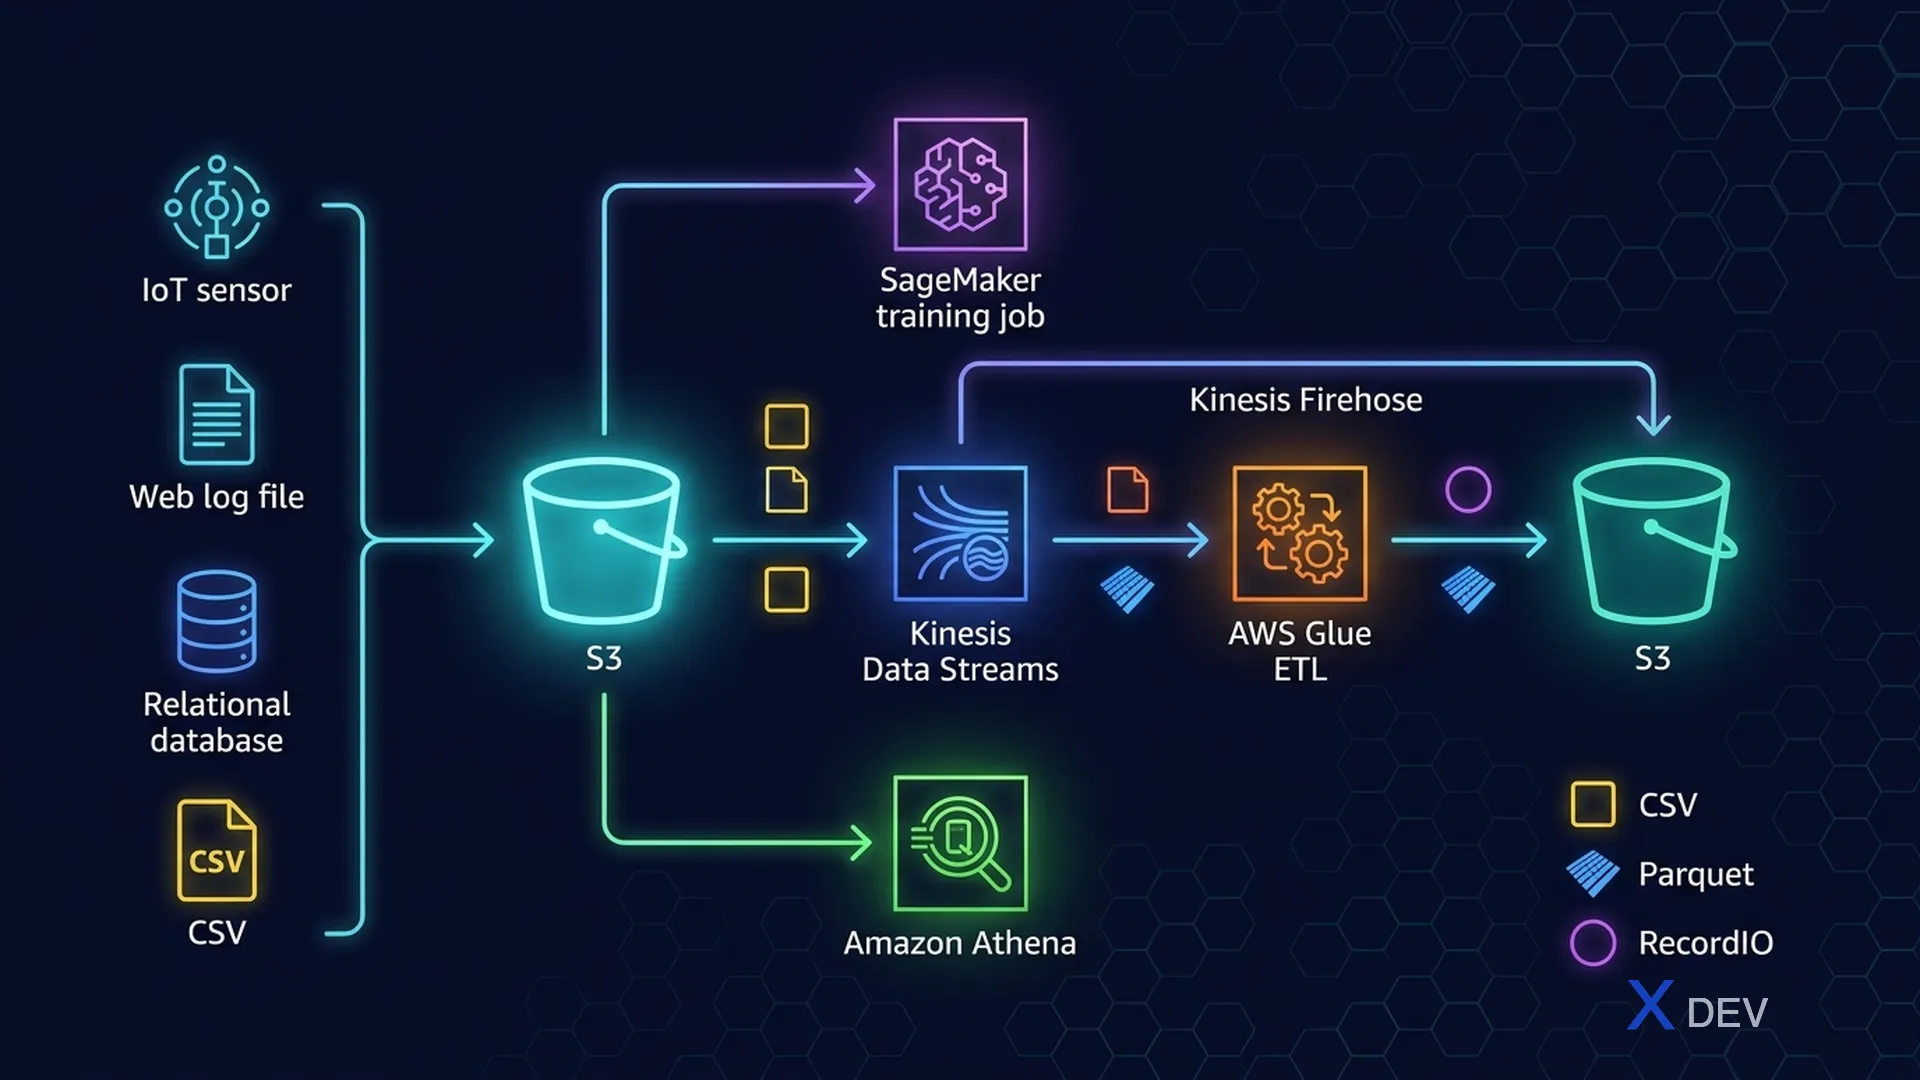
Data Repositories & Ingestion: S3, Kinesis, Glue và Lake Formation trong ML pipeline
1. Tổng quan Data Engineering trong MLS-C01
Domain Data Engineering chiếm 20% đề thi MLS-C01. Đây là phần bắt buộc phải nắm vững — đề thi thường hỏi "Which service should be used to ingest/store/transform data for ML?"
Exam tip: Phần lớn câu hỏi Data Engineering sẽ cho một scenario và hỏi service phù hợp. Key pattern: batch → S3 + Glue; streaming → Kinesis; structured/SQL → Athena; catalog → Glue Data Catalog.
2. Amazon S3 — ML Data Lake
Amazon S3 là nền tảng lưu trữ dữ liệu ML trên AWS. Mọi pipeline ML đều bắt đầu và kết thúc từ S3: training data, model artifacts, predictions.
2.1. S3 Storage Classes cho ML
| Storage Class | Use Case | Cost |
|---|---|---|
| S3 Standard | Active training data, frequent access | Cao nhất |
| S3 Intelligent-Tiering | Mixed access patterns (tự động tier) | Tự động tối ưu |
| S3 Standard-IA | Backup datasets, infrequent access | Thấp hơn Standard |
| S3 Glacier Instant Retrieval | Archived datasets, occasional retrieval | Thấp |
| S3 Glacier Deep Archive | Long-term compliance archives | Thấp nhất |
2.2. File Formats for ML
| Format | Type | Best For | Compression |
|---|---|---|---|
| Parquet | Columnar | Analytics, large datasets, feature stores | Excellent |
| ORC | Columnar | Hive/EMR workloads | Excellent |
| CSV | Row-based | Simple, SageMaker training input | Poor |
| JSON | Semi-structured | Nested data, APIs | Poor |
| RecordIO | Binary | SageMaker Pipe Mode training | Good |
Exam tip: Khi đề hỏi về performance optimization cho large-scale training, đáp án thường là chuyển sang Parquet (columnar, compressed) và dùng Pipe Mode thay vì File Mode trong SageMaker.
S3 Data Lake Architecture for ML:

┌─────────────────────────────────────────────────────────┐
│                    Amazon S3 Buckets                     │
├──────────────┬──────────────┬──────────────┬────────────┤
│  Raw Zone    │ Processed    │  Features    │  Models    │
│  (landing)   │  Zone        │  Zone        │  & Output  │
│              │              │              │            │
│  CSV/JSON    │  Parquet/ORC │  Feature     │  Model     │
│  original    │  cleaned     │  Store       │  Artifacts │
│  data        │  transformed │  snapshots   │  Predictions│
└──────────────┴──────────────┴──────────────┴────────────┘
       ↑                ↑                ↑
   Kinesis          AWS Glue         SageMaker
  (streaming)        (ETL)           Processing
3. Amazon Kinesis — Streaming Ingestion
Kinesis là họ dịch vụ cho real-time data streaming. Đây là topic quan trọng trong đề thi — cần phân biệt rõ 4 services.
| Service | Function | Destination | ML Use Case |
|---|---|---|---|
| Kinesis Data Streams (KDS) | Custom real-time processing | Custom consumers | Real-time feature engineering |
| Kinesis Data Firehose | Managed delivery (no code) | S3, Redshift, ES, Splunk | Batch loading to data lake |
| Kinesis Data Analytics | SQL/Flink on streams | S3, Redshift | Real-time aggregations, anomaly detect |
| Kinesis Video Streams | Video ingestion | Rekognition, SageMaker | Computer vision pipelines |
Exam tip: Câu hỏi phổ biến: "IoT sensors gửi data liên tục, cần store vào S3 cho ML training mà không cần custom code?" → Kinesis Data Firehose (managed, no code). "Cần xử lý real-time với custom logic?" → Kinesis Data Streams.
3.1. KDS Shards & Capacity
Kinesis Data Streams Capacity:

┌─────────────────────────────────────────────┐
│  Each Shard:                                │
│  • Ingest:  1 MB/s OR 1,000 records/s       │
│  • Read:    2 MB/s                          │
│  • Retention: 24 hours (default) → 7 days  │
└─────────────────────────────────────────────┘

Stream with N shards:
• Total ingest: N × 1 MB/s
• Total read:   N × 2 MB/s
4. AWS Glue — ETL for ML
AWS Glue là fully managed ETL service. Trong ML pipeline, Glue dùng để transform và clean data trước khi đưa vào training.
4.1. Glue Components
| Component | Function |
|---|---|
| Glue Data Catalog | Central metadata repository — schemas, tables, partitions |
| Glue Crawlers | Auto-discover schema từ S3/RDS/Redshift và populate Data Catalog |
| Glue ETL Jobs | Spark-based transformation jobs (Python/Scala) |
| Glue DataBrew | No-code visual data preparation (250+ pre-built transforms) |
| Glue Studio | Visual ETL job builder (drag-and-drop) |
Exam tip: Glue Data Catalog là metadata store chung cho Athena, EMR, Redshift Spectrum. Khi đề hỏi "centralized schema management" → Glue Data Catalog. Khi hỏi "no-code data cleaning" → Glue DataBrew.
5. AWS Lake Formation
Lake Formation build trên S3 + Glue để management data lake security và governance. Key feature: column-level và row-level access control.
Lake Formation Architecture:

  IAM Users ──→ Lake Formation ──→ S3 Data Lake
  IAM Roles       (Security         (Raw/Processed)
                   & Governance)
                       ↓
                  Column/Row
                  Level Access
                  Control
6. Cheat Sheet — Data Ingestion Services
| Scenario | Service |
|---|---|
| Streaming → S3 với no-code | Kinesis Data Firehose |
| Real-time processing với custom logic | Kinesis Data Streams |
| SQL on streaming data | Kinesis Data Analytics (Flink) |
| Batch ETL Spark-based | AWS Glue ETL Jobs |
| No-code visual data prep | Glue DataBrew |
| Schema discovery from S3 | Glue Crawlers + Data Catalog |
| SQL queries on S3 | Amazon Athena |
| Data lake governance | AWS Lake Formation |
| Large-scale Spark/Hadoop | Amazon EMR |
7. Practice Questions
Q1: A company wants to ingest IoT sensor data into Amazon S3 for ML training. The data arrives continuously and no custom processing is required. Which service is the MOST cost-effective?
- A) Amazon Kinesis Data Streams with a Lambda consumer
- B) Amazon Kinesis Data Firehose ✓
- C) Amazon EMR with Spark Streaming
- D) AWS Glue ETL jobs on a schedule
Explanation: Kinesis Data Firehose is fully managed and requires no custom code — it directly delivers streaming data to S3, Redshift, or Elasticsearch. Data Streams requires custom consumers, EMR is heavy lift, and Glue is for batch ETL.
Q2: A data engineer wants to query raw CSV files in S3 using SQL without loading them into a database. Which service should be used?
- A) Amazon RDS
- B) Amazon DynamoDB
- C) Amazon Athena ✓
- D) Amazon Redshift
Explanation: Amazon Athena is serverless and allows SQL queries directly on S3 data without loading. It reads files in-place and supports formats like CSV, Parquet, ORC, JSON.
Q3: Which file format provides the BEST performance for columnar analytics queries on large ML datasets stored in Amazon S3?
- A) CSV
- B) JSON
- C) XML
- D) Apache Parquet ✓
Explanation: Parquet is a columnar format with excellent compression and predicate pushdown support. Columnar formats allow reading only the required columns, dramatically reducing I/O for analytical queries.