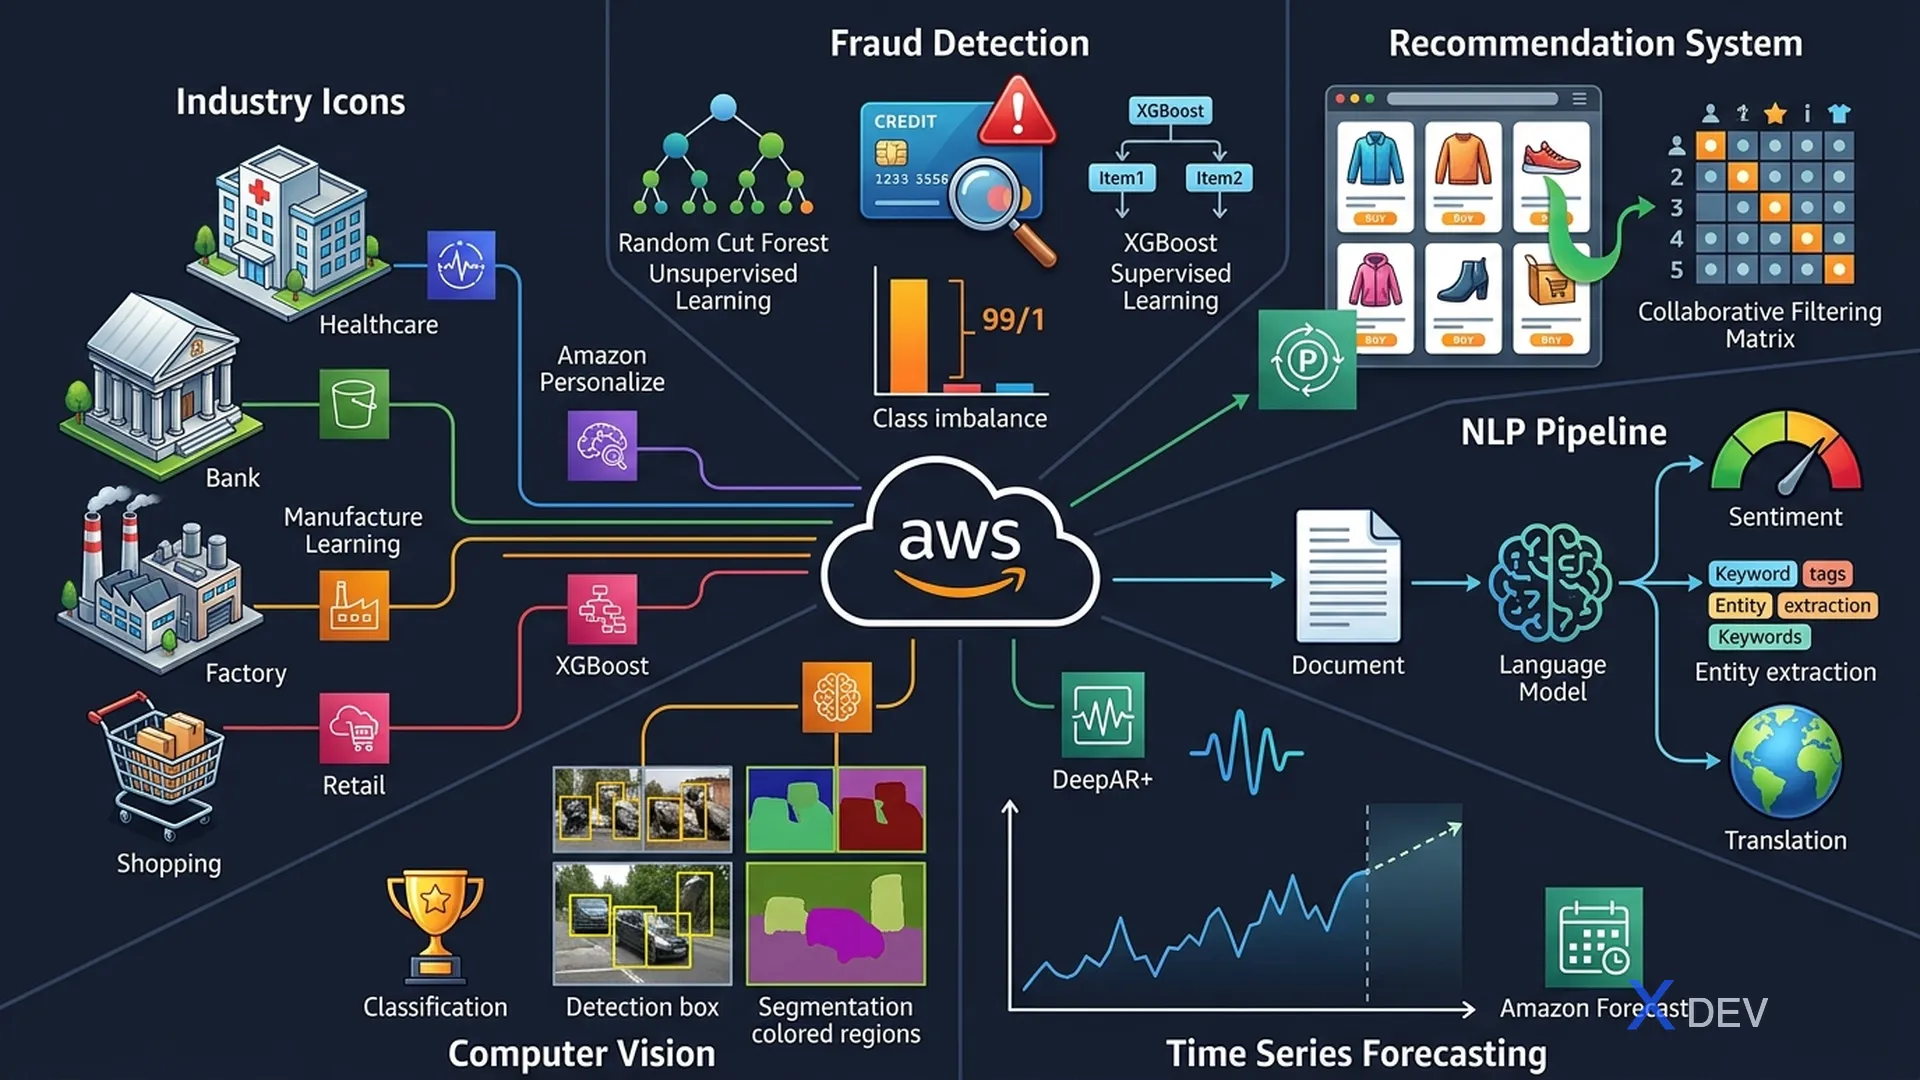
ML Problem Patterns: Fraud detection, Recommendation, NLP, Time Series, và Computer Vision trên AWS
1. Nhận Dạng Bài Toán Nhanh
Phần lớn câu hỏi MLS-C01 là scenario-based: đọc mô tả business problem, chọn AWS service hoặc algorithm phù hợp nhất. Bài học này cung cấp framework để nhận dạng nhanh.
ML Problem Recognition Framework:

READ SCENARIO
    ↓
Is output a CATEGORY?          → Classification
Is output a NUMBER?            → Regression
Is output a CLUSTER/GROUP?     → Clustering (no labels)
Is output a RANK/SCORE?        → Recommendation / Ranking
Is output a DETECTION (anomaly)? → Anomaly Detection
Is output a SEQUENCE?          → Time Series / Seq2Seq
2. Fraud Detection
Fraud detection là bài toán điển hình trong đề thi. Key challenge: extreme class imbalance (99.9% transactions là legitimate).
| Challenge | Solution |
|---|---|
| Class imbalance | SMOTE, class_weight, precision-recall (not accuracy) |
| Real-time scoring | SageMaker Real-time Endpoint |
| Unsupervised fraud (no labels) | Random Cut Forest (anomaly detection) |
| Graph-based fraud rings | Amazon Neptune + GNN (GraphSAGE) |
| Supervised (labeled history) | XGBoost or Linear Learner |
Exam tip: Khi câu hỏi nói "không có nhãn fraud" hoặc "phát hiện hành vi bất thường" → Random Cut Forest. Khi có lịch sử giao dịch gian lận đã được gán nhãn → Classification (XGBoost).
3. Recommendation Systems
| Type | Algorithm | AWS Service |
|---|---|---|
| Collaborative Filtering | Factorization Machines, Neural CF | SageMaker FM, Amazon Personalize |
| Content-Based | TF-IDF, Embeddings | SageMaker Knn |
| Hybrid | FM + content features | Amazon Personalize (HRNN) |
| Cold Start Problem | Content features, metadata | Personalize context metadata |
Đề thi thường hỏi: "Real-time personalized recommendations for e-commerce" → câu trả lời gần như luôn là Amazon Personalize (managed service).
4. NLP Pipeline
NLP Task Decision Tree:

Classify documents?
    → Text Classification → BlazingText (word2vec mode), Comprehend Custom

Extract entities from text?
    → Named Entity Recognition → Amazon Comprehend (NER)

Translate text?
    → Amazon Translate

Summarize documents?
    → Hugging Face on SageMaker (T5, BART)

Q&A / Generation?
    → SageMaker JumpStart foundation models (Llama, Falcon)

Toxic content detection?
    → Amazon Comprehend (Sentiment + custom classifier)
| NLP Task | Algorithm/Service |
|---|---|
| Document classification | BlazingText, Comprehend Custom |
| Topic modeling | Latent Dirichlet Allocation (LDA), NTM |
| Sentiment analysis | Amazon Comprehend |
| Language detection | Amazon Comprehend |
| Machine translation | Amazon Translate |
| Conversational AI | Amazon Lex (chatbot) + Lambda |
5. Time Series Forecasting
| Service/Algorithm | Use Case |
|---|---|
| DeepAR+ (SageMaker built-in) | Multiple related time series, cold start |
| Amazon Forecast | Fully managed, business forecasting (demand, inventory) |
| ARIMA | Single stationary series, classic approach |
| Prophet | Seasonality + holidays, Facebook's library |
Exam tip: "Predict retail demand for thousands of products" → DeepAR+ (multiple related series) or Amazon Forecast (managed). Key differentiator: DeepAR+ trains one model for ALL items, while classical methods need one model per series.
6. Computer Vision
| CV Task | Algorithm | Service |
|---|---|---|
| Image Classification | Image Classification (ResNet) | SageMaker built-in |
| Object Detection | Object Detection (SSD/YOLO) | SageMaker built-in |
| Semantic Segmentation | Semantic Segmentation | SageMaker built-in |
| Rekognition (no ML needed) | Faces, objects, text, moderation | Amazon Rekognition |
| Custom labels in images | Fine-tuning | Rekognition Custom Labels |
7. Business Domain → AWS Service Mapping
| Industry / Scenario | AWS Service |
|---|---|
| E-commerce personalization | Amazon Personalize |
| Call center analytics | Amazon Transcribe + Comprehend |
| Medical image analysis | Amazon HealthLake + SageMaker (custom model) |
| Document understanding (invoices, forms) | Amazon Textract |
| Product search (semantic) | Amazon OpenSearch + KNN |
| IoT anomaly detection | Amazon Lookout for Equipment |
| Manufacturing defect detection | Amazon Lookout for Vision |
| Financial forecasting (managed) | Amazon Forecast |
| Churn prediction | XGBoost (SageMaker) |
8. Practice Questions
Q1: A retail company wants to predict next quarter's sales for 10,000 individual products, incorporating holiday seasonality and promotional events. Which solution is MOST appropriate?
- A) Train separate ARIMA models for each of the 10,000 products
- B) Use Amazon Forecast with related time series data ✓
- C) Use Amazon Comprehend for trend analysis
- D) Use Amazon Rekognition to analyze product images
Explanation: Amazon Forecast is designed for business demand forecasting at scale, can handle thousands of related time series simultaneously, and supports external factors like holidays and promotions. Training 10,000 separate ARIMA models would be impractical and miss cross-series patterns.
Q2: A bank needs to detect fraudulent transactions in real time WITHOUT having labeled historical fraud data. Which algorithm should they use?
- A) XGBoost classifier
- B) Linear Learner with binary classification
- C) Random Cut Forest ✓
- D) BlazingText
Explanation: Without labeled fraud data, this is an unsupervised anomaly detection problem. Random Cut Forest detects anomalies (transactions that deviate from normal patterns) without requiring labeled examples. XGBoost and Linear Learner are supervised and require labeled training data.
Q3: A company wants to extract key-value pairs from scanned insurance claim forms (PDFs). No custom ML training has been done. Which AWS service should they use?
- A) Amazon Comprehend
- B) Amazon Textract ✓
- C) SageMaker Object Detection
- D) Amazon Rekognition
Explanation: Amazon Textract is purpose-built for extracting text, forms (key-value pairs), and tables from scanned documents including PDFs. It requires no ML training. Comprehend analyzes text meaning; Rekognition analyzes images; neither handles structured form extraction like Textract.