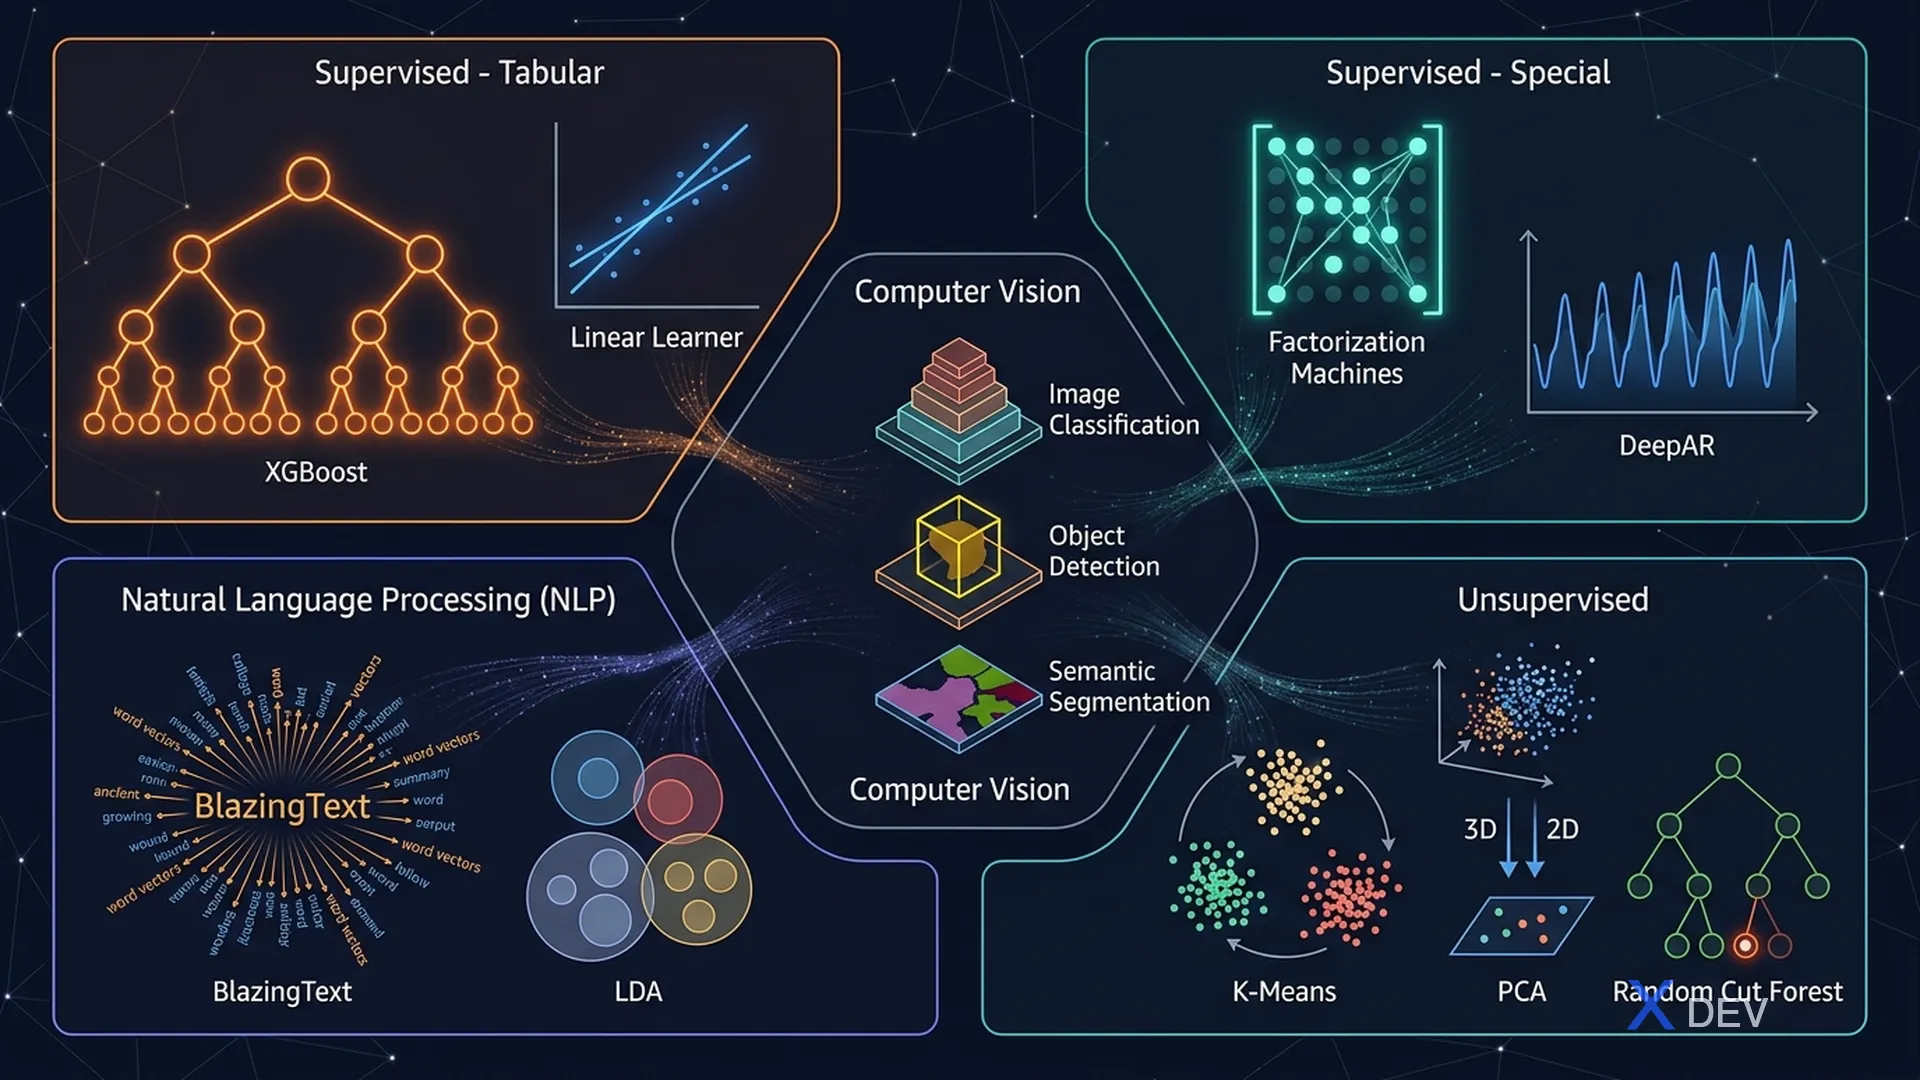
SageMaker Built-in Algorithms: từ XGBoost, Linear Learner đến DeepAR và Image Classification
1. SageMaker Built-in Algorithms Overview
SageMaker cung cấp 18+ built-in algorithms được optimize để chạy distributed trên AWS infrastructure. Đây là topic cực kỳ quan trọng trong MLS-C01 — thường chiếm 8-12 câu.
Exam tip: Học thuộc bảng "Problem Type → Algorithm". Đề thi luôn cho scenario và hỏi algorithm phù hợp. Key patterns: time series → DeepAR; anomaly → Random Cut Forest; NLP classification → BlazingText; tabular → XGBoost.
2. Supervised Learning Algorithms
| Algorithm | Problem Type | Input | Key Trait |
|---|---|---|---|
| XGBoost | Classification, Regression | Tabular (CSV/LibSVM) | Top performer cho tabular data, gradient boosting |
| Linear Learner | Binary/Multiclass classification, Regression | RecordIO, CSV | Fast, scalable, regularization built-in |
| Factorization Machines | Binary classification, Regression | RecordIO-protobuf (sparse) | Sparse data, recommendation systems, CTR prediction |
| KNN (k-Nearest Neighbors) | Classification, Regression | RecordIO-protobuf | Instance-based, no training, lazy learner |
| DeepAR | Time series forecasting | JSON Lines | Multiple related time series, probabilistic forecasts |
| Object2Vec | Embeddings | Paired sequences | Learn embeddings cho words, products, users |
3. NLP Algorithms
| Algorithm | Output | Use Case |
|---|---|---|
| BlazingText | Word vectors hoặc text classification | Sentiment analysis, spam detection, entity classification |
| Seq2Seq | Sequence → Sequence | Machine translation, summarization, Q&A |
| LDA (Latent Dirichlet Allocation) | Topics per document | Topic modeling, document categorization |
| NTM (Neural Topic Model) | Latent representations | Topic modeling với neural networks |
Exam tip: BlazingText có 2 modes: (1)
Word2Vecmode — unsupervised, generates word embeddings; (2)Text Classificationmode — supervised, like FastText. Phân biệt rõ khi đọc câu hỏi.
4. Unsupervised Learning Algorithms
| Algorithm | Problem Type | Use Case |
|---|---|---|
| K-Means | Clustering | Customer segmentation, document grouping |
| PCA (Principal Component Analysis) | Dimensionality reduction | High-dimensional data, feature compression |
| Random Cut Forest (RCF) | Anomaly detection | Fraud detection, IoT anomaly, time series anomaly |
| IP Insights | Anomaly detection | Detect unusual IP-entity relationships, security |
5. Computer Vision Algorithms
| Algorithm | Task | Output |
|---|---|---|
| Image Classification | Multi-class classification | Class label + confidence |
| Object Detection | Locate + classify objects | Bounding boxes + labels |
| Semantic Segmentation | Pixel-level classification | Segmentation mask |
6. Algorithm Selection Decision Tree
What is the problem type?
│
├── Tabular data, classification/regression?
│   └── XGBoost (best general choice)
│
├── Sparse features, recommendation, ad CTR?
│   └── Factorization Machines
│
├── Time series forecasting (multiple related series)?
│   └── DeepAR
│
├── Anomaly detection on time series / IoT?
│   └── Random Cut Forest (RCF)
│
├── Text classification / sentiment?
│   └── BlazingText (supervised mode)
│
├── Sequence-to-sequence (translation / summarization)?
│   └── Seq2Seq
│
├── Topic modeling?
│   └── LDA or NTM
│
├── Clustering?
│   └── K-Means
│
├── Dimensionality reduction?
│   └── PCA
│
└── Image tasks?
    ├── Classification only → Image Classification
    ├── Locate objects → Object Detection
    └── Pixel mask → Semantic Segmentation
7. Training Input Modes
| Mode | How It Works | Best For |
|---|---|---|
| File Mode | Downloads entire dataset to training instance before starting | Small to medium datasets |
| Pipe Mode | Streams data directly from S3 during training | Very large datasets — no disk bottleneck |
| FastFile Mode | Access S3 as if local file system (via FUSE) | Random access patterns |
Exam tip: Khi đề hỏi "reduce training time for large dataset", đáp án thường là chuyển sang Pipe Mode với RecordIO format. Pipe Mode không download toàn bộ dataset — stream trực tiếp từ S3.
8. Cheat Sheet — Quick Reference
| Keyword in Question | Algorithm |
|---|---|
| "tabular data", "structured data" | XGBoost |
| "time series", "forecast" | DeepAR |
| "anomaly detection" | Random Cut Forest |
| "recommendation", "sparse features" | Factorization Machines |
| "text classification", "sentiment" | BlazingText (supervised) |
| "word embeddings" | BlazingText (Word2Vec mode) |
| "translation", "summarization" | Seq2Seq |
| "topic modeling" | LDA or NTM |
| "clustering", "segmentation" | K-Means |
| "dimensionality reduction" | PCA |
| "bounding boxes", "object detection" | Object Detection |
| "pixel-level", "segmentation mask" | Semantic Segmentation |
| "IP address anomaly", "fraud login" | IP Insights |
9. Practice Questions
Q1: A retail company wants to forecast product demand for the next 30 days across 5,000 product categories. Which SageMaker algorithm is BEST suited?
- A) K-Means
- B) Linear Learner
- C) DeepAR ✓
- D) Seq2Seq
Explanation: DeepAR is specifically designed for time series forecasting across multiple related time series. It learns global patterns from all 5,000 series simultaneously, providing probabilistic forecasts. This is exactly the use case it's optimized for.
Q2: An IoT system monitors server CPU usage. The team wants to detect unusual spikes automatically. Which SageMaker built-in algorithm should be used?
- A) XGBoost
- B) Random Cut Forest ✓
- C) BlazingText
- D) PCA
Explanation: Random Cut Forest (RCF) is SageMaker's built-in anomaly detection algorithm. It assigns an anomaly score to each data point and works well for time series anomaly detection, such as CPU usage spikes.
Q3: A data scientist is training a model on a 500 GB dataset. Training is very slow because downloading data to the training instance takes too long. Which change will MOST improve performance?
- A) Switch from CSV to JSON format
- B) Increase the training instance size
- C) Switch to Pipe Mode with RecordIO-protobuf format ✓
- D) Add more training epochs
Explanation: Pipe Mode streams data directly from S3 during training without downloading it first, eliminating the I/O bottleneck for large datasets. Combined with RecordIO-protobuf format, it dramatically reduces startup time.