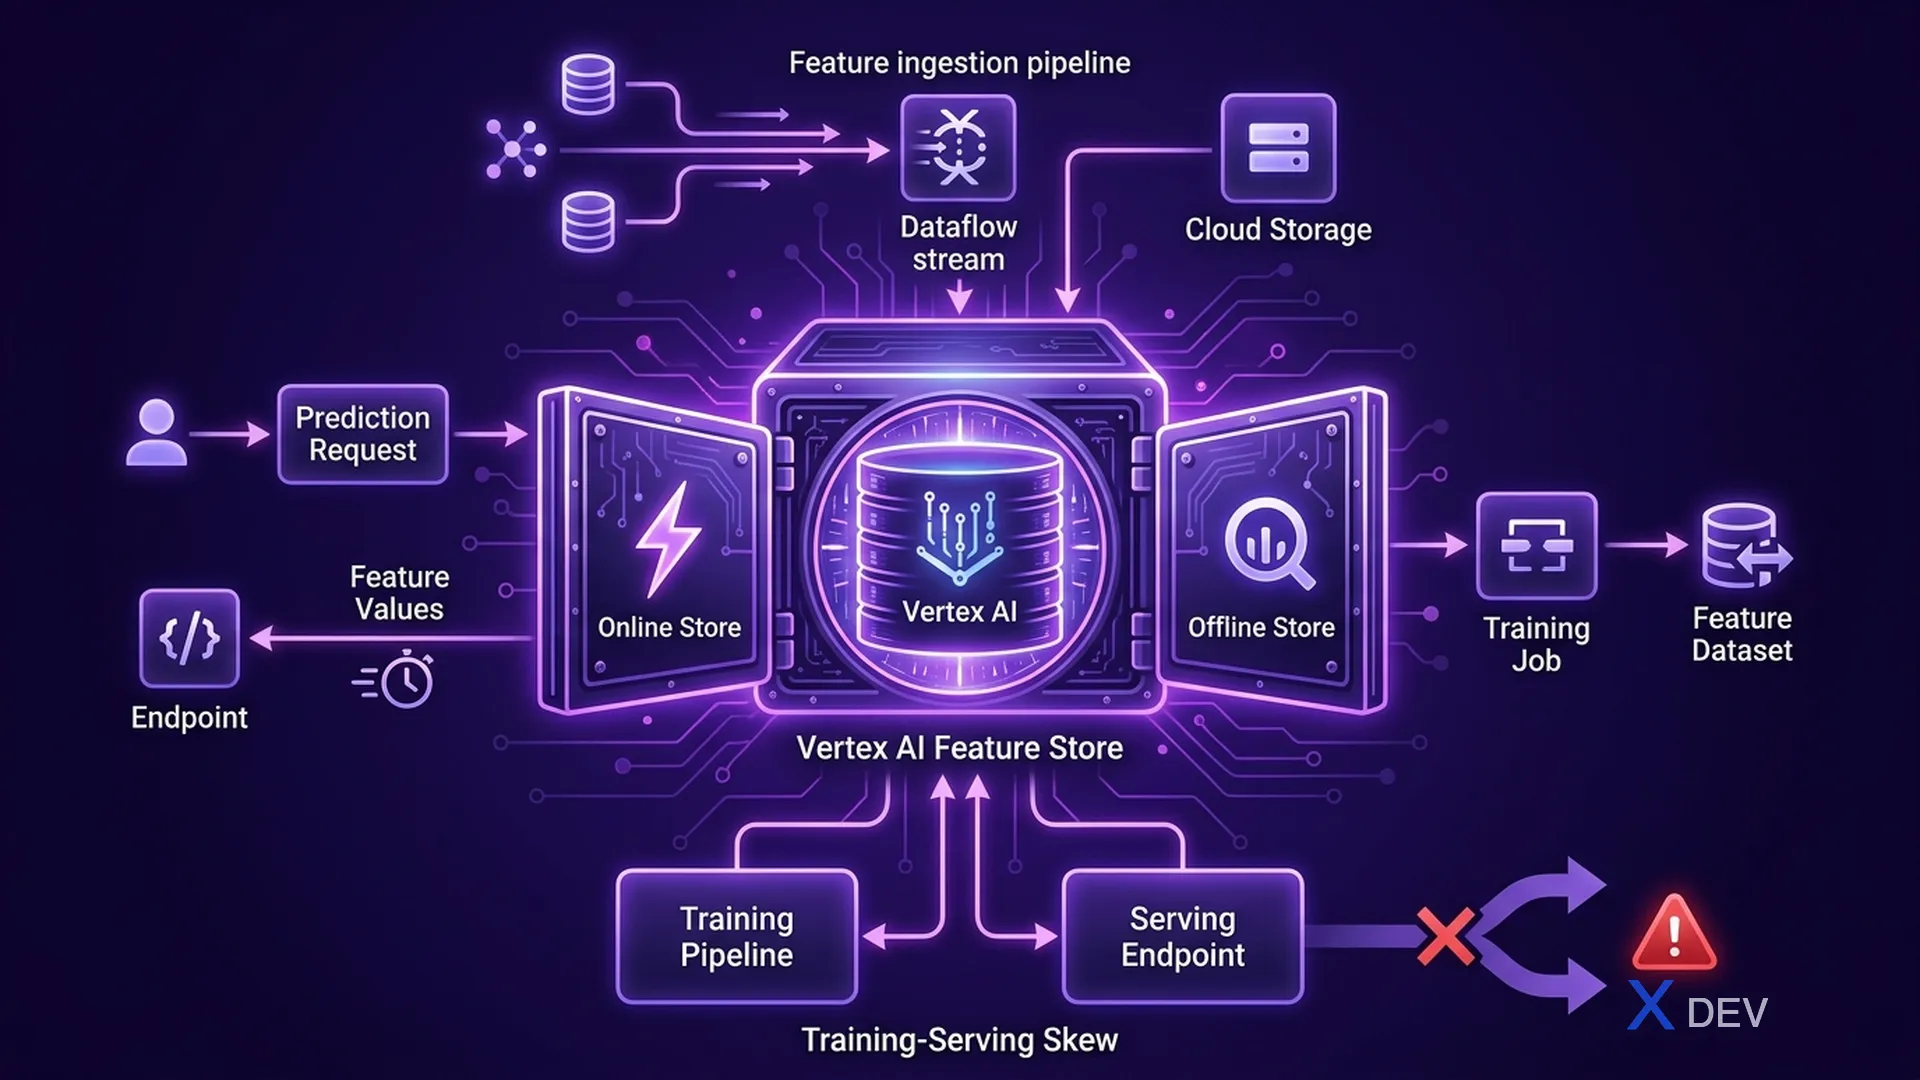
Feature Engineering & Vertex AI Feature Store: tạo, lưu trữ, và tái sử dụng features cho ML
1. Feature Engineering Techniques
| Technique | When to Use | Example |
|---|---|---|
| Normalization (Min-Max) | Bounded range required (0-1) | Image pixels, probabilities |
| Standardization (Z-score) | Normal-ish distribution, no bounds | Customer age, transaction amount |
| Log Transform | Skewed distributions (price, salary) | Log(price) for housing |
| One-Hot Encoding | Nominal categorical (no order) | Country, brand, color |
| Label Encoding | Ordinal categorical (has order) | Low/Medium/High → 0/1/2 |
| Feature Crossing | Capture interaction between features | city × day_of_week |
| Bucketizing | Convert continuous to categorical | Age → age_group |
| Embeddings | High-cardinality categorical | UserID, ProductID |
2. Handling Missing Values
| Strategy | When |
|---|---|
| Mean/Median imputation | Numerical, low missingness rate |
| Mode imputation | Categorical features |
| Model-based imputation | High missingness, complex patterns |
| Indicator variable | Missingness itself is informative (add is_missing flag) |
| Drop rows | Missing target / very few rows affected |
| Drop column | >80% missing |
3. Training-Serving Skew
Training-serving skew là vấn đề nghiêm trọng: features được compute khác nhau giữa training và serving, khiến model hoạt động kém trong production dù test metrics tốt.
Training-Serving Skew Example:

TRAINING TIME:
  avg_purchase_last_30d = mean(all purchases in batch)  ← computed over full period

SERVING TIME:
  avg_purchase_last_30d = mean(last 5 purchases)        ← computed differently!

Result: Feature distribution mismatch → poor predictions

SOLUTION: Vertex AI Feature Store
  Same feature serve logic used at training AND serving time
4. Vertex AI Feature Store
| Component | Description |
|---|---|
| Feature Store | Centralized repository for ML features |
| Entity Type | Category of things you track (User, Product) |
| Feature | Named attribute of an entity (user.avg_spend) |
| Online Store | Low-latency serving (ms) for real-time predictions |
| Offline Store | BigQuery-backed, for batch training data retrieval |
Vertex AI Feature Store Architecture:

Feature Ingestion (Batch or Streaming)
        ↓
┌──── Feature Store ────────────────┐
│  Offline Store (BigQuery)          │  ← Training data export
│  Online Store (Bigtable-backed)    │  ← Serving (ms latency)
└───────────────────────────────────┘
        ↑ Same features ↑
  Training      Inference
  Pipeline      Endpoint
5. BigQuery for Feature Engineering
BigQuery là công cụ tốt nhất trên GCP để compute aggregate features từ large datasets.
| Feature Pattern | BigQuery Approach |
|---|---|
| Rolling window aggregates | Window functions: AVG() OVER (PARTITION BY ... ORDER BY ... ROWS BETWEEN ...) |
| User activity counts | COUNT() GROUP BY user_id |
| Categorical encoding | CASE WHEN ... or ML.ONE_HOT_ENCODE() |
| Hash embedding (high cardinality) | FARM_FINGERPRINT() mod N |
| Feature normalization | ML.STANDARD_SCALER() in BigQuery ML |
Exam tip: Khi câu hỏi nhắc đến "training-serving consistency" hoặc "feature reuse across multiple models" → Vertex AI Feature Store. Khi nhắc đến "compute features from BigQuery data at scale" → BigQuery window functions + scheduled queries.
6. Feature Drift Monitoring
| Type | What Changes | Detection Method |
|---|---|---|
| Feature Skew | Training vs serving feature distribution differs | Compare training baseline vs serving stats |
| Feature Drift | Serving features change over time | Monitor serving feature distributions daily |
| Label Drift | Target variable distribution changes | Track prediction distribution shifts |
7. Practice Questions
Q1: A team's ML model has excellent accuracy during testing but performs poorly in production. Investigations reveal that the average purchase feature is calculated differently in training (using historical batch data) vs. serving (using real-time lookups). What is this problem called and how should it be solved?
- A) Model drift — retrain the model more frequently
- B) Training-serving skew — use Vertex AI Feature Store ✓
- C) Data leakage — remove the purchase feature
- D) Overfitting — add dropout layers
Explanation: Training-serving skew occurs when features are computed differently at training and serving time. Vertex AI Feature Store solves this by providing a single source of truth for feature computation, ensuring the same logic is used for both training data export and online serving.
Q2: A feature has values ranging from $10 to $10,000,000 with a heavily right-skewed distribution. Which transformation is MOST appropriate before using this feature in a linear model?
- A) One-Hot Encoding
- B) Min-Max Normalization
- C) Log transformation ✓
- D) Label Encoding
Explanation: Log transformation compresses the scale of highly skewed distributions, making them more normal-like and suitable for linear models. Min-Max normalization would still preserve the skew. One-hot encoding is for categorical data.
Q3: Which Vertex AI Feature Store store type is optimized for serving features to real-time prediction endpoints with millisecond latency?
- A) Offline Store (BigQuery)
- B) Online Store (Bigtable-backed) ✓
- C) Feature Catalog
- D) Cloud Memorystore
Explanation: The Online Store in Vertex AI Feature Store is backed by Bigtable and designed for sub-100ms latency lookups, serving fresh feature values to real-time prediction endpoints. The Offline Store uses BigQuery and is for batch training data retrieval.