"BA estimate bao nhiêu points cho story này?" — Câu hỏi dễ với feature CRUD thông thường. Nhưng với AI feature, answer thường là "tùy" và đó không phải câu trả lời stakeholder muốn nghe.
1. Tại sao AI Story khó estimate hơn?
AI work có 3 nguồn uncertainty mà feature thường không có:
| Nguồn Uncertainty | Ví dụ | Ảnh hưởng |
|---|---|---|
| Data readiness | Data pipeline chưa sẵn sàng | Block toàn bộ story |
| Model performance | Accuracy có đạt threshold không? | Cần thêm iteration |
| Experiment branching | Thử approach A fail, phải làm lại approach B | Sprint scope thay đổi |
2. Story Types trong AI Project
Phân biệt 3 loại story để estimate đúng:
Type 1: Standard Implementation Story
Feature đã rõ ràng, AI role đã design xong:
"As an agent, I want to see AI suggestion in review UI
 [UI đã design, API spec đã có]"
→ Estimate bình thường bằng Planning Poker
Type 2: Spike Story (Research Story)
Chưa biết approach, cần investigate trước:
"Spike: Evaluate 3 embedding models for customer query classification.
 Timebox: 2 days. Output: Recommendation doc."
→ Không estimate story points — timebox cố định
→ Output của Spike = input để estimate Implementation story
Type 3: Experiment Story
Cần run experiment, result không chắc:
"Experiment: Test GPT-4o-mini vs Claude Haiku for ticket categorization.
 Success criterion: Either model reaches 87% accuracy.
 Timebox: 3 days. If neither passes → escalate to team."
→ Timebox + success criterion, không phải story points
3. Adapted Planning Poker cho AI Stories
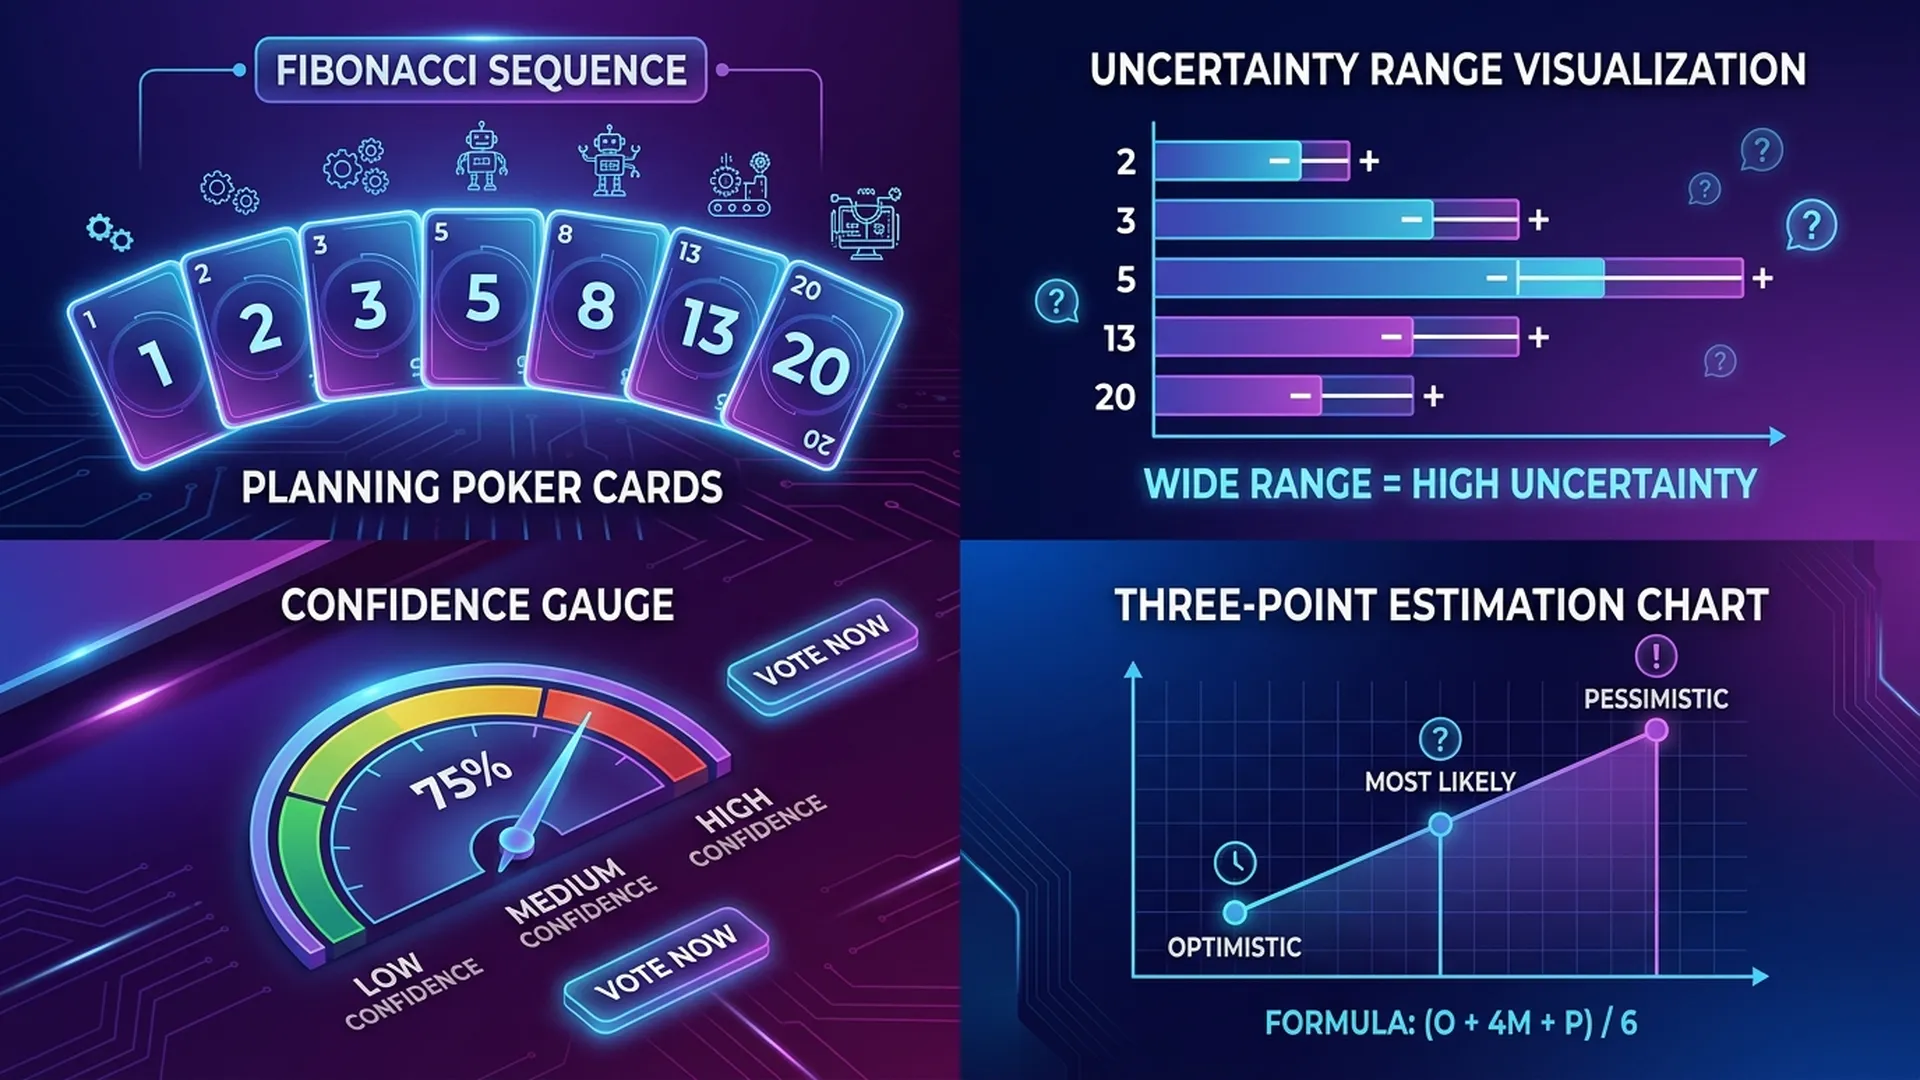
3.1 Thêm "Uncertainty Dimension" vào estimate
Traditional Planning Poker: 1 số (effort)
AI Adapted: 2 số (effort × confidence)
Estimate format: [Points] / [Confidence: H/M/L]

Ví dụ:
- Dev 1: "8 / M" — 8 points nhưng medium confidence
- Dev 2: "13 / L" — 13 points với low confidence (nhiều unknown)
- BA: "5 / H" — 5 points, high confidence (requirements clear)
Khi có diverge lớn → discussion về nguồn uncertainty trước khi estimate lại.
3.2 Uncertainty Breakdown Discussion
Khi confidence thấp, hỏi team:
1. "Phần nào của story chúng ta chưa rõ?"
2. "Unknown nào cần resolve trước khi có thể estimate?"
3. "Cần Spike không, hay có thể estimate với buffer?"
4. Three-Point Estimation (PERT)
Khi uncertainty cao nhưng không muốn Spike, dùng 3-point:
O = Optimistic (everything goes right)
M = Most Likely (normal conditions)
P = Pessimistic (things go wrong)

E (Expected) = (O + 4M + P) / 6

Ví dụ: AI model integration story
O = 3 days (API works as documented)
M = 5 days (1 round of debugging)
P = 10 days (API has bugs, need workaround)

E = (3 + 4×5 + 10) / 6 = (3 + 20 + 10) / 6 = 5.5 days
Report to stakeholder: "Expected 5-6 days, range 3-10 days depending on API stability"
5. Communicating Uncertainty với Stakeholder
Nguyên tắc: Commit với phạm vi, không phải điểm chính xác
Tránh:
"Feature này xong trong sprint 3" (vô căn cứ)
Nên nói:
"Feature này có 3 phần:
1. UI implementation: High confidence, sprint 3 ✅
2. API integration: Medium confidence, sprint 3-4
3. Model accuracy validation: Low confidence — cần Spike sprint 3,
   estimate lại sau Spike"
Uncertainty Communication Template
## Feature Estimate: [Feature Name]

### Confident Scope (commit)
- [Component 1]: X points — clear requirements ✅
- [Component 2]: Y points — proven tech ✅

### Uncertain Scope (indicative)
- [Component 3]: ~Z points — pending data validation
- [Component 4]: Need Spike first (2 days timebox)

### Dependencies / Blockers
- [ ] Data pipeline from [team] needed by [date]
- [ ] Model threshold confirmed by [stakeholder]

### Recommended Approach
Sprint N: Spike + Confident scope
Sprint N+1: Uncertain scope (estimate after Spike)
6. Definition of Ready cho AI Stories
Story ready để estimate khi:
- Data dependency identified và confirmed available (or spike planned)
- AI/model approach confirmed (hoặc spike planned cho approach)
- Acceptance threshold agreed với stakeholder
- Fallback behavior defined
Kết luận
Estimation accuracy không quan trọng bằng estimation honesty. BA role trong AI estimation là structure uncertainty, propose Spike khi cần, và set realistic expectations với stakeholder — không phải ép ra con số chính xác giả.
Sprint velocity của AI team thường thấp hơn feature team truyền thống 20-30% vì Spike work. Build điều này vào capacity planning từ đầu.